Author: Wall Street News
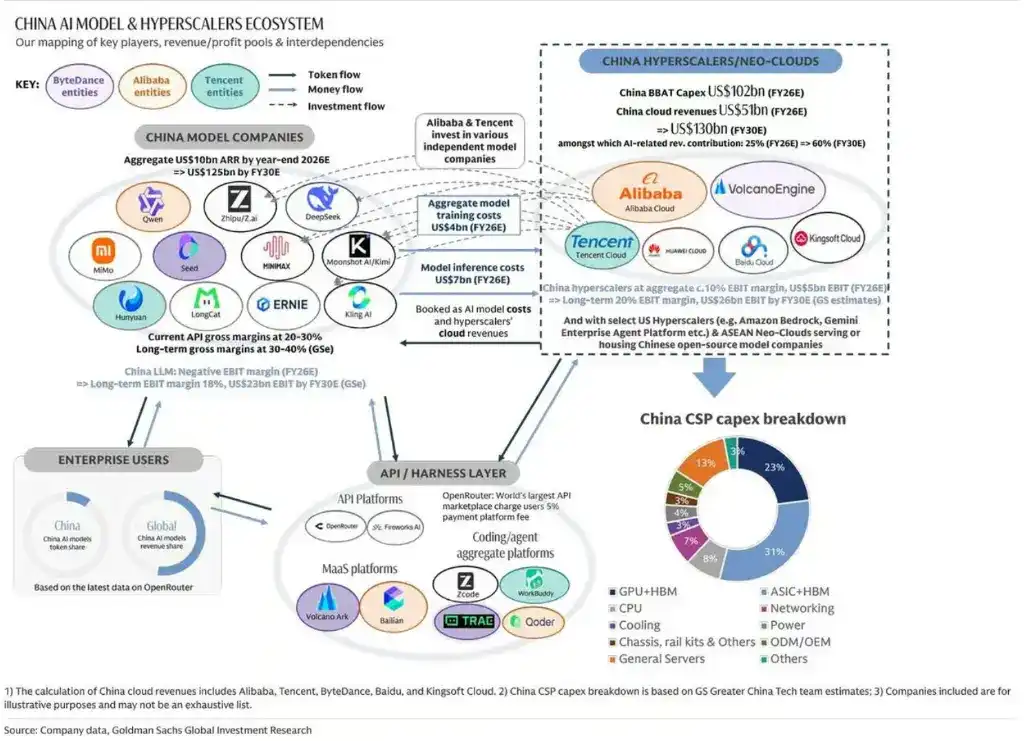
China's AI large models are standing at a historic inflection point. Goldman Sachs believes that the intelligence performance of China's open-source/open-weight large models is approaching the world's top proprietary models, with rapid adoption by domestic enterprises and global SMEs, thereby creating a data flywheel effect that will further drive model iteration and upgrades.
According to Chasing Wind Trading Desk, Goldman Sachs' latest report points out that this evolutionary trajectory can be summarized as 'from DeepSeek's cost-efficiency moment last year to Zhipu GLM's model intelligence moment this year.' A team led by Goldman Sachs analyst Ronald Keung systematically evaluates four core questions in this 50-page report: how Chinese AI models achieve high performance at low cost, why the open-source path is chosen and how to monetize it, where the core addressable market lies, and who will be the long-term winners.
In assessing the competitive landscape, Goldman Sachs introduced a "competitive positioning framework" based on pricing power, cost advantage, and financial strength, and concluded accordingly that in the foundational text model field, Zhipu (initiating coverage) and DeepSeek (unlisted) have the strongest positioning; in the multimodal field, ByteDance (unlisted) leads. Goldman Sachs simultaneously maintains its Buy ratings on MiniMax and Kuaishou.
Achieving More with Less, Efficiency Wins
China's large models can achieve performance close to their US counterparts at a far lower cost, with the core lying in the dual breakthrough of architectural innovation and parameter efficiency.
The Goldman Sachs report points out that the parameter scale of Chinese open-source models generally ranges from 200 billion to 1.6 trillion, only 2% to 10% of the world's top models, mainly due to restricted access to high-end computing power. Meanwhile, innovations like the Mixture of Experts (MoE) architecture and sparse attention mechanisms have reduced the actual activated parameters to only 3% to 5% of the total parameters, significantly lowering training and inference costs.
At the specific model level, DeepSeek V4 Pro has 1.6 trillion parameters, Zhipu GLM5.2 has 0.7 trillion, and MiniMax M3 has 0.4 trillion.
Goldman Sachs attributes the recent leap in coding capabilities of Chinese models to the synergistic effects of data filtering, reinforcement learning post-training, and other factors. On June 27, DeepSeek launched the speculative decoding framework DSpark, already deployed in the online services of V4-Flash and V4 Pro, which increases generation speed per user by 60% to 85% (V4-Flash) and 57% to 78% (V4 Pro) without changing model weights or output quality.
Meituan's release of LongCat 2.0 on June 30 is regarded by Goldman Sachs as a significant milestone in the self-sufficiency of China's AI infrastructure—it's China's first open-source 1.6 trillion parameter MoE model fully trained and deployed based on 50,000 domestic compute cards. Goldman Sachs believes this proves the feasibility of a localized hardware stack during the compute-intensive pre-training phase, holding profound significance for China's AI models to reduce reliance on foreign high-end chips.
A Bifurcating Market, the Strong Get Stronger
Goldman Sachs describes the Chinese AI model market as forming a "two-tier structure" and identifies two ARR-maximizing quadrants.
In the high-end market, top models represented by Zhipu GLM5.2 and Alibaba's Qwen3.7 Max are priced at about $1 per million tokens, which is 5 times that of low-end models, with estimated inference gross margins around 10% to 20%. In comparison, US top models are priced at $4 to $8 per million tokens; Chinese high-end models are only 10% to 25% of that price, yet can maintain positive gross margins thanks to a lower parameter activation ratio.
In the low-end market, models oriented for agent tasks are priced as low as $0.06 to $0.2 per million tokens, opening up markets among price-sensitive global SMEs and individual users. MiniMax derives 60% to 70% of its revenue from overseas. Notably, DeepSeek has announced the introduction of peak/off-peak pricing for the V4 series from mid-July, with peak rates twice the off-peak rate, with a blended pricing of about $0.35 (V4 Pro) and $0.12 (V4 Flash) per million tokens.
Goldman Sachs forecasts that Chinese AI model API and subscription revenue will grow from an estimated 35 billion yuan in 2026 to 879 billion yuan in 2030, corresponding to daily token consumption increasing from 35 trillion to 460 trillion, an approximately 25-fold increase.
Open-Source Strategy: Widespread Penetration, Monetization Path Awaits Upgrade
The Goldman Sachs report details the strategic logic behind the widespread adoption of open-source/open-weight routes by Chinese AI models and their monetization limitations.
The core advantages of the open-source strategy lie in deployment flexibility and community ecosystem. Alibaba's Qwen series, DeepSeek, Zhipu's GLM, and MiniMax's M3 all adopt open-source or open-weight methods, with ByteDance's Seed model being a major exception, following a fully closed-source proprietary route. The open-source model allows flexible deployment both within and outside mainland China and accelerates iteration through community feedback.
However, Goldman Sachs points out that the ARR numbers disclosed by open-source model companies likely significantly underestimate the actual deployment scale and revenue potential. Taking Zhipu as an example, its ARR target for the end of 2026 is $1 billion, but the actual global deployment volume of GLM5.2 will far exceed the token volume and revenue through Zhipu's own API channels—Alibaba Cloud's Bailian MaaS platform can directly host the open-source GLM5.2 model without paying Zhipu any fees.
Goldman Sachs expects the industry to gradually shift from pure open-source (MIT license, completely free) to an "open-weight + community license" model—where commercial use requires signing a revenue-sharing agreement with the model company. MiniMax's M series has pioneered this model. Goldman Sachs believes this transition will significantly improve the unit economics for AI model companies, as they can benefit from revenue-sharing agreements with platforms like AWS Bedrock and Alibaba Cloud Bailian without bearing the inference compute costs themselves.
From 'Token Maximization' to ROI Priority
Goldman Sachs characterizes international market expansion as the most important upside for Chinese AI models, especially in non-US markets.
Goldman Sachs' US research team estimates that by 2030, agent AI will drive a 24-fold increase in global token consumption to 12 quintillion tokens per month, with enterprise agents contributing a 55-fold growth and consumer agents contributing a 12-fold growth. In global (excluding China) markets, Chinese AI models have already achieved significant token share growth due to performance improvements and price advantages.
The Goldman Sachs report notes that the global enterprise AI usage paradigm is undergoing a fundamental shift from 'token maximization' to 'ROI priority'. The former prevailed from late 2025 to early 2026, where enterprises equated high token consumption with organizational productivity; the latter focuses more on clear task boundaries, daily active agent count, backend process automation, and actual output. Data from a Jellyfish AI engineering trends study shows that heavy AI users in enterprises consume 10 times the tokens but only increase output by 2 times.
At the channel level, Alphabet's Gemini Enterprise Agent Platform and Amazon's AWS Bedrock already offer hosting services for Chinese AI models like DeepSeek, MiniMax, Moonshot, GLM, and Qwen. According to the Wall Street Journal, Microsoft's CEO recently stated that Microsoft is considering hosting a version of DeepSeek in Copilot as an optional low-cost model, emphasizing that if DeepSeek is hosted, the model would run within Microsoft's cloud ecosystem, ensuring customer data remains within Azure.
Who Are the Long-Term Winners?
Goldman Sachs constructed a three-dimensional competitive positioning framework to evaluate each player's long-term winning probability with quantitative metrics, with the core formula being: ARR scale × gross margin advantage + financial strength.
The Pricing Power dimension examines release speed (compared to previous generation and same-level models), LMArena Arena score (based on large-scale blind user evaluations), and blended pricing level per million tokens.
The Cost Advantage dimension examines throughput (tokens per second), cache hit rate, parameter activation ratio, and inference gross margin. The Financial Strength dimension examines cash on hand, net cash as a percentage of total assets, and valuation multiples.
In the field of foundational text models, Goldman Sachs identifies Zhipu (initiating coverage, Neutral rating, target valuation $110 billion) and DeepSeek (unlisted) as having the strongest positioning, with both excelling in pricing power and cost advantage. The overall implied valuation of independent AI model companies exceeds $200 billion.
In the field of multimodal/video generation, ByteDance leads with Seedance. According to LatePost and 36Kr reports, Seedance has a gross margin as high as 70%, with an ARR run rate already exceeding $2 billion. Kuaishou's Kling and MiniMax's Hailuo/upcoming H3 models are also favored by Goldman Sachs, expected to benefit from functional breakthroughs in video generation and LLM integration and healthy pricing due to tight supply in the second half of 2026.
Goldman Sachs maintains a Buy rating on MiniMax with a target price of HK$860, citing its M3 model being in the ARR-maximizing quadrant of high token volume and attractive pricing, and its current valuation being only 13 times its ARR at the end of 2026, showing a significant discount compared to the valuation multiples of Chinese and global peers, with risk-reward skewed to the upside.