A PPT Dismissed as 'Nonsense' by MIT Professors 5 Years Ago Predicted the Core Ideas of OpenAI o1 and o3

marsbit2026-08-17 tarihinde yayınlandı2026-08-17 tarihinde güncellendi

Özet

In 2020, AI researcher Giambattista Parascandolo presented his vision for neural network reasoning at an MIT faculty interview, only to have the committee dismiss the direction as "nonsense." He later posted the details online. His talk centered on enabling artificial neural networks to generalize and plan beyond their training data, closer to human capabilities. Parascandolo proposed three key research directions. First was "open-ended reasoning," where models could dedicate more computation time to harder problems, continuously refining answers—a precursor to today's compute-adaptive reasoning models. He noted that simply adding steps (e.g., in RNNs) wasn't enough without learning to use them effectively. Second, he advocated using language as a medium for reasoning within reinforcement learning. By leveraging the world knowledge in models like GPT, agents could better describe environments, decompose tasks, and plan—foreshadowing concepts like chain-of-thought and agent workflows. His third direction involved giving AI systems the ability to manipulate their own learning process: resetting to past states, creating counterfactual scenarios, and even editing their own activations or weights to facilitate deliberate practice. Parascandolo, who earned his PhD focusing on out-of-distribution generalization and had internships at Google X and DeepMind, joined OpenAI in 2021. He contributed to GPT-4 and later became integral to the foundational research behind the reasoning mod...

The AI community never runs short of gossip.

This time, the protagonist is Giambattista Parascandolo, an important researcher in the direction of reasoning models at OpenAI.
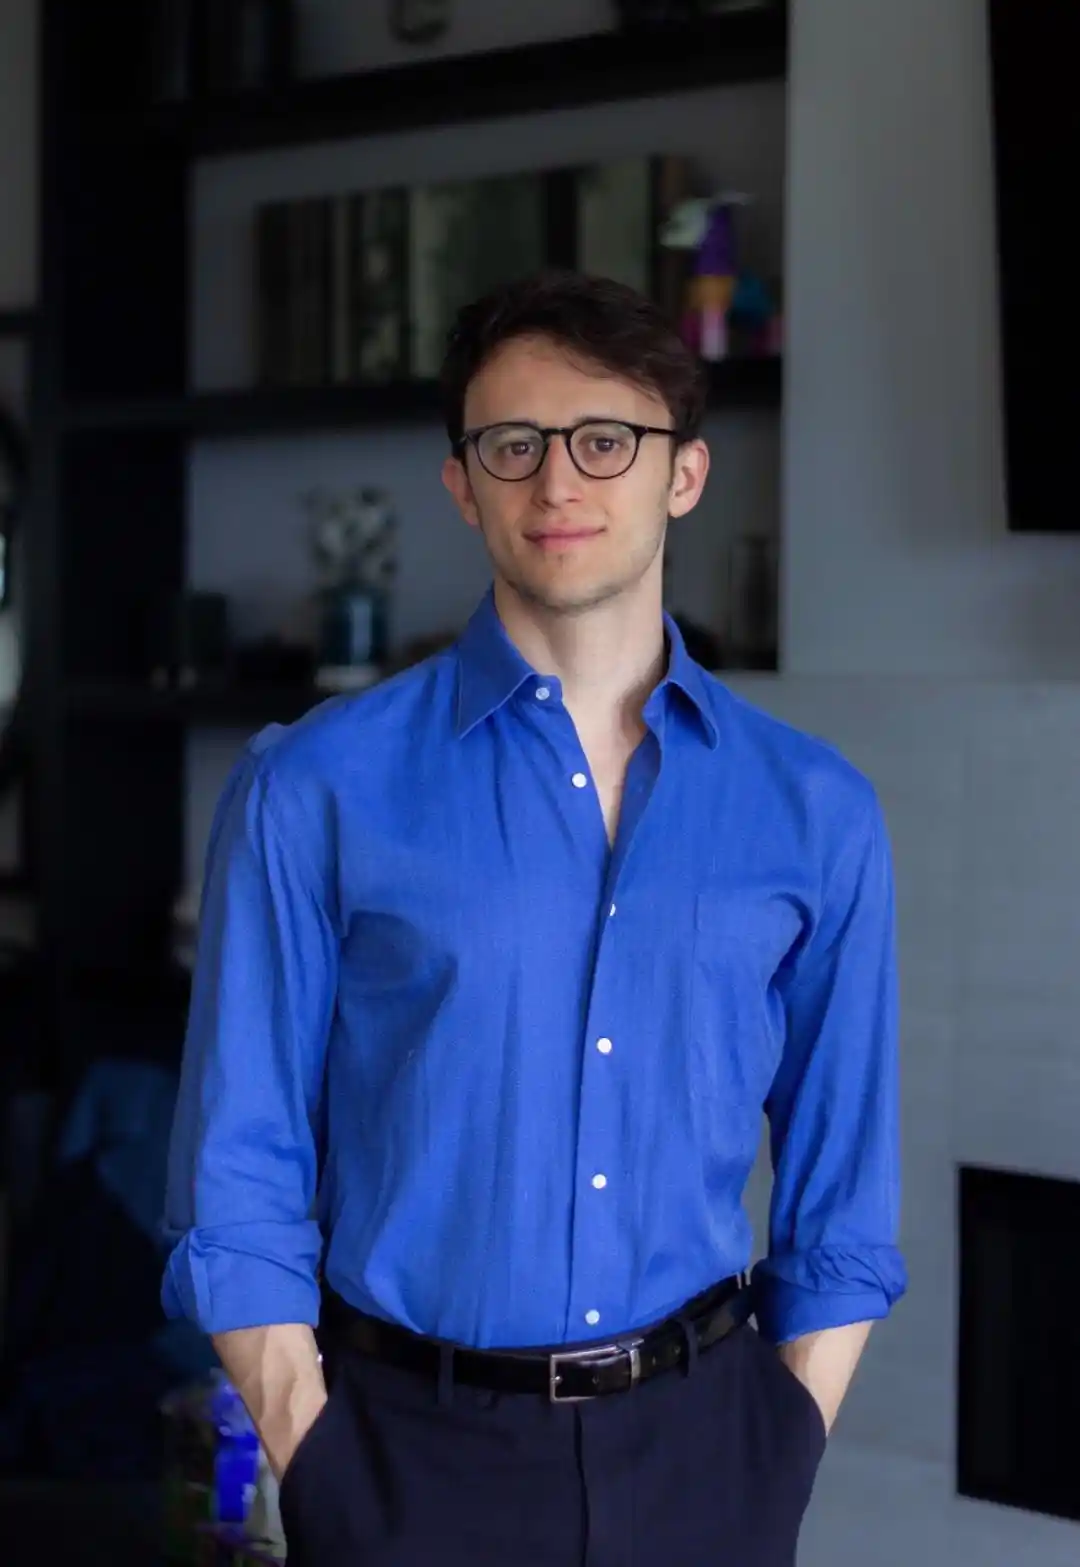
In 2020, he went to MIT to interview for a professorship, giving a presentation on using GPT for reasoning. As a result, most professors on the interview committee dismissed this direction as "nonsense."
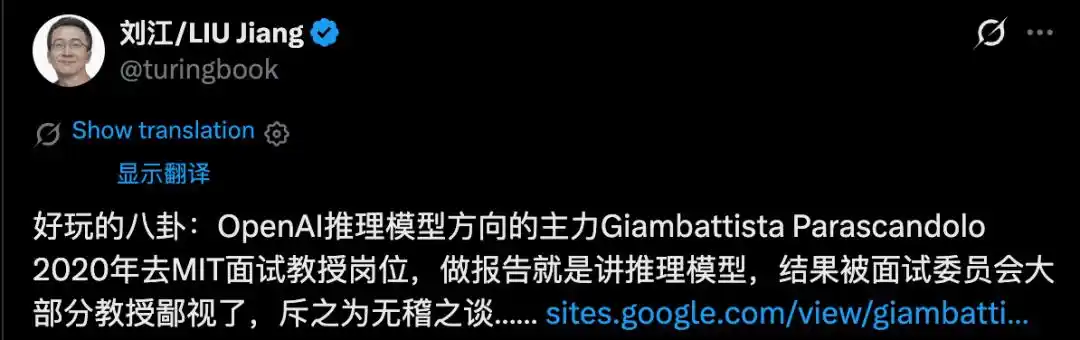
https://x.com/turingbook/status/2084003612687249836?s=20

This guy went all out, directly putting this experience on his personal homepage and attaching the description and slide link from that year's presentation.
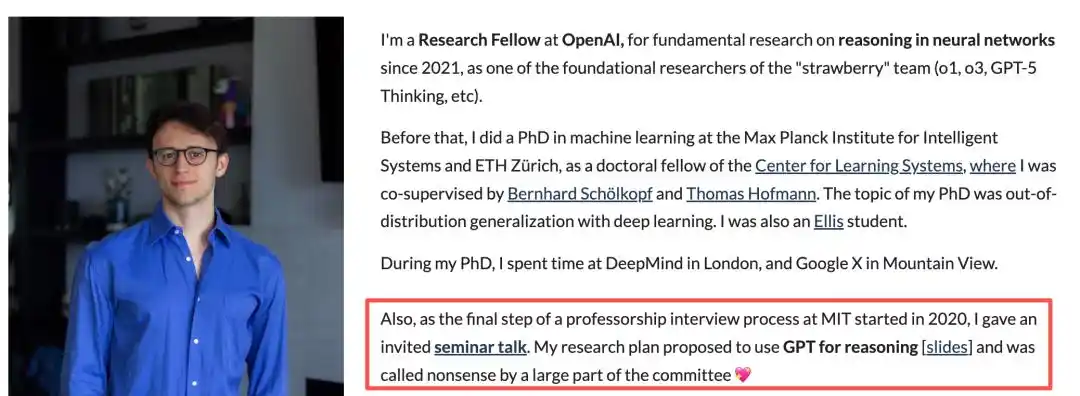
https://sites.google.com/view/giambattista-parascandolo/home

What was in that report dismissed as "nonsense"?

The MIT website shows that the topic of this presentation was how to enable artificial neural networks to break through the training distribution and achieve generalization and planning capabilities closer to humans.
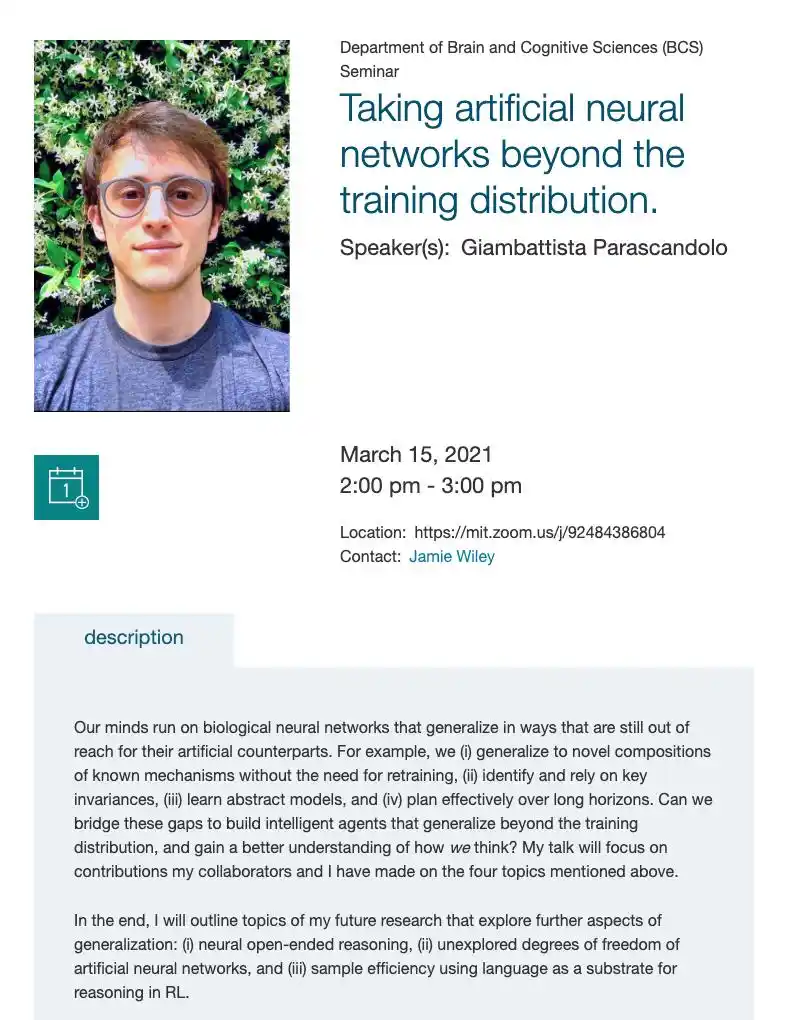
Parascandolo believed that humans can recombine existing knowledge, identify key invariants, build abstract models, and perform long-horizon planning. Artificial neural networks still have much room for improvement in these aspects.

At the end of the presentation, he proposed three future research directions: open-ended reasoning in neural networks, unexplored degrees of freedom in artificial neural networks, and using language as a reasoning substrate in reinforcement learning to improve sample efficiency.

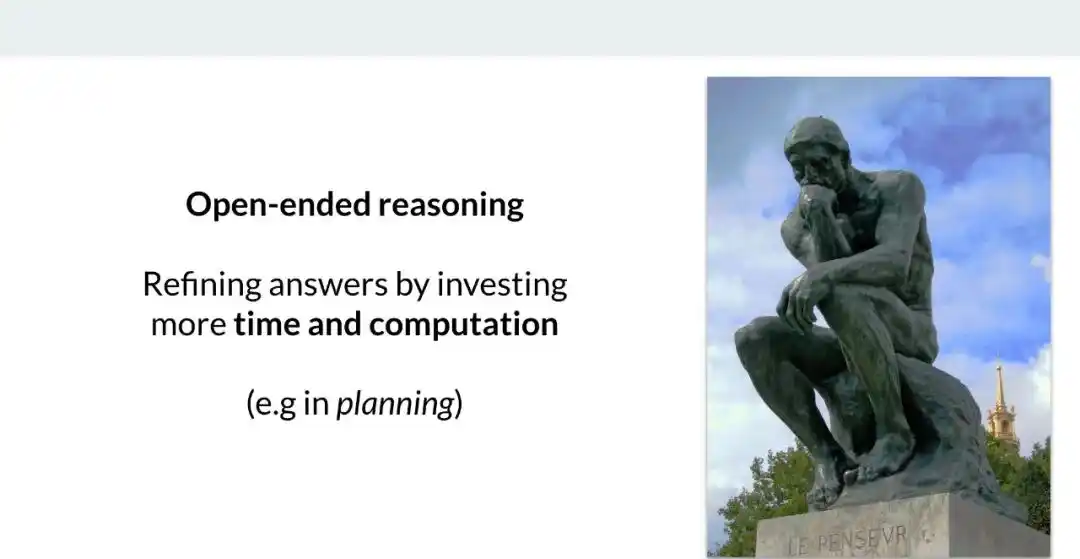
The most crucial concept among these was "open-ended reasoning."

Parascandolo defined it as: the model can invest more time and computation to continuously refine its answer. The harder the problem, the more steps the model should think, and the extra computation should translate into better results.

This already sounds very much like today's inference-time compute scaling.
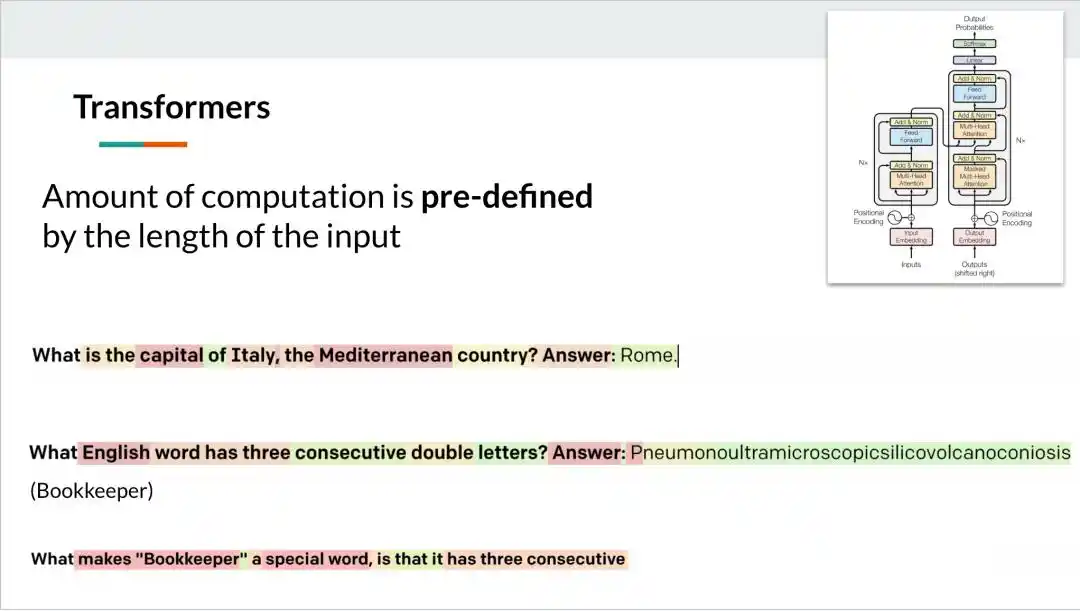
At that time, standard Transformers had a fixed network depth, and the forward compute each token experienced was basically predetermined. However, problem difficulty has no stable relationship with input length. A problem could be very long but have a simple answer. Another problem might be a single sentence but require multiple rounds of decomposition and verification.
RNNs seemed more suitable for such tasks. They could run repeatedly and theoretically obtain arbitrary amounts of thinking time. However, the curve Parascandolo showed in his PPT indicated that RNNs typically performed best only around the number of reasoning steps they had seen during training. Continuing to increase the number of iterations could actually decrease accuracy.
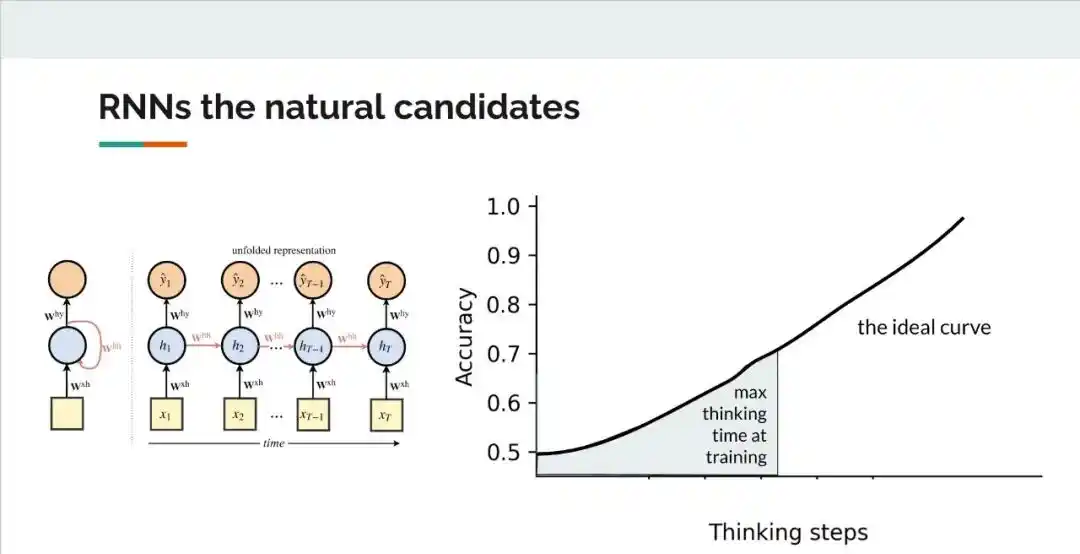
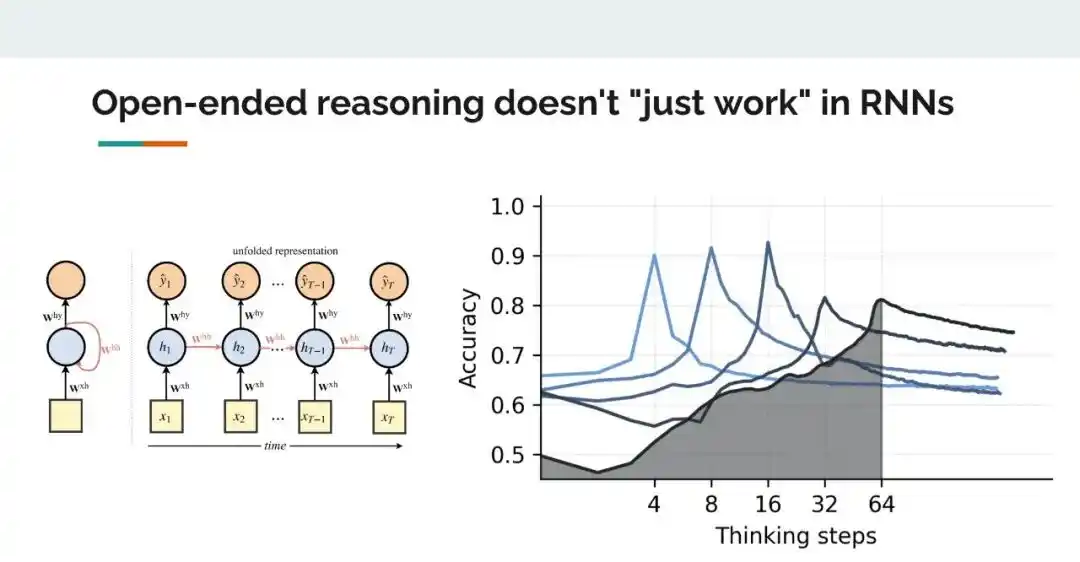
This meant that increasing compute was only the first step; the model also needed to learn how to utilize this compute.

At the time, the most effective multi-step planning heavily relied on model-predictive control and Monte Carlo tree search. Neural networks were responsible for predicting the environment or evaluating value, while external search algorithms were responsible for expanding future paths. Parascandolo hoped to further integrate long-horizon reasoning capabilities into neural networks themselves.
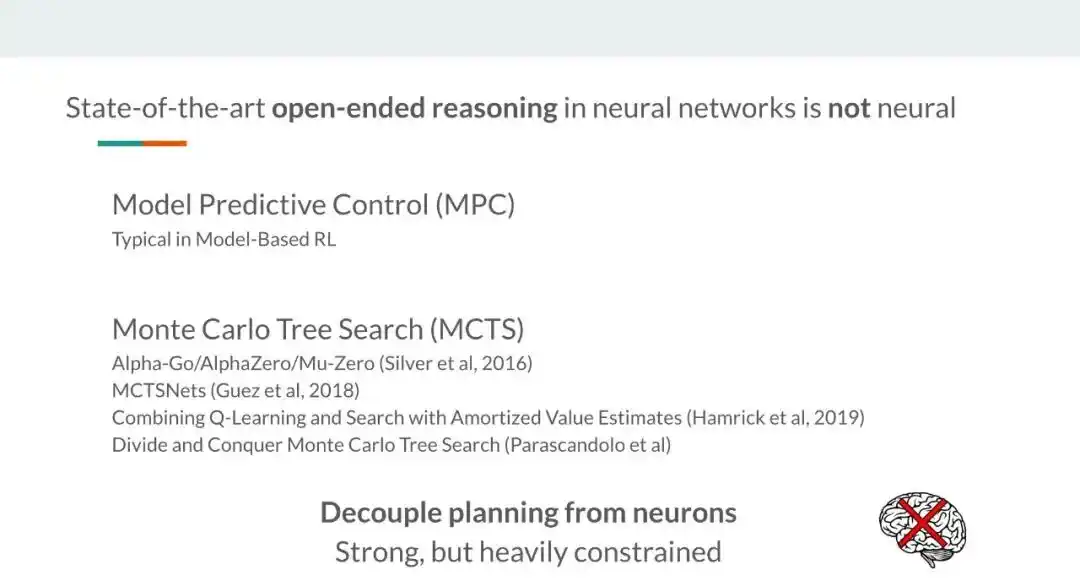
His second vision was to make language the substrate for reasoning.
Parascandolo used the classic game *Montezuma's Revenge* as an example. A reinforcement learning Agent trained from scratch needed to try a huge number of state and action combinations. Many correct actions themselves were not complex; what the Agent truly lacked was a judgment of "which behaviors are more reasonable."
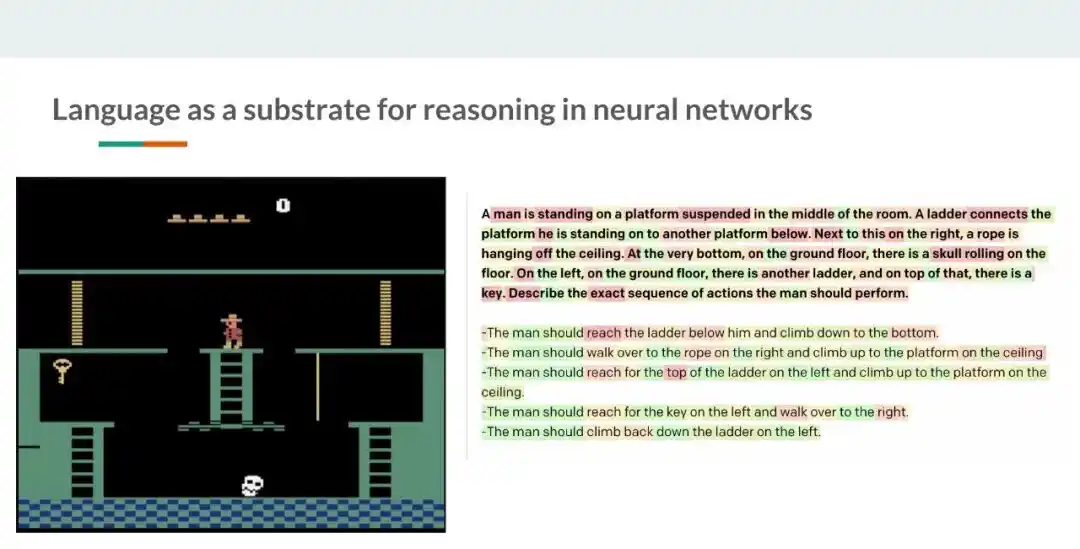
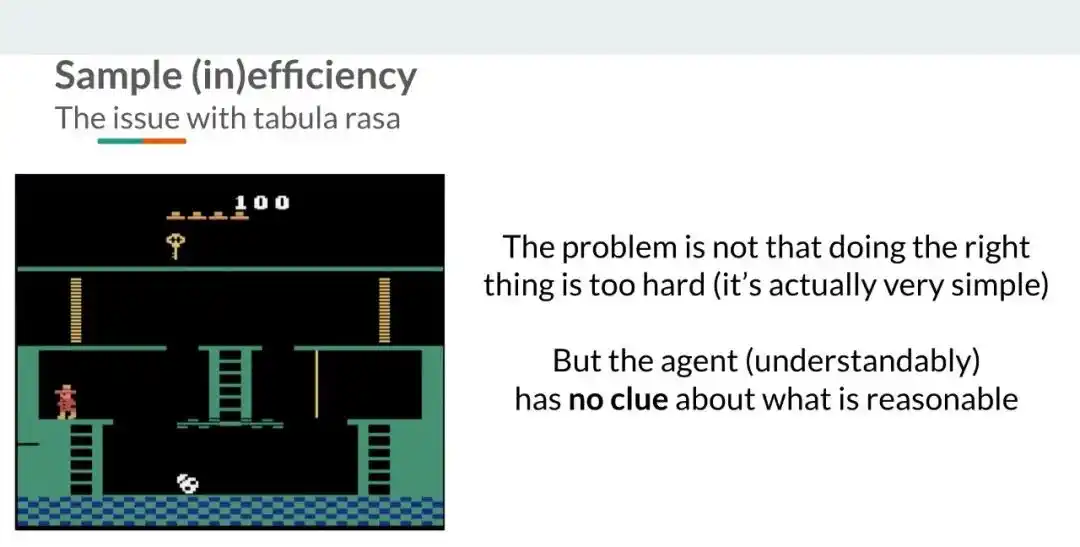
GPT had already absorbed vast amounts of world knowledge from text. Language could help models describe environments, understand goals, decompose tasks, and generate high-level plans, also significantly narrowing the search space.

Today, this line of thinking easily brings to mind chain-of-thought, language planning, and Agent workflows.

The third direction Parascandolo proposed was that AI systems could reset tasks, return to any remembered state, construct counterfactual scenarios, and even adjust time, gravity, and observations within the simulator. Systems could also directly read, copy, and modify their own activation values and neural network weights.
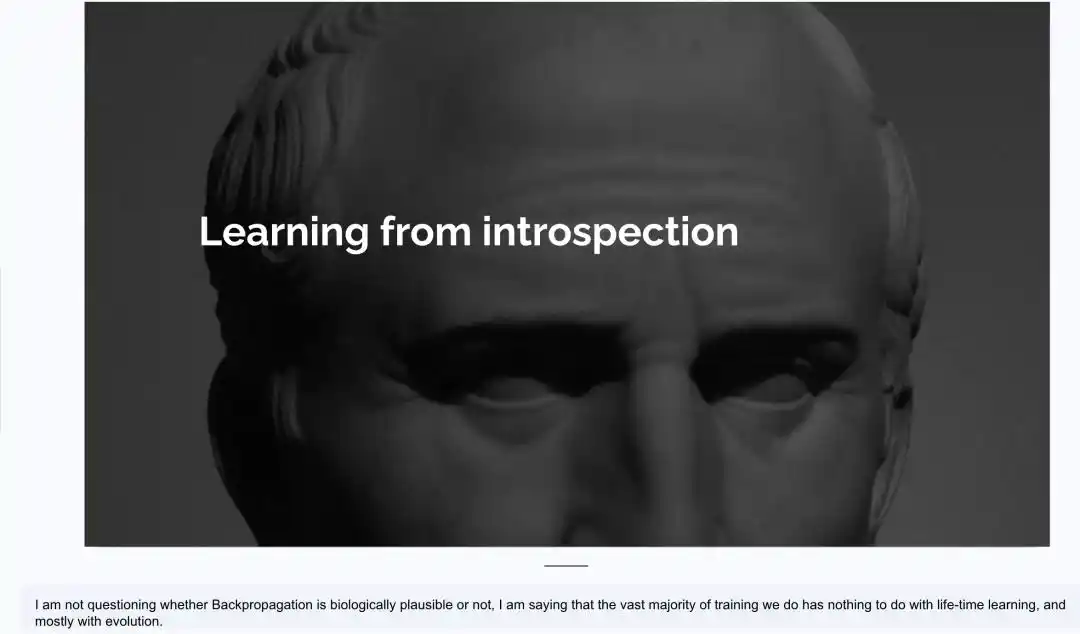
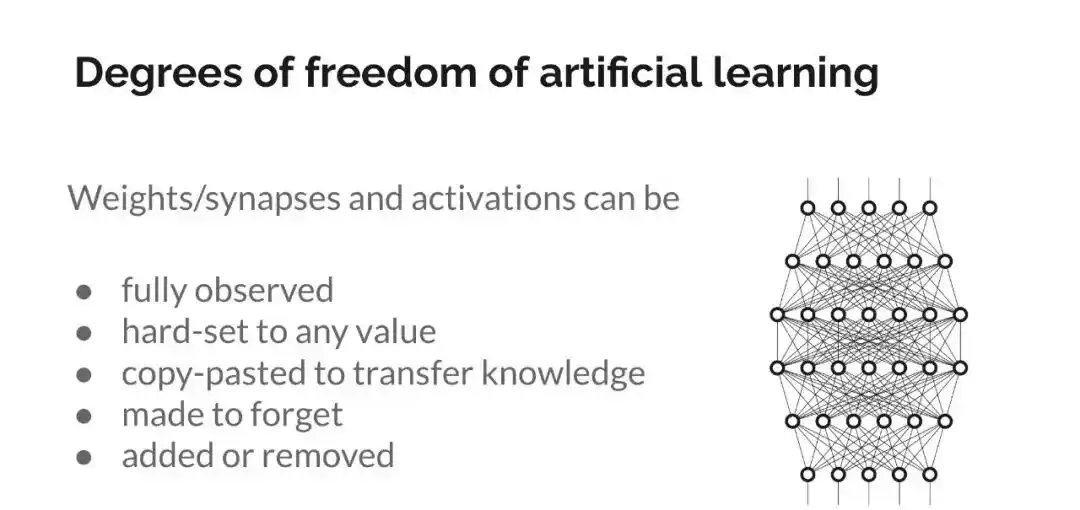
This was equivalent to incorporating the learning process itself into the Agent's operational space. It could engage in deliberate practice, generate special training scenarios, transfer existing knowledge, and relearn from failure trajectories.
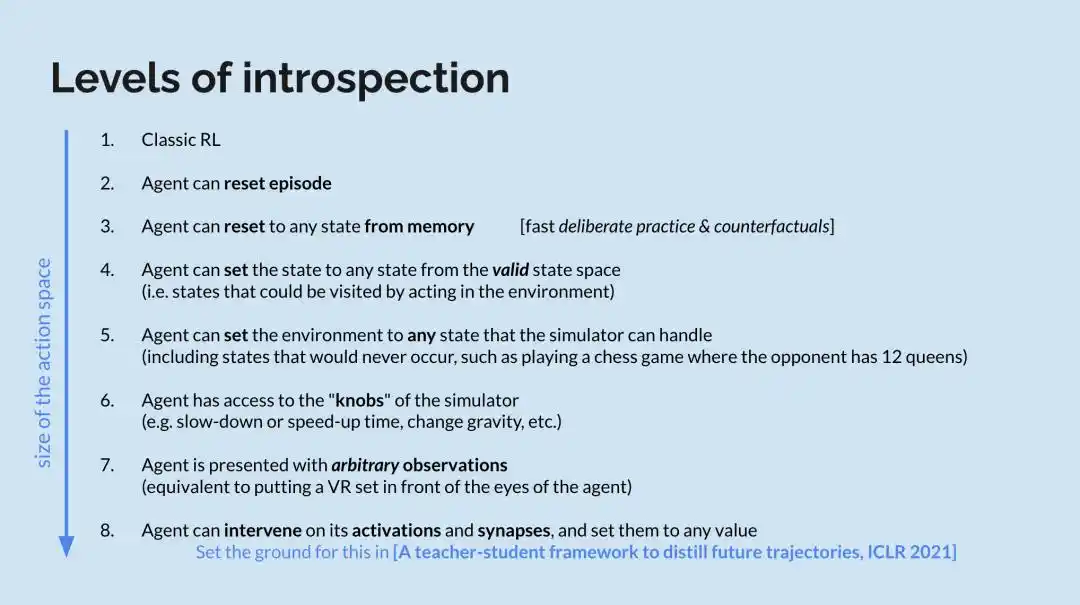
The PPT from five years ago almost wrote today's reasoning model roadmap.

We also dug up a blog post he wrote in June 2021, titled "Backprop, Evolution, and the ‘Two Dogs’ Fallacy."
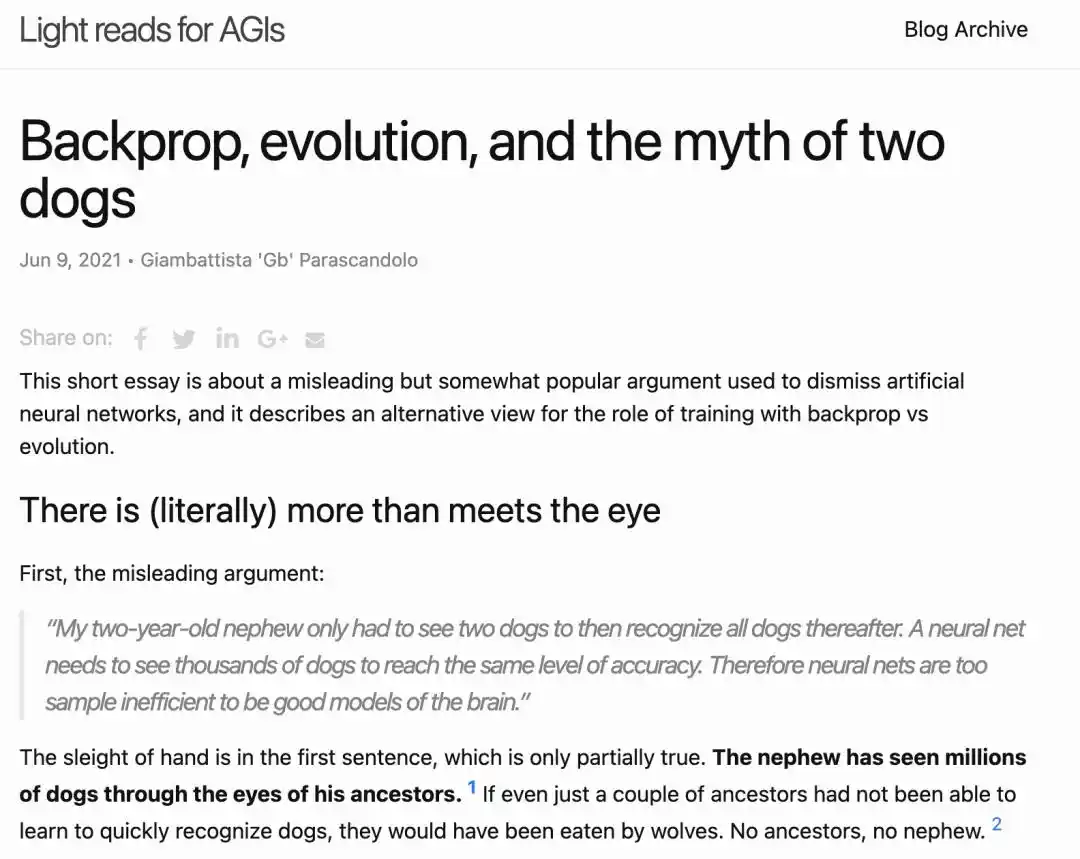
This blog post mainly refuted the view that "neural networks need massive amounts of data, therefore they are unlike the human brain."

Parascandolo argued that the fact humans can learn to recognize dogs after seeing just a few does not mean there was no prior accumulation of experience. Long evolution has already condensed the experiences of ancestors interacting with the world into the structure and inductive biases of the human brain.

From this perspective, the large-scale pre-training of neural networks can be analogized to biological evolution, while model fine-tuning and in-context learning are closer to the learning an individual does in a lifetime. GPT-3 has read far more text than any individual, but its pre-training served to compress massive experience and shape efficient learning capabilities. Therefore, one should not directly compare the model's entire pre-training data with the small number of learning samples an individual receives after birth.

This understanding also implies that continuing to scale data and compute could still bring significant improvements. He was drawing an analogy about the roles they play, not claiming that gradient descent and biological evolution share the same specific mechanisms.

What's this guy's background?

This guy is quite low-key. His latest post on X dates back to November 2024, when he was recruiting two Research Engineers (RE) and Software Engineers (SWE) for o1.
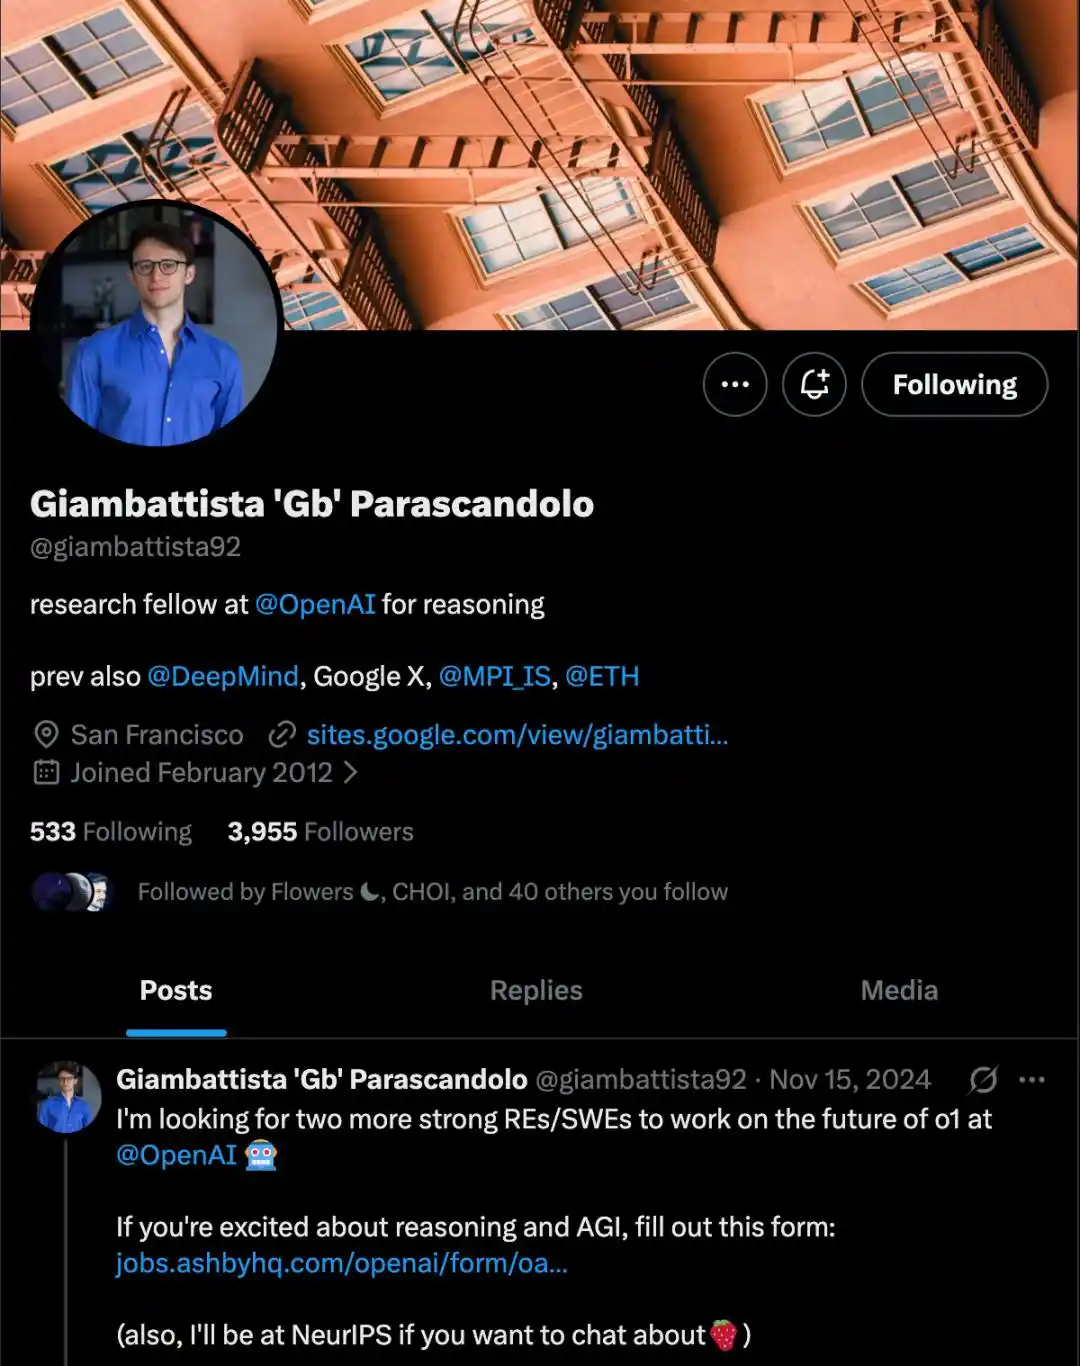
According to his personal homepage, Parascandolo's research experience has always revolved around generalization, planning, and reasoning.

In 2017, he began his Ph.D. at the Max Planck Institute for Intelligent Systems and ETH Zurich, supervised by Bernhard Schölkopf and Thomas Hofmann. His doctoral research focused on OOD generalization in deep learning.

During his Ph.D., he did internships at Google X in Mountain View and DeepMind in London, participating in research on automated design on ultra-large-scale simulators at the former, and research on divide-and-conquer Monte Carlo tree search at the latter.

After graduating with his Ph.D. in September 2021, he directly joined OpenAI. Initially, he entered the reinforcement learning team led by John Schulman, then moved to the algorithms team where Mark Chen was, and later joined the 🍓 (strawberry) team led by Jerry Tworek. The strawberry team was the internal codename for the o1 project.
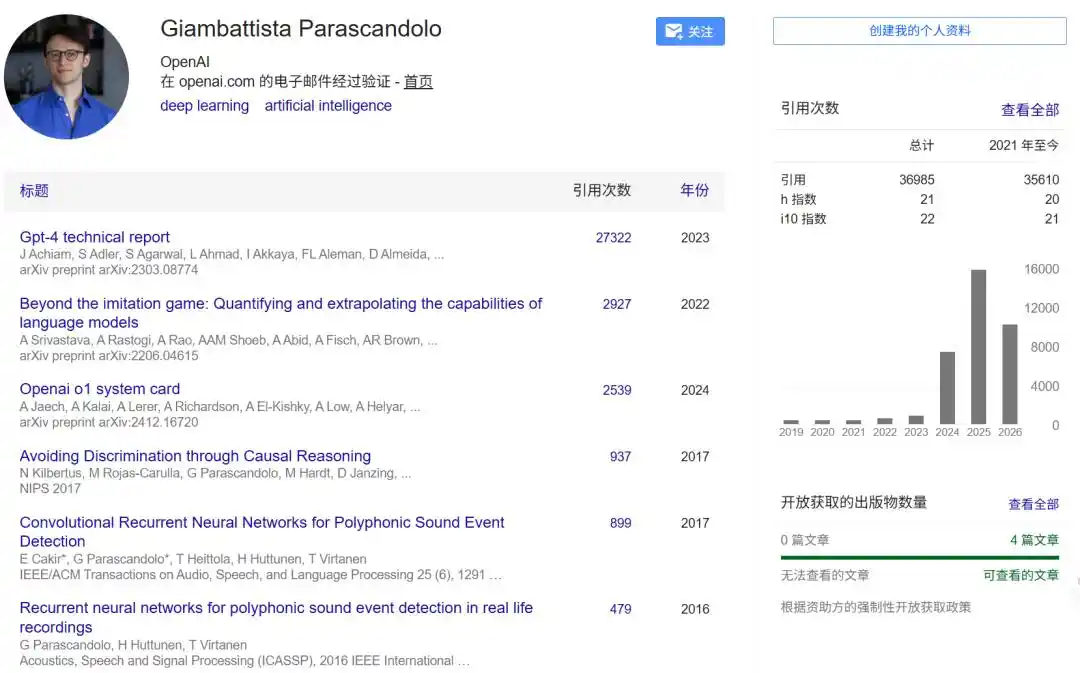
In 2023, he participated in GPT-4 development and formed a new team continuing reasoning research. Later, he participated in the foundational research for OpenAI o1 and o3, promoting the scaling of reward modeling, environment construction, and general reasoning algorithms. Part of the algorithm description is still covered by black blocks on his page.
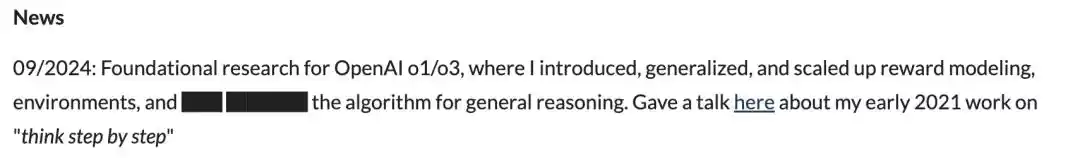
Parascandolo didn't get the MIT professorship from that 2020 interview; he went to OpenAI instead.

Four years later, he helped build o1.

Life is always full of delightful surprises.

References:

https://x.com/giambattista92

https://sites.google.com/view/giambattista-parascandolo/home

https://gibipara92.github.io/2021/06/09/backprop-evolution-two-dogs.html

https://docs.google.com/presentation/d/1edd2GkAP31wNygaev3DO8gE1t2lgsx1z8TeVpBKqlYA/edit?slide=id.gc772610149_0_179#slide=id.gc772610149_0_179

This article is from the WeChat public account "Almost Human" (ID: almosthuman2014), author: Yang Wen

Trend Kriptolar

İlgili Sorular

QWhat were the three key research directions proposed by Giambattista Parascandolo in his MIT job talk?

AThe three key research directions were: 1) Open-ended reasoning in neural networks (models allocating more time/computation for harder problems), 2) Using language as a substrate for reasoning in reinforcement learning to improve sample efficiency, and 3) Allowing AI systems to manipulate their own internal states (like activations and weights) to conduct deliberate practice and counterfactual learning.

QHow does Parascandolo's concept of 'open-ended reasoning' relate to modern AI like OpenAI's o1?

AParascandolo's 'open-ended reasoning' concept, where models spend more time and computation to refine answers for harder problems, directly foreshadows the core idea of 'reasoning-time compute scaling' used in modern AI systems like OpenAI's o1 and o3. These models dynamically allocate computational effort based on problem difficulty.

QWhy did Parascandolo argue that comparing a neural network's pre-training data to a human's lifelong learning is misleading?

AParascandolo argued that large-scale pre-training is analogous to biological evolution, compressing vast ancestral experience into the model's structure and inductive biases. Fine-tuning and in-context learning are more akin to an individual's lifetime learning. Therefore, comparing total pre-training data to a human's post-birth learning samples is an apples-to-oranges comparison.

QWhat role did Giambattista Parascandolo play at OpenAI leading up to the development of o1 and o3?

AAt OpenAI, Parascandolo initially worked in the reinforcement learning team, later joined the algorithms team, and was part of the 'Strawberry' team (the internal codename for the o1 project). He contributed to GPT-4, formed a new team focused on reasoning research, and worked on the foundational research for o1 and o3, specifically on reward modeling, environment construction, and scaling general reasoning algorithms.

QWhat was the main point of Parascandolo's blog post 'Backprop, Evolution and the "Two Dogs" Fallacy'?

AThe main point was to challenge the argument that neural networks are unlike the human brain because they require massive data. He posited that human ability to learn from few examples (like recognizing dogs) is built upon evolutionary history, just as a neural network's pre-training compresses vast experience. Thus, pre-training is analogous to evolution, not individual learning, justifying the value of scaling data and compute.

İlgili Okumalar

"20CM" Limit Up: Another Star Secondary New Stock on the STAR Market?

On September 14th, the STAR Market's recently listed stock, Gaokai Technology, surged and hit the 20% daily limit, reaching a new all-time high of 324.41 yuan. The stock opened slightly higher and quickly rose to the limit-up price, closing with a full 20% gain. Its turnover reached approximately 1.128 billion yuan. Gaokai Technology went public on August 25, 2026, with an IPO price of 61.36 yuan. Its first-day closing price of 235.00 yuan represented a massive 282.99% surge from the IPO price. Following the recent 20% rise, the stock has gained about 4.29 times relative to its IPO price. The company, Jiangsu Gaokai Precision Fluid Technology Co., Ltd., is a national-level specialized and sophisticated "Little Giant" enterprise. It is a leader in China's precision fluid control sector, focusing on R&D, production, and sales of key control components. Its core products include flow control, dispensing/packaging, and precision coating systems, serving industries such as semiconductors, consumer electronics, and new energy. Financially, Gaokai has shown rapid growth. From 2023 to 2025, its operating revenue increased from 226 million yuan to 511 million yuan, with net profit attributable to parent shareholders rising sharply. In the first half of 2026, revenue grew 35.46% year-on-year to 327 million yuan, while net profit surged 95.07% to 106 million yuan. The stock's strong performance reflects market interest in semiconductor supply chain components and import substitution themes, as well as pricing for the growth potential of new listings. However, with a high trailing P/E ratio of approximately 175.79 and a relatively short trading history, investors should be mindful of potential volatility risks.

marsbit26 dk önce

"20CM" Limit Up: Another Star Secondary New Stock on the STAR Market?

marsbit26 dk önce

The Essence of the Engels’ Pause is 'Social Sarcopenic Obesity'

The article argues that the concept of "Engels' Pause"—a historical period during the British Industrial Revolution where wages stagnated despite productivity gains—is experiencing a modern resurgence with AI and automation. However, the author contends the core issue is not merely a problem of wealth distribution (a "cake-sharing" problem), but a deeper systemic ailment termed "social sarcopenic obesity." This condition describes an economy that gains "fat"—measured as GDP, profits, and capital stock—while losing "muscle," which is the vitality of society itself, including community organization, collective action, social trust, and individual agency. Key mechanisms causing this muscle atrophy include administrative overreach, market and algorithmic substitution for human interaction, and a narrative that workers are replaceable by machines, which undermines their bargaining power. The author warns against the Western path of addressing wage-productivity decoupling primarily through redistributive welfare ("blood transfusion"), which treats symptoms but allows social muscles to atrophy further, leading to issues like low fertility and political polarization ("social atrophy trap"). China, the article states, is institutionally committed to avoiding the original "Engels' Pause" through policies like "two synchronizations" (aligning income with economic growth and labor remuneration with productivity). Its real challenge is to avoid the subsequent Western trap and forge a third path: fostering social vitality ("muscle growth") alongside economic development. This requires shifting social policy from providing a safety net ("transfusion") to "investing in people" ("protein") and, crucially, to enabling social "weight-bearing"—empowering communities, labor organizations, and individuals. The prescription is "economic weight loss, social muscle gain." Concrete proposals include making "two synchronizations" a hard policy constraint, conducting "social impact assessments" for major industrial policies, and promoting initiatives where "funding follows organization," such as community-based childcare and eldercare. Other measures involve integrating labor into profit-sharing structures, fostering collective bargaining in the platform economy, leveraging public computing power to prevent monopoly "rents," directing AI to augment (not replace) care work, and strengthening social muscles at the county level. The goal is to build an economy with high order and high vitality, preventing growth from consuming the very social foundations that sustain it.

marsbit31 dk önce

The Essence of the Engels’ Pause is 'Social Sarcopenic Obesity'

marsbit31 dk önce

Fed Decision Window, BTC & HYPE Chan Theory Structure and Trading Strategy Analysis | Guest Analysis

This week's focus is on the Federal Reserve's interest rate decision, expected to heighten short-term market volatility. Technically, Bitcoin's rebound from July lows has entered a phase of range-bound consolidation and testing of key levels. Price action is wrestling around the critical 364-day moving average, indicating a tug-of-war between bulls and bears. **Bitcoin (BTC) Analysis:** The primary bullish development is BTC reclaiming the 182-day moving average and testing the 364-day moving average, a key "bull/bear" demarcation line after ~300 days. Price is currently consolidating within a 75,500–82,850 USD range, supported by the 30-day MA and pressured by the 364-day MA. Two main scenarios are outlined for the Fed decision window: 1. **Pre-announcement Rally:** A bounce leading into the event, potentially breaking resistance temporarily, but with limited upside and risk of a post-news "bull trap" pullback. 2. **Pre-announcement Consolidation/Decline:** Sideways or weak action near support, followed by a potential sharp post-news sell-off. A downside spike could present a buying opportunity for a rebound targeting 82,500 USD. **BTC Trading Strategy:** Adopt a wait-and-see approach early week. Post-Fed, implement short-term strategies (using 30% capital) based on price action at key levels: * **Plan A (Long):** Consider a long position if price stabilizes above the second major support zone (67,300–69,100 USD) with confirming signals. * **Plan B (Short):** Consider a short position if price rallies to the 82,850–84,500 USD resistance zone and shows signs of rejection. Mid-term strategy remains on hold, awaiting a confirmed pullback to the breakout level of the "long/short channel." **Hype (HYPE) Analysis:** HYPE's rally from early August appears to have concluded, forming a clear momentum divergence (bearish) upon reaching its all-time high. Price has broken below key $80 support, confirming a shift to a corrective phase. **HYPE Trading Strategy:** Previous long positions from 50–52 USD were exited near 80 USD. Given the Fed event, the recommendation is to remain in cash and monitor. Key will be the strength of any rebound from the 76–77 USD support zone to gauge the correction's duration. **General Risk Management:** Immediately set a stop-loss on entry. Trail the stop to breakeven at +1% profit, then lock in profits by moving the stop-loss incrementally with each further 1% gain. *Disclaimer: Market conditions change rapidly. This analysis is for informational purposes only and not investment advice. Trading carries significant risk.*

marsbit1 saat önce

Fed Decision Window, BTC & HYPE Chan Theory Structure and Trading Strategy Analysis | Guest Analysis

marsbit1 saat önce

İşlemler

Spot

Popüler Makaleler

CORE Nasıl Satın Alınır

HTX.com’a hoş geldiniz! CORE (CORE) satın alma işlemlerini basit ve kullanışlı bir hâle getirdik. Adım adım açıkladığımız rehberimizi takip ederek kripto yolculuğunuza başlayın. 1. Adım: HTX Hesabınızı OluşturunHTX'te ücretsiz bir hesap açmak için e-posta adresinizi veya telefon numaranızı kullanın. Sorunsuzca kaydolun ve tüm özelliklerin kilidini açın. Hesabımı Aç2. Adım: Kripto Satın Al Bölümüne Gidin ve Ödeme Yönteminizi SeçinKredi/Banka Kartı: Visa veya Mastercard'ınızı kullanarak anında CORE (CORE) satın alın.Bakiye: Sorunsuz bir şekilde işlem yapmak için HTX hesap bakiyenizdeki fonları kullanın.Üçüncü Taraflar: Kullanımı kolaylaştırmak için Google Pay ve Apple Pay gibi popüler ödeme yöntemlerini ekledik.P2P: HTX'teki diğer kullanıcılarla doğrudan işlem yapın.Borsa Dışı (OTC): Yatırımcılar için kişiye özel hizmetler ve rekabetçi döviz kurları sunuyoruz.3. Adım: CORE (CORE) Varlıklarınızı SaklayınCORE (CORE) satın aldıktan sonra HTX hesabınızda saklayın. Alternatif olarak, blok zinciri transferi yoluyla başka bir yere gönderebilir veya diğer kripto para birimlerini takas etmek için kullanabilirsiniz.4. Adım: CORE (CORE) Varlıklarınızla İşlem YapınHTX'in spot piyasasında CORE (CORE) ile kolayca işlemler yapın.Hesabınıza erişin, işlem çiftinizi seçin, işlemlerinizi gerçekleştirin ve gerçek zamanlı olarak izleyin. Hem yeni başlayanlar hem de deneyimli yatırımcılar için kullanıcı dostu bir deneyim sunuyoruz.

543 Toplam GörüntülenmeYayınlanma 2024.12.13Güncellenme 2026.06.02

CORE Nasıl Satın Alınır

Tartışmalar

HTX Topluluğuna hoş geldiniz. Burada, en son platform gelişmeleri hakkında bilgi sahibi olabilir ve profesyonel piyasa görüşlerine erişebilirsiniz. Kullanıcıların CORE (CORE) fiyatı hakkındaki görüşleri aşağıda sunulmaktadır.

活动图片