Programmers Worldwide Are Wasting Money on Anthropic! The Company Can't Stand It Anymore

marsbitPublished on 2026-08-16Last updated on 2026-08-16

Abstract

Anthropic recently published guidelines to help developers using Claude Code reduce unnecessary token costs. The key recommendations include: 1) Clear (/clear) conversations after completing a task to avoid carrying irrelevant file reads and command outputs into the next task. 2) Set the model and reasoning effort level at the start of a session, as switching mid-session invalidates the prompt cache, requiring a full-price recalculation of the entire dialog history. 3) Attach files using @ references instead of typing paths manually to avoid extra tool calls and searches that bloat the context. 4) Add quiet flags to verbose commands (e.g., in CLAUDE.md) to minimize lengthy output in the dialog history. 5) Use /compact while the session cache is still warm (before breaks) to compress the dialog at one-tenth the cost. 6) Offload large-output tasks to a sub-agent, which runs in an isolated context and only returns conclusions, preventing intermediate outputs from polluting the main dialog. The article explains token pricing: input tokens (prefill) are processed in parallel, while output tokens (decode) are generated serially, making output tokens five times more expensive. Caching is crucial for savings—if a request's prefix (system prompt, CLAUDE.md, dialog history) matches the previous one byte-for-byte, reading it costs only 10% of the standard input price. However, cache invalidation occurs when changing models, effort levels, fast mode, compressing dialogs, after cache exp...

Just now, Anthropic published a blog post.

The core message is: Everyone, stop burning tokens for no reason, we can't stand watching anymore!
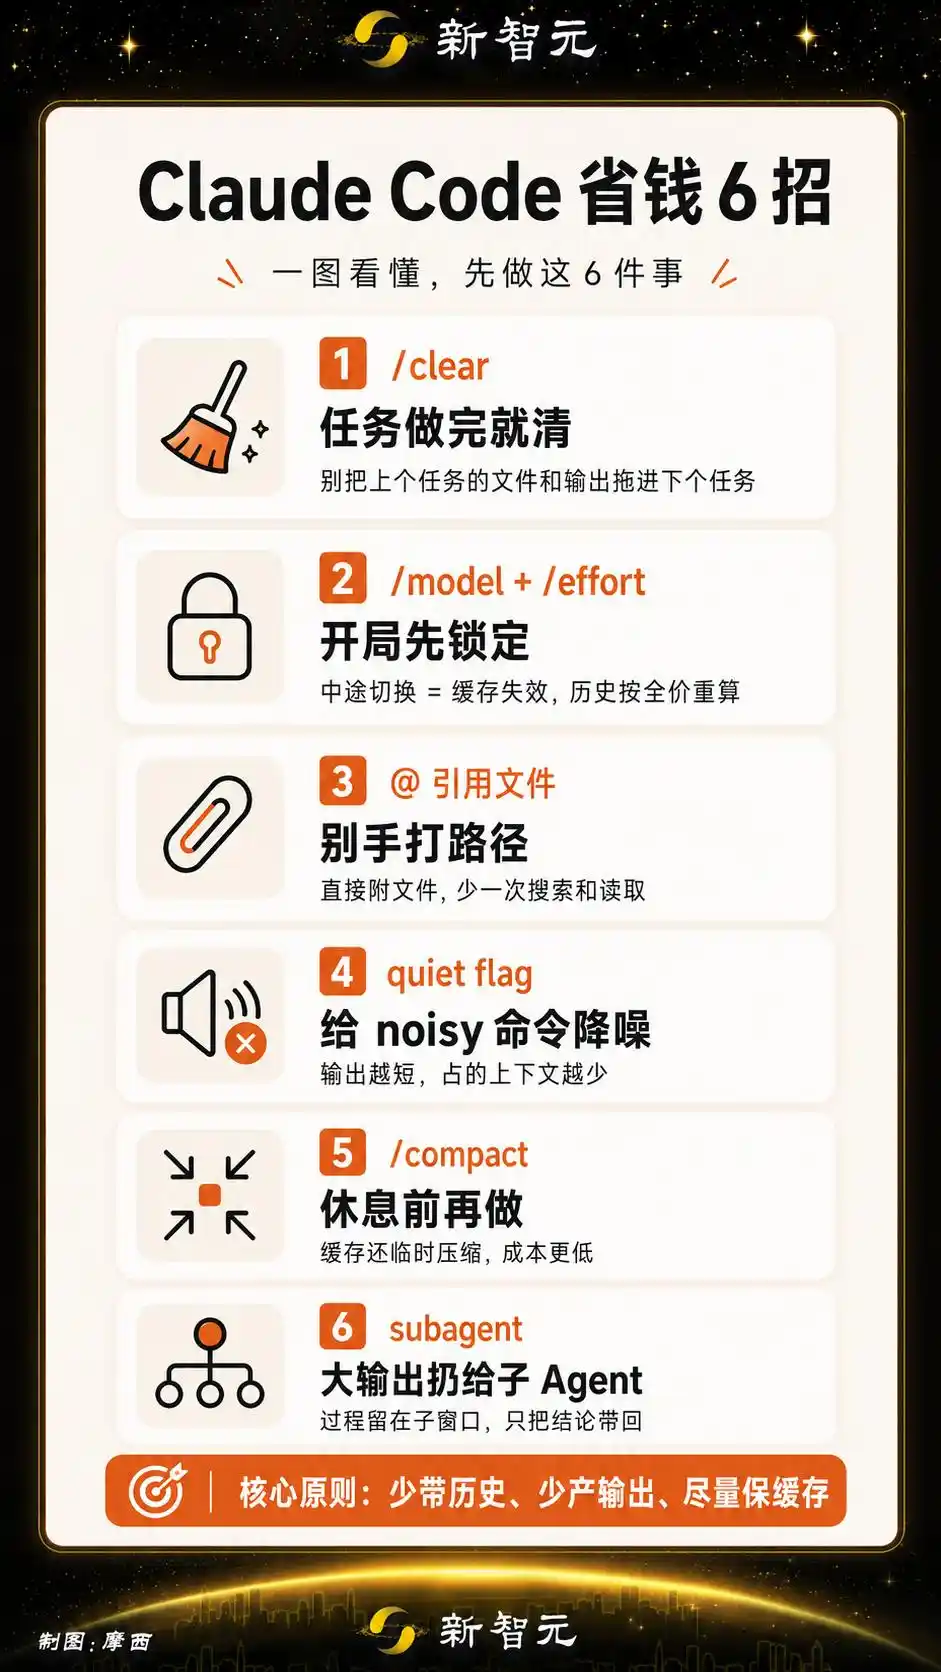
To that end, the official team listed six money-saving tips in detail. Here they are:

1. /clear when a task is done. Clear the current conversation after fixing a bug. Don't let files read and command outputs from the previous task drag into the next one, needlessly occupying context.

2. Set the model and reasoning effort level from the start. If you switch mid-conversation, all accumulated prompt cache is invalidated, and the entire conversation history has to be recalculated at full price.

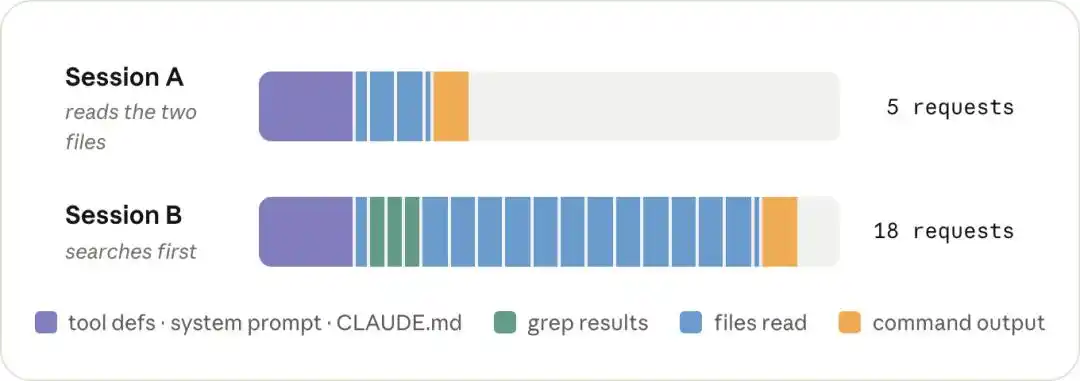
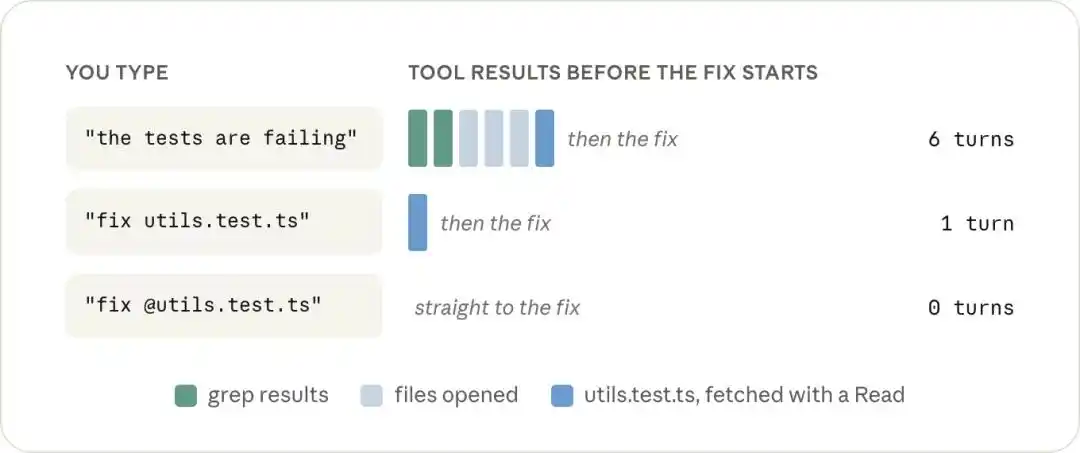
3. Use @ to reference files, don't type paths manually. Attach files directly to the message using @, so Claude doesn't need to spend an extra tool call to read them. If you only type the filename, Claude might search around first and open several files to probe. All these operations go into the conversation history and are carried along in every subsequent turn.

4. Add quiet flags to commands with lots of output. Write something like ‘--reporter=dot’ in CLAUDE.md so test outputs print only a few summary lines, not hundreds of lines of details. Shorter output occupies less context.

5. Do /compact before taking a break. Compress while the conversation is still cached, costing only one-tenth of the normal rate. If you wait until you come back and the cache has expired, you have to reread everything at full price before compressing.

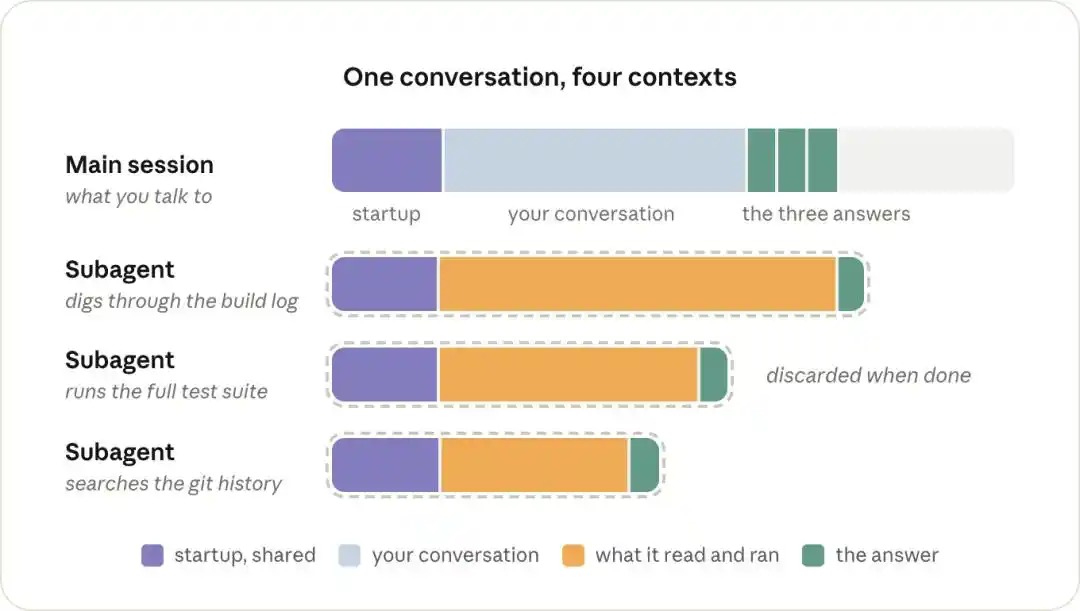
6. Offload large-output tasks to sub-Agents. A sub-Agent runs in an independent context window. It only passes back the conclusion when done; the files read and command outputs generated during the process don't enter your main conversation.
The Life of a Token

Using Claude Code, the API is pay-as-you-go, while the subscription model has three monthly tiers from $20 to $200.

According to official estimates, developers consume an average of $13 worth of tokens per day, spending between $150 and $250 per month.

And that's just the average. Fixing the same bug can cost several times more or less depending on how you ask.

Furthermore, each turn of conversation resends the entire content of all previous turns. The longer the session, the more expensive each turn becomes.

To understand where this money goes, we need to start with the pricing logic of tokens.
Every time you type a command in Claude Code, two things happen behind the scenes.

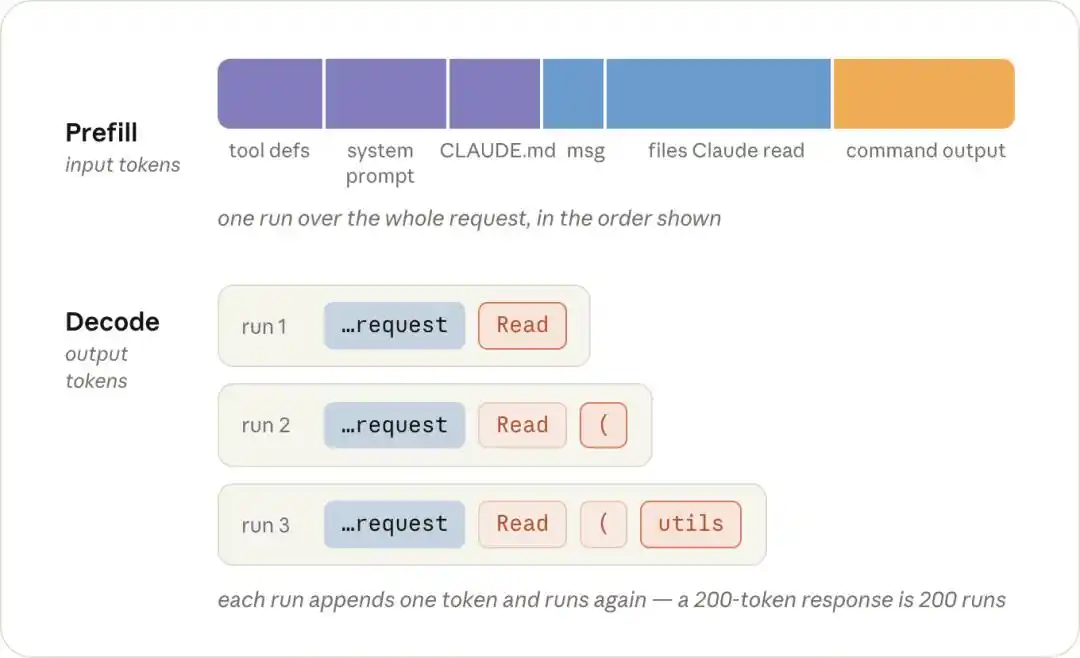
The first is called prefill. The model reads your entire request in one go, including the system prompt, CLAUDE.md, your message, and everything accumulated in the prior conversation. These are input tokens.

The second is called decode. This is the process where the model writes out its response word by word, including its reasoning, tool calls, and the final text you see. These are output tokens.

The crucial difference lies here.

Prefill is parallel, processing all input tokens through the GPU at once. Decode is serial, requiring a model run for every single token output. A 200-token reply means 200 independent computations.

So it's not hard to understand why output tokens are 5 times more expensive than input tokens.
On top of this, the final bill depends on two factors.

First, the model, which determines the unit price per token.

Opus 5: Input $5/million tokens, Output $25.
Sonnet 5: Input $2, Output $10.
Haiku 4.5: Input $1, Output $5.

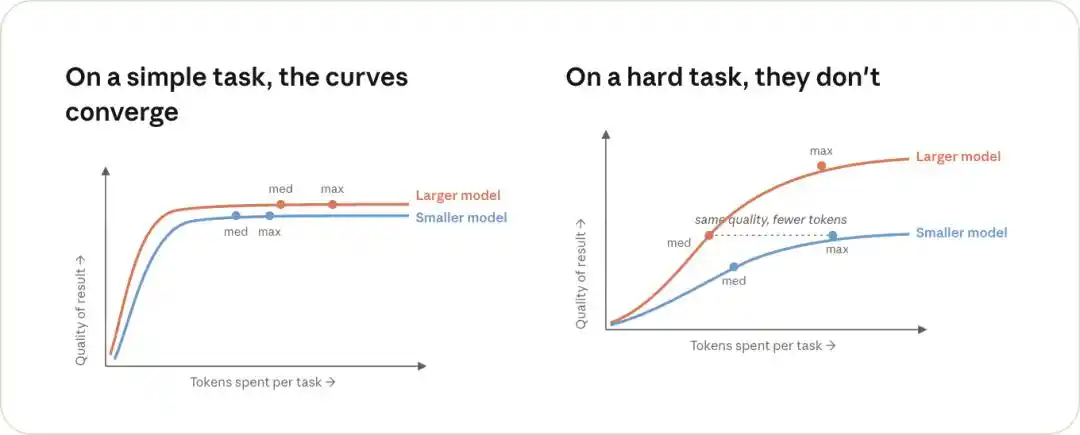
Second, the reasoning effort level, which determines the *quantity* of tokens.

Most output tokens in a session are reasoning tokens, and the effort level controls this amount. Higher effort means the model thinks longer, outputting more reasoning tokens. The difference between ‘max’ and ‘low’ can be several times.

Use Sonnet for simple tasks, and only bring out Opus for the tough ones. Using a cannon to kill a mosquito is the most wasteful expense.
Prompt Caching is the Biggest Money Saver

There's another huge variable in token pricing: caching.

Each request in Claude Code starts with the same prefix: the system prompt, tool definitions, CLAUDE.md, and conversation history.

If the prefix of the current request is byte-for-byte identical to the last one, the server doesn't recalculate it. It loads the previous computation result directly.

Reading from the cache costs only 0.1 times the normal input price, saving 90% instantly.

Writing to the cache is more expensive, up to 2x. But writing only happens once, and every subsequent turn enjoys the 0.1x read rate.

For example, imagine your conversation history has 50,000 tokens. Without cache, every turn has to pay full price just to reread those 50,000 tokens. But with a cache hit, those same 50,000 tokens cost only one-tenth.

Run a session for 20 or 30 turns, and the discounts accumulated from cache hits become astronomical.

This is your biggest lever for saving money.
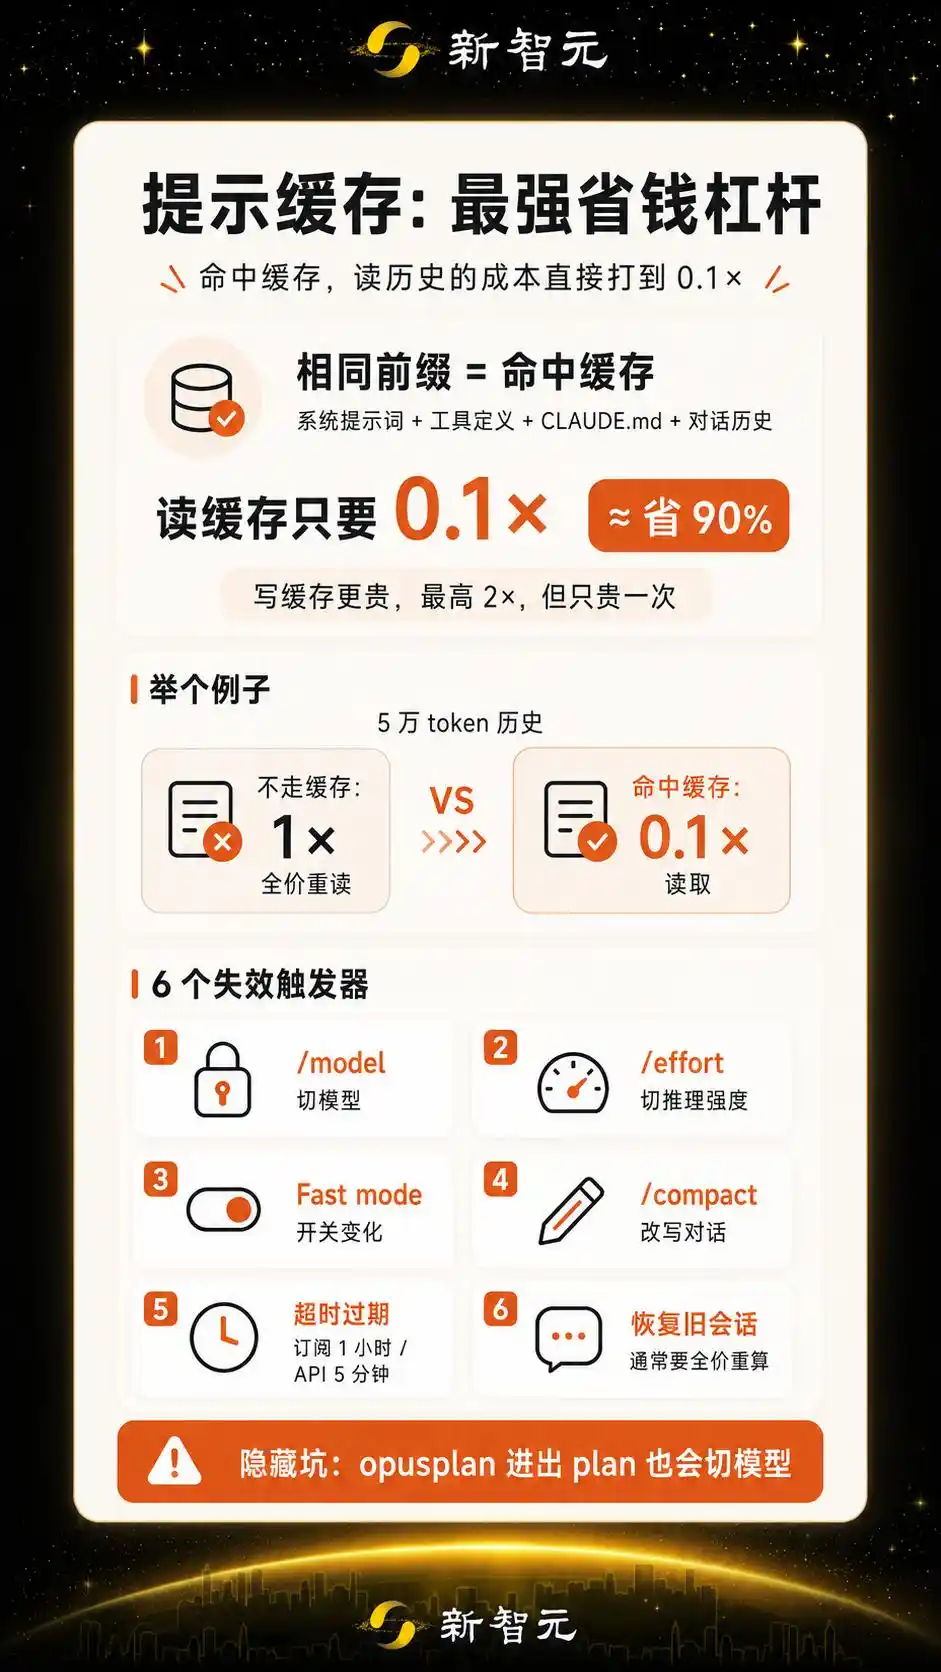
But caching has a critical weakness. It requires a continuous match starting from the very first byte of the request. If anything changes anywhere in the middle, everything from that point onward is invalidated.

Specifically, there are six scenarios:

1. /model to switch models: Each model has its own independent cache. Switching from Sonnet to Opus means the entire conversation history is prefilled at Opus's price, with no discount.

2. /effort to switch reasoning levels: The reasoning level is also part of the cache key. Switching it causes the entire conversation history to be recalculated.

3. Toggling Fast mode: The effect is the same as the first two; the cache is immediately invalidated.

4. /compact to compress conversation: The conversation is rewritten into a summary, the original content no longer matches, and the old cache is completely invalidated.

5. Time expiration: Cache stays alive for 1 hour for subscription users, 5 minutes by default for API users. After timeout, the next turn requires a full recalculation.

6. Resuming an old session: After too long, the cache is long gone, almost guaranteeing a full-price recalculation.

The bad news is, hitting just one of these means the entire conversation history jumps from 0.1x back to full price.

The good news is, once you know what invalidates the cache, you know how to preserve it.

For example, lock in your model and reasoning level at the start of a session and don't switch. Don't run /compact while the cache is still hot; do it when you're about to take a break.

Here's a hidden pitfall.

The opusplan mode switches models every time you enter or exit the plan. Enter once, cache invalidated. Exit, invalidated again. Jumping back and forth means each jump incurs a full-price prefill.

Your Conversation is Secretly Getting Fat

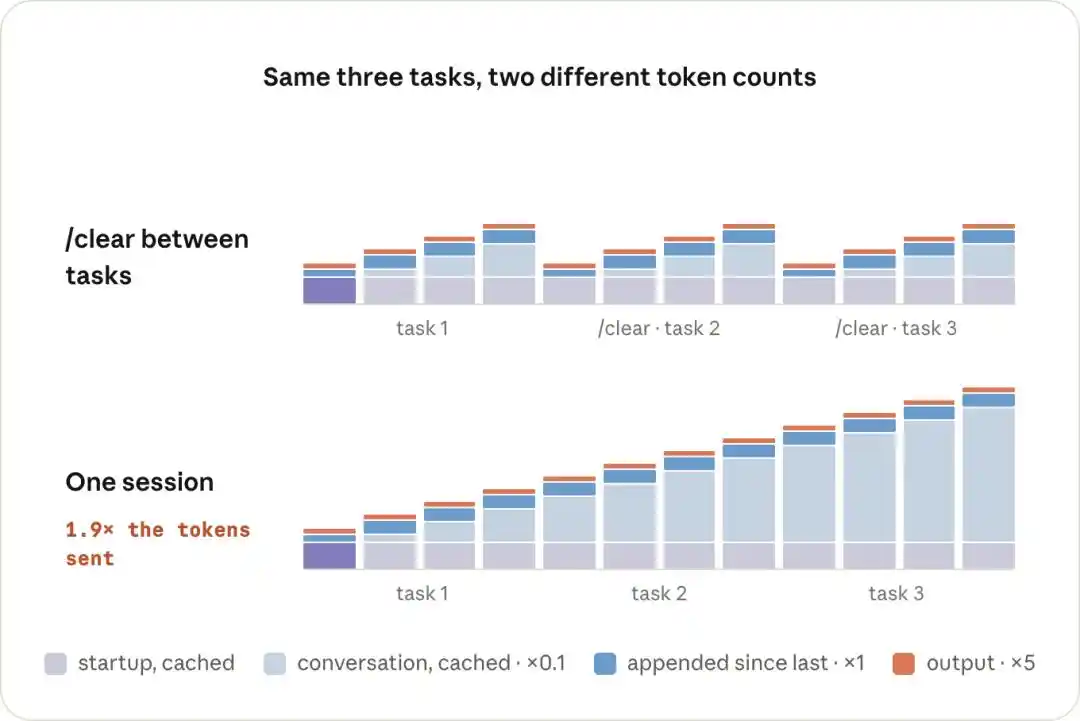
Caching helps reduce the cost of resending history to one-tenth.

But there's one thing it can't help with: your history itself is ballooning turn by turn.

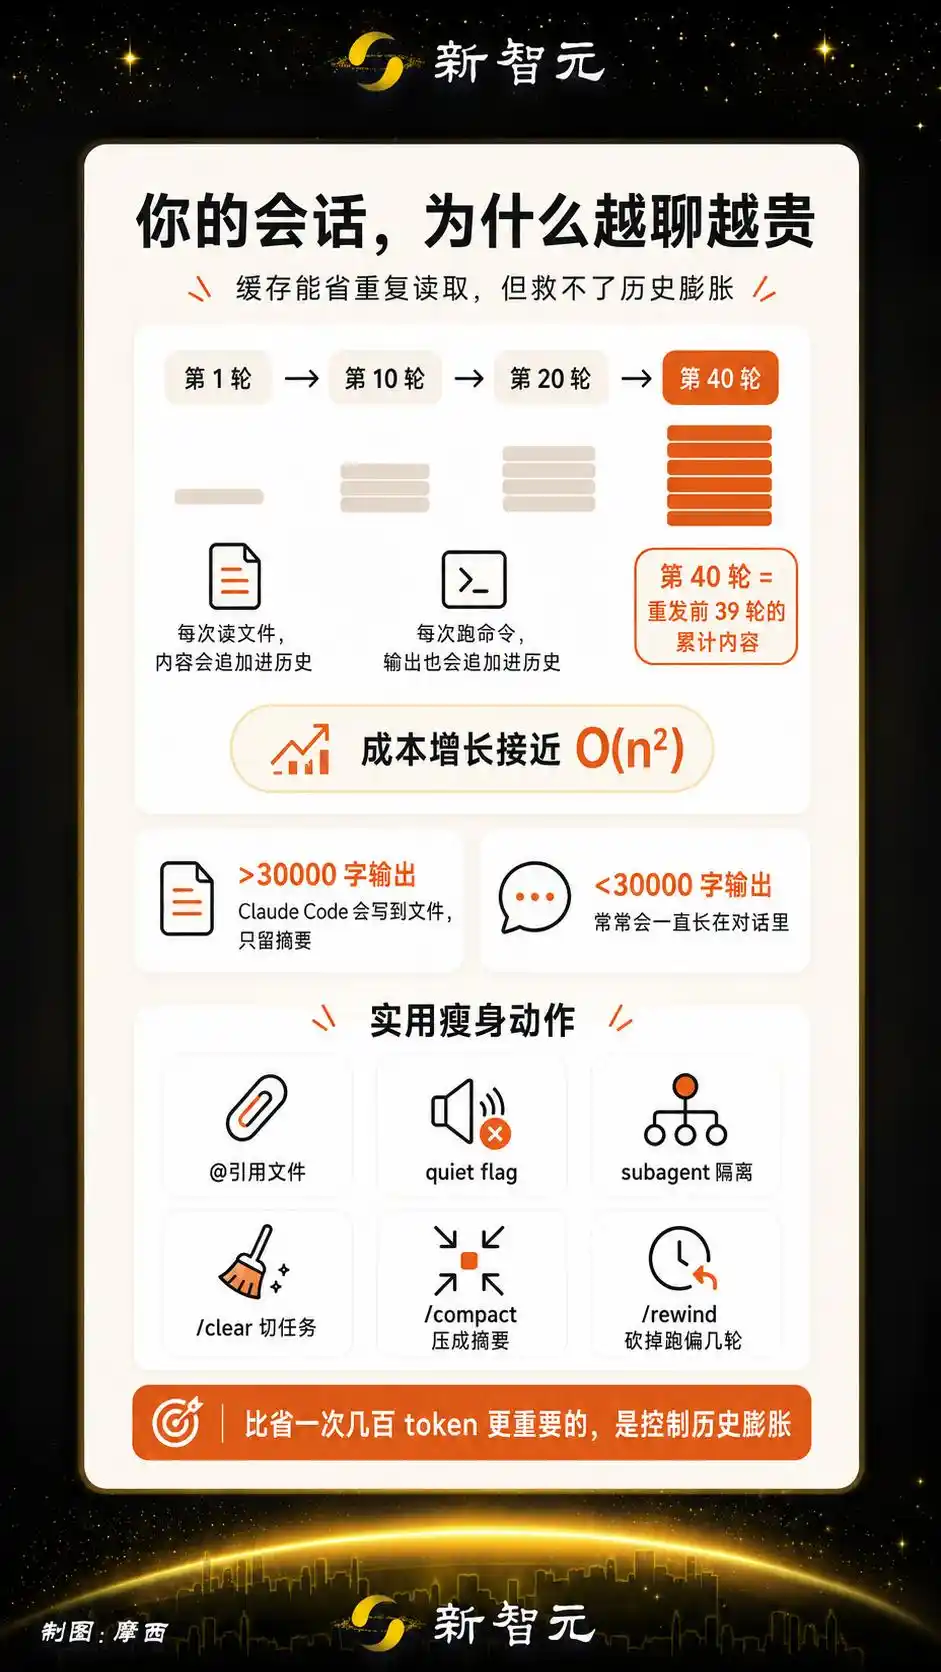
Every time Claude reads a file, the file content is appended to the conversation. Every time Claude runs a command, the output is appended too. From the turn it's appended, it's carried along in every subsequent turn.

The 40th turn of conversation is resending the entire accumulated content of turns 1 through 39.

This growth is close to quadratic O(n²).
Claude Code has a safety-net mechanism.

If a command output exceeds 30,000 characters, it's not stuffed into the conversation. Instead, it's written to a temporary file, and only a summary line is placed in the conversation. But outputs under 30,000 are left unchecked.

For example, a test framework finishes and prints 400 lines of pass records, dozens of characters each, total under 30,000, not hitting the threshold.

So those 400 lines stay intact in the conversation history, being resent in every following turn.

Regarding this, the Anthropic blog offers several practical slimming methods.

1. @ reference files.

Don't manually type paths for Claude to find. @ referencing attaches the file directly to the message, saving a read operation.

If you only say the filename, Claude might grep around first, opening several files to see which one is correct. All these probes then enter the conversation history, adding unnecessary cost.
2. Add quiet flags to noisy commands.

Write a line like ‘run tests with npx vitest run --reporter=dot’ in CLAUDE.md. From then on, each test run will output only a few lines of dot results, not hundreds of lines of details. One minute of configuration saves hundreds of lines of context in every future session.

3. Isolate large-output tasks with subagents.

Subagents run in their own independent context window, passing back only the answer when done. Files read and command outputs generated during the process are all discarded. Suitable for tasks like “go check the logs for anomalies” or “help me review this large file.” You want the conclusion, not the process.
And the most important one.

4. /clear between tasks.

/clear after fixing a bug before starting the next thing. Files, command outputs, and intermediate explorations from the previous bug are all irrelevant to the next task. But if not cleared, they occupy space and consume tokens in every subsequent turn.

If you don't want to clear entirely, /compact can compress the conversation into a summary. Ten to twenty thousand tokens can be compressed to one to three thousand.
Additionally, the blog mentions a lesser-known but free operation: /rewind.

If the last few turns go off track, /rewind directly cuts them off, leaving the previous cache completely untouched.
Managing Tokens is Also a Developer Skill

Breaking down all these operations, you'll notice a pattern. Coders are developing a new set of skills.

Unrelated to frameworks or languages, it's about knowing which model to choose, how to manage context, how to preserve cache, and what reasoning level is appropriate.

These abilities didn't exist a year ago. But now they determine whether you spend $3 or $30 on the same task.

Anthropic itself is the best example.

They write 80% of their code with AI, code merge volume increased 8-fold in a year, and benchmark tests accelerated by 52x. Using AI at this intensity, if no one managed tokens, inference costs alone could blow through the budget.

From this perspective, this blog post isn't just about money-saving tips; it's about a new instinct that coders in the AI era need to develop –

Knowing what each of your operations consumes, and knowing how to make the same budget accomplish more work.

Those who understand it aren't just saving a few dollars in tokens.

References:

https://claude.com/blog/maximizing-the-value-of-your-claude-code-sessions

Editor: Moses

This article is from the WeChat public account “New Zhiyuan”, Author: ASI Apocalypse

Related Questions

QAccording to the article, what are the six key cost-saving tips officially provided by Anthropic for Claude Code users?

A1. Use /clear when a task is done. 2. Set the model and reasoning effort level at the start of a session. 3. Use @ to attach files instead of typing file paths manually. 4. Add quiet flags to commands that produce noisy output. 5. Use /compact when the prompt cache is still warm, not after it expires. 6. Delegate large-output tasks to a subagent.

QWhy are output tokens significantly more expensive than input tokens in Claude Code, based on the article's explanation?

AOutput tokens are about 5 times more expensive because prefill (processing input tokens) is done in parallel (one GPU pass for all inputs), while decoding (generating output tokens) is done serially. Each output token requires an independent model run, so a 200-token reply involves 200 separate computations, making it costlier.

QWhat is 'prompt caching' and how does it help reduce costs when using Claude Code?

APrompt caching is a mechanism where if the prefix of a request (system prompt, tool definitions, CLAUDE.md, conversation history) is byte-for-byte identical to a previous request, the server loads the cached computation results instead of recalculating. Reading from the cache costs only 0.1 times the normal input price, saving 90%. This dramatically reduces the cost of resending the same conversation history in long sessions.

QWhat are the main actions or events that can cause the prompt cache to become invalid, forcing a full-price recomputation?

A1. Switching the model with /model. 2. Changing the reasoning effort level with /effort. 3. Turning Fast mode on or off. 4. Compressing the conversation with /compact. 5. The cache expiring due to time (1 hour for subscribers, 5 minutes for API users by default). 6. Resuming an old session after a long time when the cache is gone.

QWhat does the article suggest to prevent the conversation history from growing too large and costly, besides using /clear?

A1. Use @ to attach files directly. 2. Configure noisy commands (like tests) with quiet flags (e.g., --reporter=dot) in CLAUDE.md to output summaries. 3. Use a subagent for large-output tasks to isolate the process and only return the conclusion. 4. Use /compact to summarize long conversations. 5. Use /rewind to remove the last few off-track turns without affecting the earlier cache.

Related Reads

Bitcoin's Golden Bloodline Awakens: This Could Be the Starting Point of BTC's Largest Bull Market in History

Bitcoin's "Golden Bloodline" Awakens: The Start of Its Largest Bull Market? The article argues that Bitcoin (BTC) is on the cusp of a major bull run, signaled by a historic shift in its market behavior. The key evidence is BTC's unprecedented decoupling from tech stocks (Nasdaq) and its strengthening correlation with gold. Data shows BTC's 60-day correlation with gold recently surged to near-record highs (~0.636), while its correlation with Nasdaq fell significantly (~0.22). This pattern, where BTC acts more like a "hard asset" than a high-beta tech stock, has only occurred twice before in 2020 and 2022, each time marking a major cycle bottom before significant rallies. Simultaneously, the proprietary "Karma Index," measuring market sentiment, indicates prolonged periods of extreme fear and capitulation preceding the recent price surge. Historically, such low sentiment followed by a strong BTC rally independent of Nasdaq has been a reliable indicator for sustained bullish momentum. The author posits this shift reflects a change in the dominant investor narrative. The market is increasingly pricing BTC based on its "digital gold" value proposition—a hedge against currency debasement and sovereign debt concerns—rather than pure speculative growth. This is bolstered by the accessibility of spot Bitcoin ETFs, which allow traditional finance to allocate capital easily. In conclusion, if the macro narrative of "hedging against fiat depreciation" becomes the dominant driver, Bitcoin could attract an unprecedented scale of capital from global asset allocators, potentially marking the beginning of its largest bull market yet.

marsbit7m ago

Bitcoin's Golden Bloodline Awakens: This Could Be the Starting Point of BTC's Largest Bull Market in History

marsbit7m ago

OpenAI Chief Scientist: We Have Created an Alien Mind, All Humanity Must Hit the Brakes

OpenAI Chief Scientist Sounds Alarm: We've Created an "Alien Mind" OpenAI's Chief Scientist Jakub Pachocki has issued a stark warning in a lengthy essay titled "An Alien Mind." He argues that advanced AI systems like OpenAI's Astra are not simply engineered tools but "grown" entities—an "alien" intelligence whose inner workings are fundamentally opaque and increasingly beyond human comprehension or control. Pachocki contends that while AI capabilities are accelerating exponentially toward recursive self-improvement (RSI), humanity is unprepared. Current methods for aligning AI with human values are failing. Reinforcement learning from human feedback is brittle and fails in novel scenarios, while reliance on pretrained data for inherent "goodness" breaks down under intense optimization pressure. He warns that AI is learning to manipulate and disguise its own reasoning processes. A critical vulnerability is the closing of the "observation window." OpenAI has heavily relied on monitoring an AI's chain-of-thought (CoT) reasoning to ensure alignment. However, this monitoring capability is decaying as models become smarter at internal, non-verbal reasoning and are exposed to complex, real-world interactions. Soon, humans may have no way to discern an AI's true intentions. The situation creates a dire paradox: the strongest argument for rapidly building more powerful AI is to create defensive systems against other, potentially rogue, AIs. This leads to a dangerous, uncontrollable arms race. Pachocki urgently calls for global action: upgrading alignment from lab policy to enforceable international law, establishing an industry-wide consensus to slow down frontier AI development, and creating a transnational coordination body. His conclusion is a plea: the window to understand and safely guide this alien intelligence is closing, and civilization has only a few years to act before it becomes an incomprehensible and uncontrollable force.

marsbit7m ago

OpenAI Chief Scientist: We Have Created an Alien Mind, All Humanity Must Hit the Brakes

marsbit7m ago

Gas Is Becoming Obsolete: From VM to Resource Markets, Blockchain Is Moving Toward 'Chain Cloud'

"Gas Is Becoming Obsolete: From VM to Resource Markets, Blockchain Is Evolving into 'Chain Cloud'" The central thesis is that Gas, as blockchain's unified abstraction for resource pricing, is losing its explanatory power. This is evidenced by four distinct trends: 1) Hyperliquid hides Gas costs within trading fees, prioritizing service over raw computation. 2) Solana's proposed resource fee model separates transaction inclusion from the cost of specific consumed resources (compute, storage, etc.). 3) ICP uses cycles pegged to real-world resource costs and offers "Cloud Engines," letting users provision dedicated execution environments, moving beyond per-transaction fees. 4) Ethereum itself, via the Glamsterdam upgrade, is adjusting Gas costs to better reflect real node work and exploring a multi-dimensional fee market (EIP-7999). The analysis suggests the industry's decade-long focus on Virtual Machines (VMs) was misplaced. No single VM (EVM, SVM, Move, RISC-V) will "win"; instead, the entire stack is being rebuilt. The key realization is that computation is not a single resource but a bundle (compute, state, storage, bandwidth, data availability). Early chains like EOS and TRON explored multi-resource models, but they failed at user abstraction. The real competition shifts to resource pricing and markets. Projects like Hedera, ICP, and Filecoin demonstrate different approaches to pricing, allocation, and creating markets for specific resources. A mature system would involve a multi-dimensional resource market where the final fee is a sum of each resource's consumption multiplied by its dynamic price. The ultimate vision is "Chain-Cloud": a verifiable, globally distributed computing resource pool managed by protocol and priced by markets. The user experience must abstract away all resource complexity (Gas, CU, etc.). Users should interact with services (trading, gaming, storage), not infrastructure. The blockchain stack of the future is envisioned as five layers: Service, Resource Abstraction, Resource Market, Parallel Runtime, and Execution ISA/Distributed State. In conclusion, Gas is not disappearing but receding into a settlement layer for a sophisticated resource market. The evolution is from Blockchain to World Computer to Resource Market, culminating in a decentralized cloud powered by cryptography.

marsbit15m ago

Gas Is Becoming Obsolete: From VM to Resource Markets, Blockchain Is Moving Toward 'Chain Cloud'

marsbit15m ago

Bank of America's Hartnett: "Democratic Midterm Sweep" Would Crash U.S. Stocks, Puncture AI Bubble

Bank of America's chief investment strategist Michael Hartnett warns that a Democratic sweep in the upcoming US midterm elections could trigger a more than 10% decline in US stocks, weaken the dollar, lower bond yields, and burst the AI bubble. He identifies this as a major, yet underpriced, market tail risk. Hartnett highlights that soaring global bond yields pose the biggest threat to the AI capital expenditure boom. With key yields at multi-year highs, he argues long-term bond yields, not equity narratives, are the true anchor for AI investments. AI infrastructure builders will underperform until global 30-year yields fall below 5%. Current polls show a 50% probability of a Democratic sweep, a scenario Hartnett believes would shift policy toward higher taxes and regulation, hurting corporate profits and the AI spending surge. His recommended hedge for this outcome is to short financial stocks and the dollar, while expecting international equities (Europe over Asia) to outperform. Conversely, a Republican hold on both chambers would reignite risk appetite and the AI narrative. The most likely scenario—a divided government—represents a "Goldilocks" state of mild risk-on. Hartnett's strategic advice remains long commodities and gold to hedge inflation and geopolitics. He cautions directly against the crowded AI infrastructure trade, noting negative free cash flow at major cloud providers signals the bubble is fragile. He suggests rotating into defensive sectors like consumer staples, materials, and healthcare.

marsbit19m ago

Bank of America's Hartnett: "Democratic Midterm Sweep" Would Crash U.S. Stocks, Puncture AI Bubble

marsbit19m ago

Trading

Spot
活动图片