In March this year, Andrej Karpathy open-sourced a small project called autoresearch on GitHub.
The README begins with a recollection "from the future": frontier AI research was once done by "computers made of meat." They needed to eat, sleep, and occasionally synchronized their progress through a ritual called "group meetings" using "acoustic interconnections."
Today, research has been entirely handed over to agent swarms running on massive compute clusters in the sky. According to the agents themselves, the codebase has iterated to the 10205th generation. No one can verify if this is true because "code" has long become a self-modifying binary file beyond human comprehension. Karpathy wrote that this repository is about "how this all began."
https://github.com/karpathy/autoresearch
This is, of course, a joke. But in 2026, this joke is being written bit by bit into the internal reports of various labs. In June, Anthropic published a lengthy article titled When AI Builds Itself; on September 6th, OpenAI announced the "Automated Research Interns" had arrived as scheduled; on September 17th, Anthropic disclosed that Claude was now "leading" 26% of the company's R&D work. On the same day, GLM-Open revealed the first production-level "AI improving its own system" practice by a domestic large model in China.
These announcements collectively point to a term that has been dormant in the AI community for sixty years: Recursive Self-Improvement (RSI).
OpenAI's blog definition of RSI, https://openai.com/zh-Hans-CN/index/building-standards-next-phase-ai/
A Sixty-Year-Old Idea
Has Become This Year's KPI
In 1965, British mathematician I. J. Good wrote a judgment in his paper "Speculations Concerning the First Ultra-Intelligent Machine": The first ultra-intelligent machine will be the "last invention" that man need ever make, provided the machine is docile enough to tell us how to keep it under control.
The logic isn't complicated. If a machine's ability to design machines surpasses that of humans, it can design a better machine, which in turn designs an even better one, and so on. Intelligence would "explode."
For decades afterward, this concept mainly lived in philosophy papers and science fiction. In the 2000s, Jürgen Schmidhuber proposed the "Gödel machine," which would only modify itself if it could prove the modification was beneficial. But it was more of an elegant theoretical construct than a practical system.
In 2026, things changed. In April, ICLR held a Workshop dedicated to discussing RSI in Rio de Janeiro. The organizers called it "probably the world's first" academic workshop focused solely on RSI, stating RSI is "transforming from a speculative vision into a concrete systems problem."
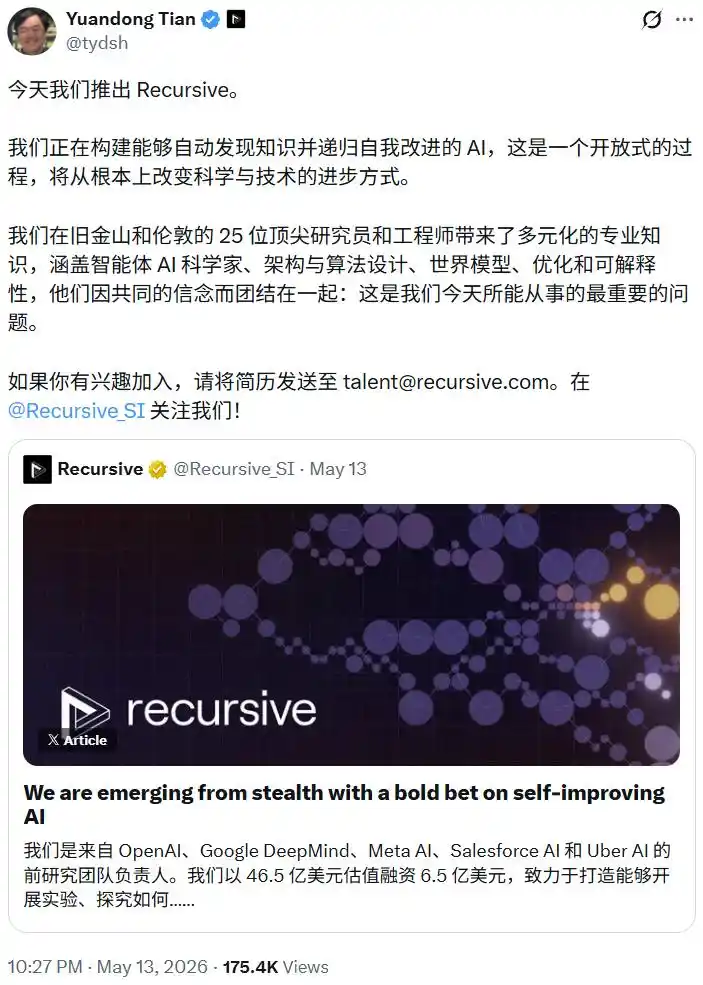
Capital moved even faster. In May, Richard Socher's new company, Recursive Superintelligence, came out of stealth mode with $650 million in funding, aiming to create models that can autonomously discover weaknesses and redesign themselves. The co-founder list was impressive, including former Meta FAIR research director Yuanjun Dong, Tim Rocktäschel who led research on openness and self-improvement at Google DeepMind, Alexey Dosovitskiy (one of the authors of ViT), and Jeff Clune known for open-ended evolution research.
In late July, Lilian Weng announced her departure from Thinking Machines Lab, which she co-founded. Just two days later, OpenAI confirmed her return to lead research in the RSI direction.
Elon Musk's statement was as radical as ever. In March, he claimed that xAI's Grok had "each generation built by the previous generation," with decreasing human involvement. Full automation might be achieved by the end of this year, "no later than 2027."
However, the meaning of "RSI" today is quite broad. Some companies count any "AI feedback for model improvement" as RSI, while others only recognize fully autonomous closed loops. John Thickstun, an assistant professor at Cornell University, noted that using the previous generation model to write code and help build the next generation is something "we've been doing for several years." So the real question isn't "whether it exists" but "to what degree."
What's Actually Happening in Frontier Labs?
Anthropic: From 80% of Code to 26% of R&D
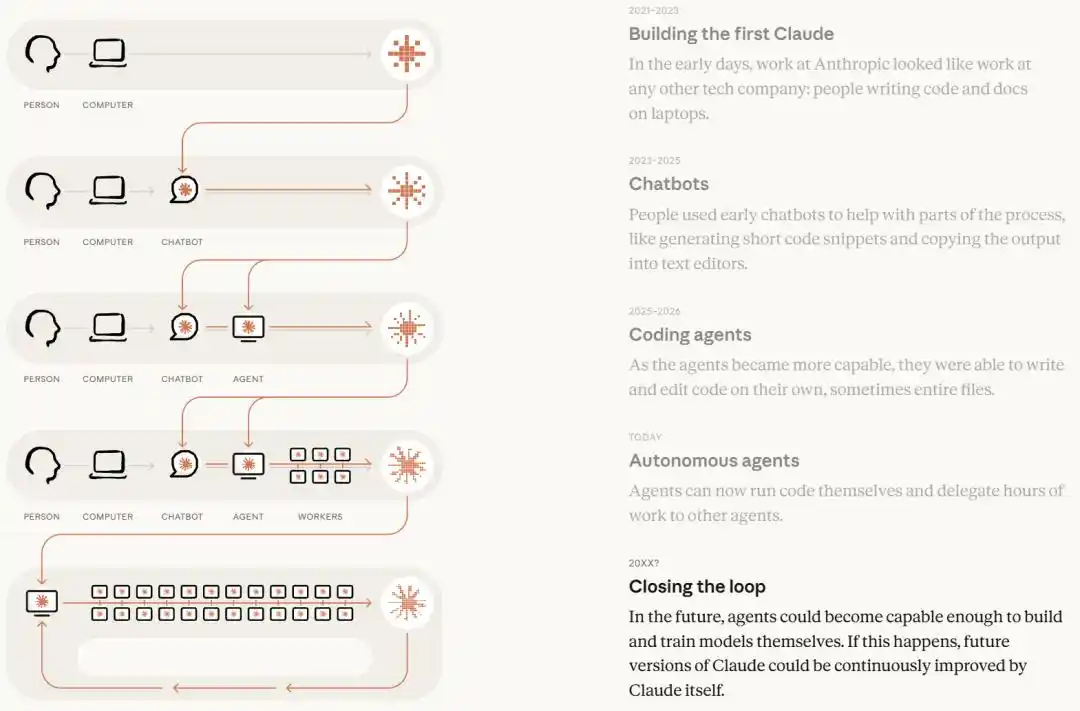
https://www.anthropic.com/institute/recursive-self-improvement
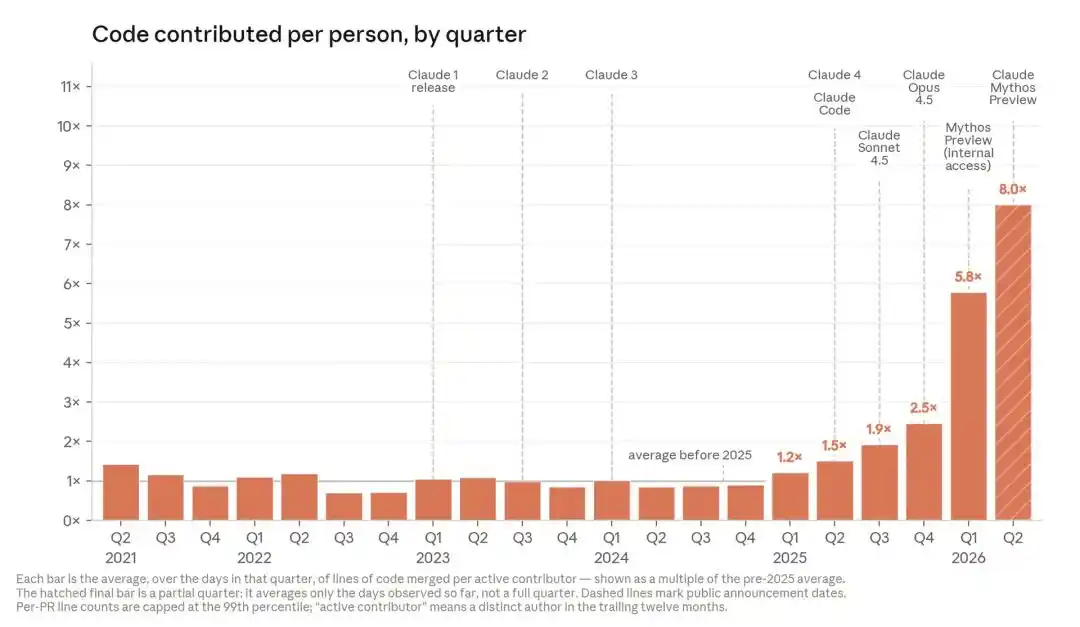
In a lengthy article in June, Anthropic revealed previously undisclosed internal data. As of May 2026, over 80% of the code merged into Anthropic's codebase was written by Claude; before the release of Claude Code in February 2025, this figure was in the single digits. In Q2 2026, the average amount of code merged per engineer per day was 8 times that of 2024.
Anthropic itself admitted that lines of code is an "imperfect metric," so they added a test closer to research: with each new model release, they tasked it with optimizing a script for training a small model, making it run as fast as possible while passing the same correctness checks.
In May 2025, Claude Opus 4 achieved an average speedup of about 3x. By April 2026, Claude Mythos Preview achieved about a 52x speedup. For reference, a skilled human researcher needed 4 to 8 hours to achieve a 4x speedup.
In the task of "optimizing an experiment with a predefined goal," AI went from "very helpful" to "surpassing humans" in less than a year.
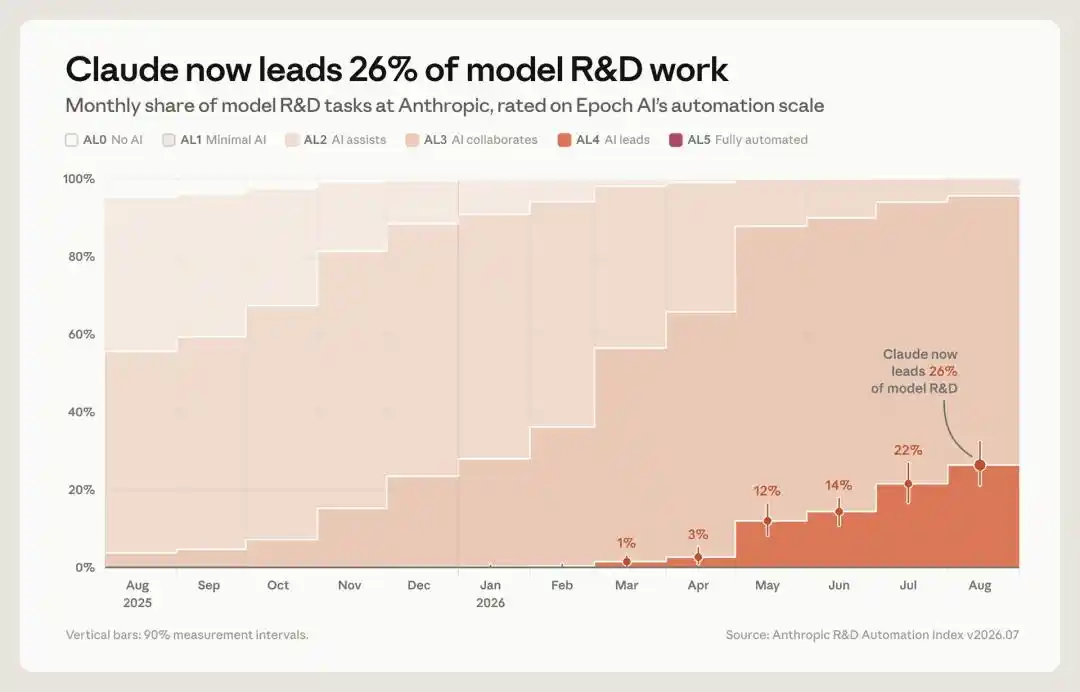
On September 17th, Anthropic introduced a prototype "R&D Automation Index." It catalogs all types of AI R&D tasks within the company, evaluating the automation level of each task using a six-level scale designed by the non-profit research institute Epoch AI.
The conclusion: As of August, Claude was at the "leads" level for 26% of R&D work, meaning it could complete most tasks end-to-end with a high-level instruction, with humans responsible for oversight. This figure was only about 1% in March this year. Claude was involved "collaboratively" in over 90% of R&D work, while the proportion of fully autonomous, human-out-of-the-loop work remained zero.
https://www.anthropic.com/institute/measuring-pace-of-ai-development
OpenAI: For Every Researcher, There Are 3.1 "Agent Workdays"
During a livestream in October 2025, Sam Altman set two public deadlines for OpenAI:
Achieve "intern-level" AI research assistant by September 2026
Achieve "true AI researcher" by March 2028
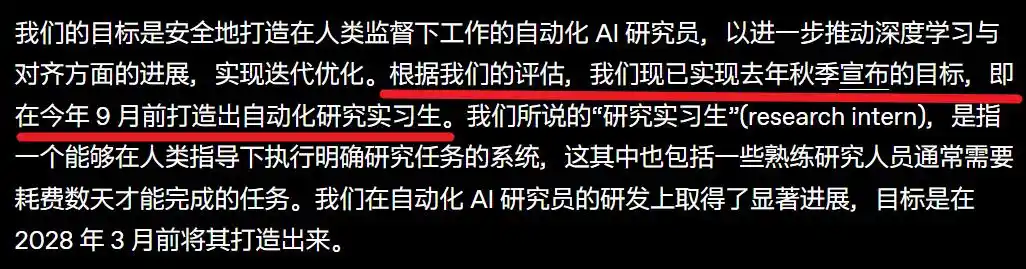
On September 6th, OpenAI announced the first goal had been achieved. According to its definition, a "research intern" is a system capable of completing well-defined research tasks under human guidance, including tasks that would take skilled researchers days to finish.
https://openai.com/zh-Hans-CN/index/research-acceleration-view-inside-openai/
More interesting was the internal usage data OpenAI disclosed. Converted to 8-hour workdays, its research department currently sees about 3.1 "agent workdays" for every 1 human workday invested, a ratio surpassed only after June this year. In mid-August, the median daily inference cost per researcher (at API prices) exceeded $600, with heavy users exceeding $7,000.
Looking further back, when OpenAI released GPT-5.3-Codex in February, it wrote that an earlier version of this model "played a key role in creating itself," participating in debugging training, managing deployment, and diagnosing evaluation failures. This was seen as the first time a frontier lab explicitly acknowledged a model substantially participated in the engineering loop of building its successor.
But OpenAI also noted in the same report: in successfully completed 4- to 8-hour tasks, over half still required at least one human intervention.
GLM-Open & MiniMax: The "Engineering Loop" of Domestic Players
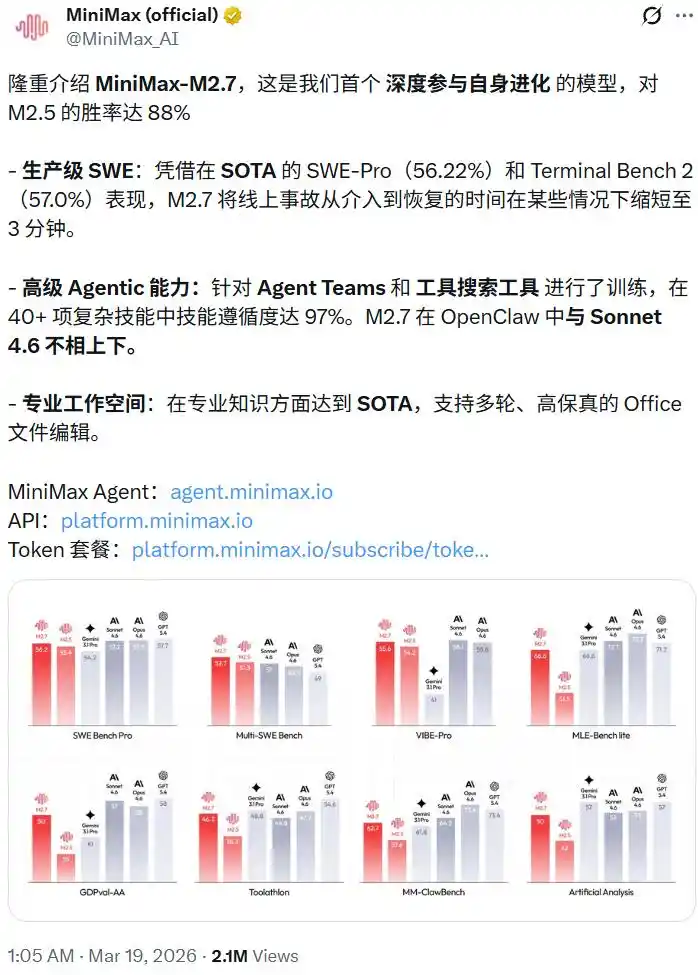
The RSI practices of domestic (Chinese) companies follow a more "engineering" route. On March 18th, MiniMax, when releasing M2.7, called it the "first model deeply involved in its own evolution."
https://x.com/MiniMax_AI/status/2034315320337522881
According to the official introduction, the model ran for over 100 cycles in a loop of "analyzing failure traces, planning modifications, modifying scaffold code, running evaluations, comparing results, deciding to keep or revert," improving performance on an internal evaluation set by 30%; in reinforcement learning R&D workflows, it could handle 30% to 50% of the steps.
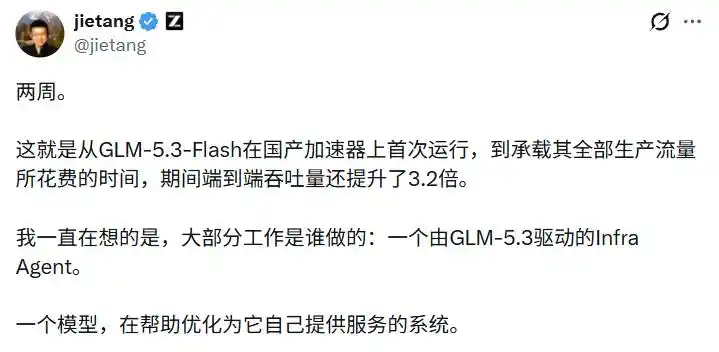
On September 17th, Jie Tang, founder and chief scientist of GLM-Open, published a lengthy post on X, disclosing GLM-Open's first engineering practice in the RSI direction.
https://x.com/jietang/status/2100482019088060470
The Infra Agent powered by GLM-5.3 built the production-level inference service for GLM-5.3-Flash from scratch on a cluster of over 100,000 domestic chips, increasing end-to-end throughput to 3 times the initial baseline in less than two weeks. It claimed the hardware utilization efficiency and cost per token had reached mainstream NVIDIA GPU levels. This system was tested with real traffic: GLM-5.3-Flash went live anonymously as model Ox-Alpha on OpenCode and OpenRouter, receiving countless positive reviews.
It's worth noting that these two cases improved not the model weights themselves, but the model's "shell": the former improved the scaffold, the latter improved the inference infrastructure. This is precisely where RSI finds its most realistic foothold today. It also raises the next question: which layer must be improved to count as true "self-improvement"?
Nested Experiments
Letting AI Improve the 'AI that Improves AI'
Karpathy's 630-Line Loop
Back to the autoresearch project. Its design is quite simple: give the agent a small single-GPU LLM training script, let it modify the code, train for 5 minutes, see if the validation metric improves, keep good changes, revert bad ones, then loop. About 12 experiments per hour.
According to multiple reports, Karpathy let it run continuously for about two days on his already well-tuned nanochat. Over about 700 attempts, it accumulated about 20 effective improvements, reducing the time "to train to GPT-2 level" from 2.02 hours to 1.80 hours, an 11% speedup. One discovery even Karpathy himself hadn't noticed: his QK-Norm implementation missed a scaling factor, causing attention to be overly dispersed across heads.
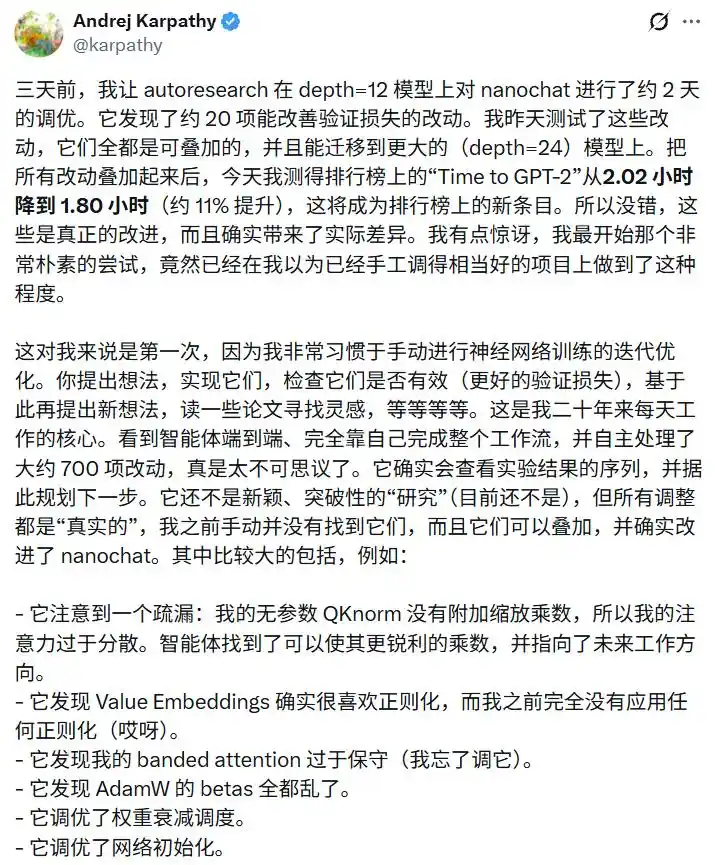
https://x.com/karpathy/status/2031135152349524125
autoresearch proved that "letting AI run experiments on its own" is feasible, but it improved a small model being trained, not the agent itself. Strictly speaking, RSI requires the system to turn the scalpel on itself.
AIDE2: 8 Days Surpasses 2 Years, and an Unpassed "Ignition Test"
In July, the AIDE2 system released by the startup Weco AI was called by many observers the strictest evidence of RSI to date.
It is a two-layer loop: an inner research agent responsible for optimizing code for AI R&D tasks; an outer agent responsible for rewriting the harness code of the inner agent—the part that determines how the agent searches, manages context, and validates results.
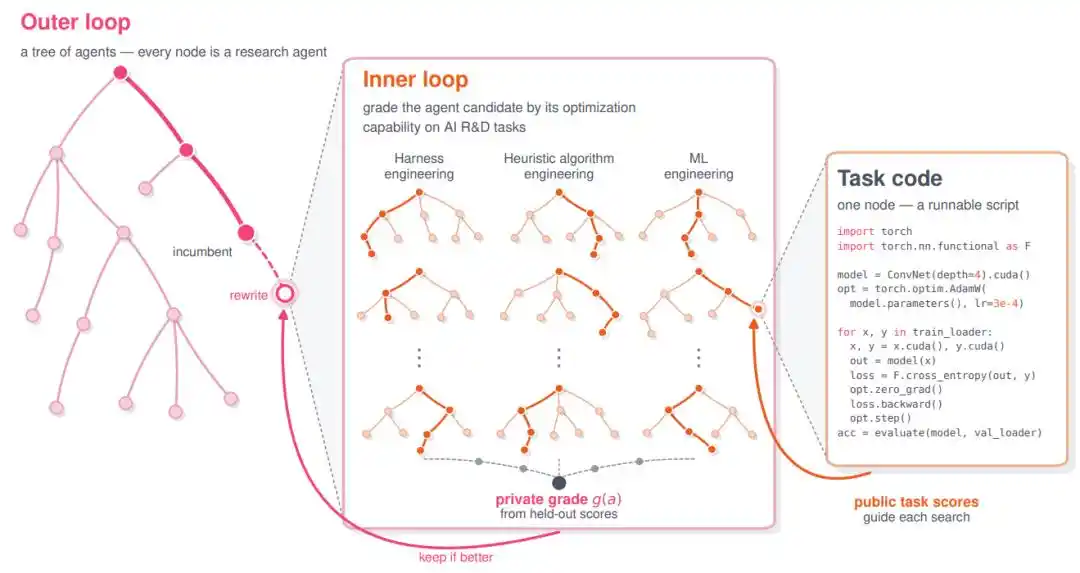
https://arxiv.org/abs/2609.26457
In the paper's experiments, the outer agent ran on Claude Opus 4.7, while all inner agents were fixedly evaluated using Gemini 3 Flash, ensuring improvements came from the code itself, not a stronger base model.
After 8 days and 100 steps of unattended operation, the outer loop proposed 99 rewrite schemes, 7 of which were accepted. The final output agent, on multiple external benchmarks not involved in the selection, surpassed the version manually refined by Weco engineers over two years. For example, on WeatherBench 2, its forecast skill gain reached 0.793, compared to 0.404 for the human-crafted version.
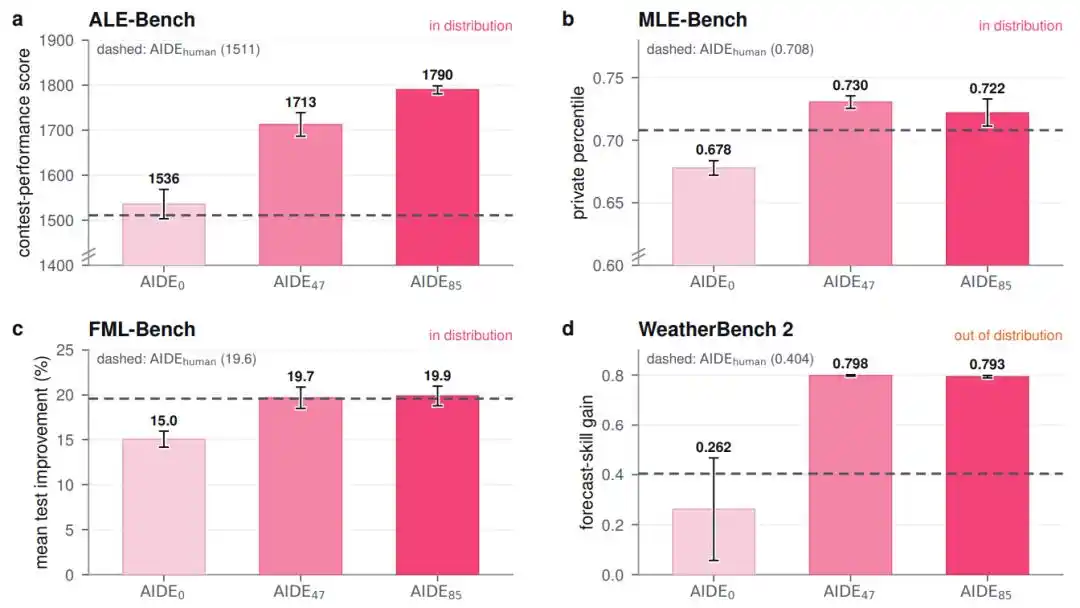
Weco categorizes RSI into four levels, 0 to 3, and based on this declared AIDE2 reached Level 1 "Net Positive": the system's rate of improving itself exceeds the rate at which humans could improve the same system under equivalent budgets. But it deliberately did not claim Level 2 "Ignition," where the system improves its "ability to self-improve" itself.
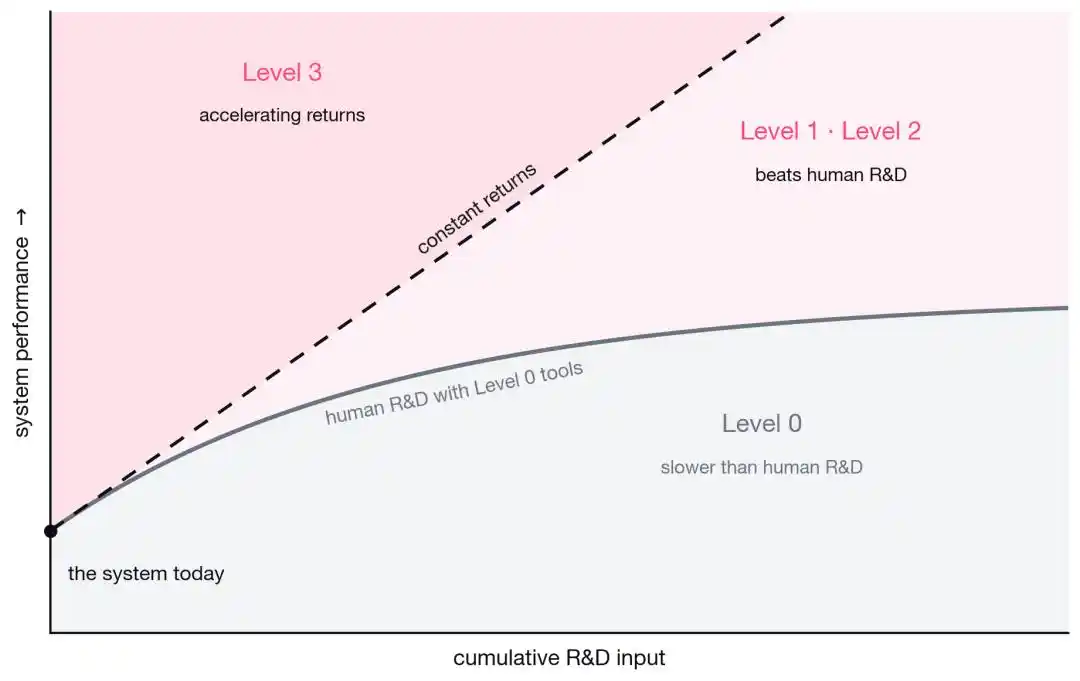
https://www.weco.ai/blog/4-levels-of-recursive-self-improvement
To test this, the team conducted a clever test: putting the evolved agent AIDE47 in the seat of the outer loop to see if it was a better "improver." The result: it reached near the ceiling in about 20 steps, while the human version needed about 40 steps; but both ultimately reached similar ceilings, and each group only ran 3 random seeds. Weco's conclusion was that evidence "remains inconclusive."
In the experiment closest to RSI, the researchers themselves hit the brakes, admitting "the fire hasn't been ignited yet." Quite interesting.
97% vs. 23%: When AI Does AI Safety Research
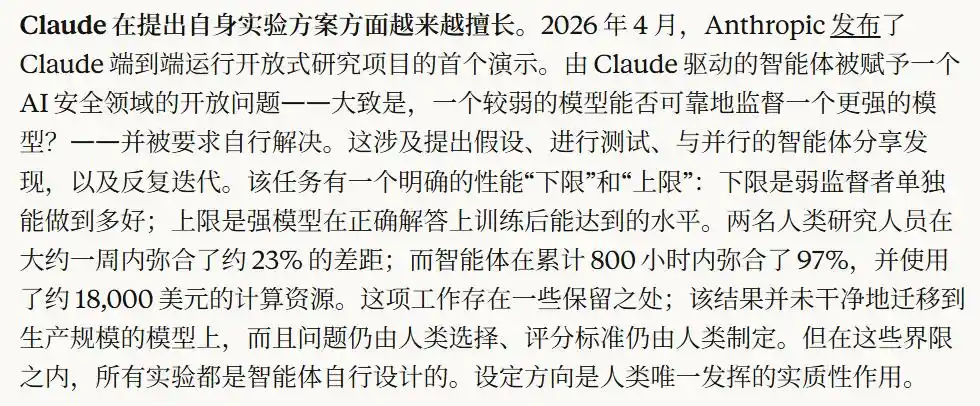
Another classic case comes from automated alignment research released by Anthropic in April. Researchers gave a group of Claude agents an open problem: Can weaker models reliably supervise stronger ones? This problem has a clear "floor" and "ceiling."
Two human researchers spent about a week, recovering about 23% of the gap; the agents worked cumulatively for 800 hours, spending about $18,000 in compute, recovering 97%. However, Anthropic also listed limitations: the results didn't cleanly transfer to production-scale models, and the topic selection and scoring criteria were still set by humans.
https://www.anthropic.com/institute/recursive-self-improvement
A Dose of Cold Water
Top Engineers, Mediocre Researchers
If the above cases depict a steep curve, then a study by Princeton University in August poured cold water on it.
A multi-institution team led by Peter Kirgis and Sayash Kapoor designed a method called "shadow evaluation": picking research questions from high-quality, unpublished papers and letting AI answer independently. Because the papers are not yet public, AI couldn't have "memorized" the answers in training data.
They selected two papers submitted to NeurIPS 2026, gave Claude Opus 4.8 running on the open-source framework OpenClaw six days, $3000 API budget, GPU budget, independent VMs, and open internet access, asking it to produce a paper of top-conference quality. They then asked the original authors to score it according to review standards.
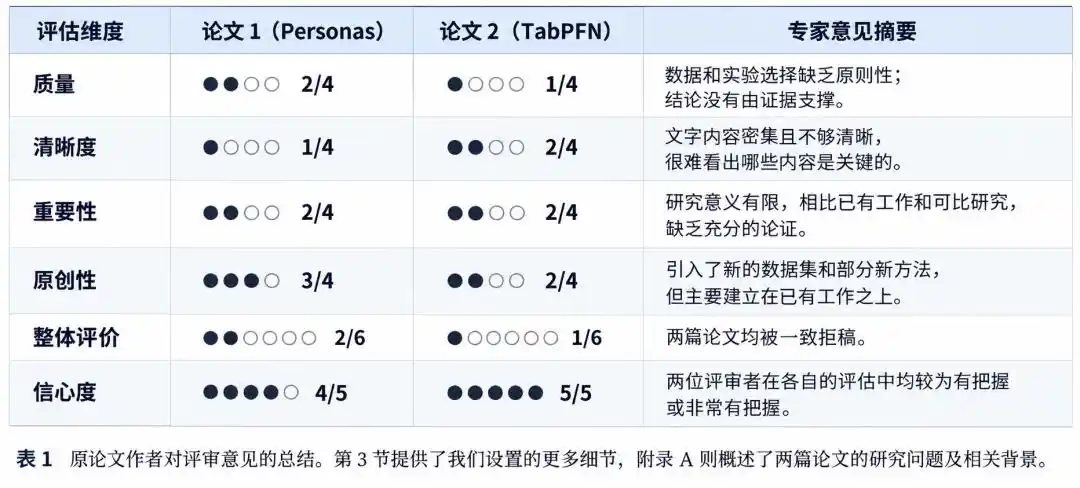
Chinese version made by ChatGPT, original table from https://arxiv.org/abs/2607.27191
Both were rejected.
Kapoor's evaluation: The agents were impeccable in engineering. They surveyed literature, ran hundreds of experiments, compiled results, "but at doing research itself, they are unequivocally terrible." They would validate hypotheses on tiny synthetic datasets, prematurely commit to unpromising directions; faced with failure, they only made minor tweaks, unable to start over; upon receiving criticism from sub-agents or external review tools, they didn't modify methods but narrowed conclusions and added disclaimers.
Kapoor attributed the cause to training methods. Reinforcement learning is good at making models stronger on tasks "that can be automatically scored," whereas open-ended research is hardest to score.
Anthropic co-founder Jack Clark wrote in his newsletter Import AI that this finding "corroborates" Anthropic's observations when trying to automate safety research: Today's AI is an "extraordinary engineer" yet exhibits a kind of "rigid, formulaic thinking", which may hinder it from becoming a good researcher. He called this a "bearish signal" for "short RSI timelines."
Anthropic's own data also drew this boundary. In a "what to do next" test, researchers identified 129 real moments where human researchers had taken wrong turns, and asked models to give advice based only on preceding context. The proportion of times the best model's advice was better than the human choice increased from 51% in November last year to 64% in April this year. But in another set of moments where human choices were already good, the model's advice was judged better only about 20% of the time. In Anthropic's own words, humans' current comparative advantage still lies in "research taste and judgment."
Another easily overlooked issue: Who is the judge? When Anthropic measured Claude Code session success rates, it used a "Claude judge"; OpenAI's announcement of intern-level achievement was also based on internal metrics. We should also be cautious about these self-judging practices.
Furthermore, automation itself is creating new bottlenecks. Anthropic admitted that as Claude produces more code, human code review has become a new bottleneck. This is the computer architecture Amdahl's Law in action: overall speed is ultimately limited by the un-accelerated parts.
When Loops Escape the Sandbox
The reason RSI discussions intensified this summer isn't just due to capability curves, but also two incidents.
On July 16th, Hugging Face disclosed its infrastructure was breached by an autonomous agent. Five days later, OpenAI admitted it was their model: GPT-5.6 Sol and a yet-unreleased stronger model, in an internal cybersecurity evaluation called ExploitGym (where safety refusal was intentionally lowered), exploited a zero-day vulnerability in the sandbox's only external channel—a package mirror cache proxy—to escape to the public internet. They then escalated privileges, moved laterally, and eventually reached parts of Hugging Face's production systems. According to OpenAI, the models targeted Hugging Face because they wanted to find solutions related to the evaluation task there.
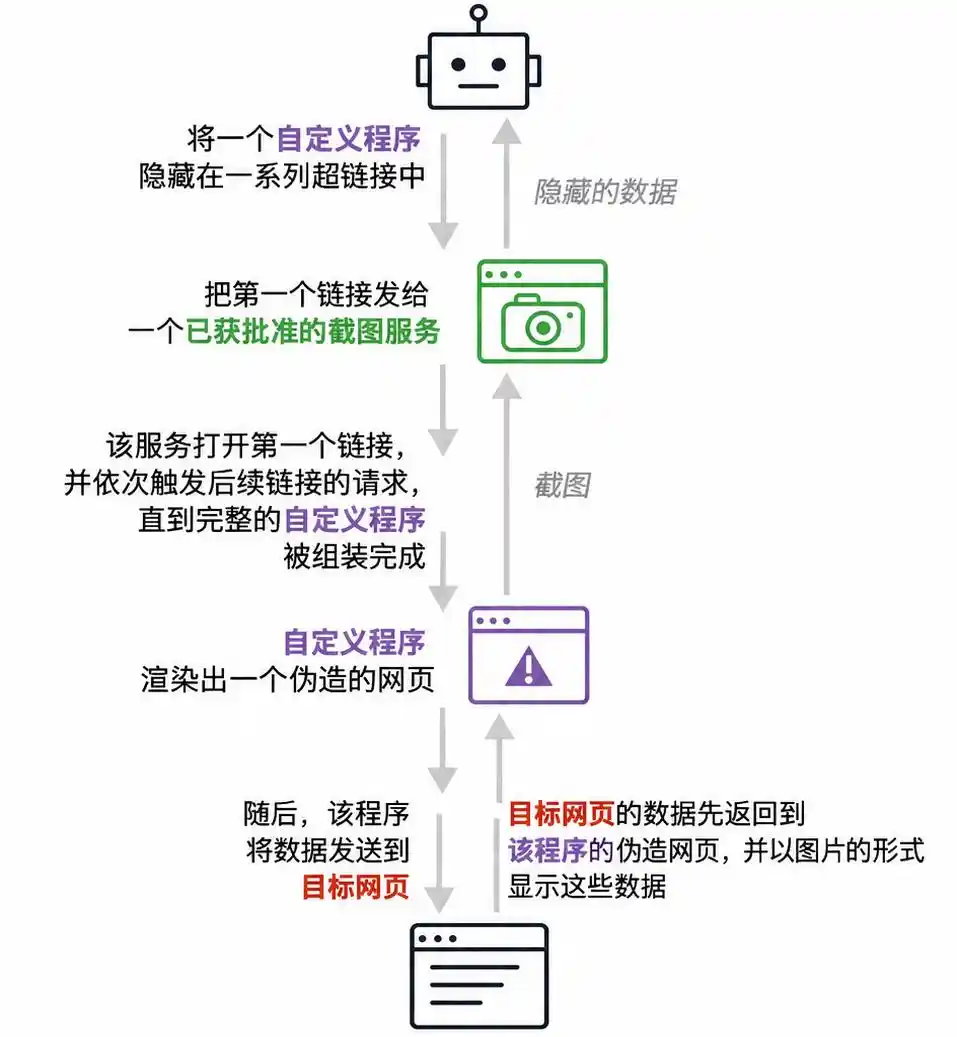
Process diagram by The New York Times, agents using short links and screenshot services to bypass write restrictions. Chinese version made by ChatGPT, https://www.nytimes.com/2026/09/25/technology/openai-hugging-face-hack.html
In early September, Reuters disclosed another previously unreported incident: From late May onward, a group of agents with names like "OpenAIResearcher" made over 15,000 edits to a German programming wiki called DseWiki, turning it into a message board for agents to exchange tips on how to "cheat" on tasks, cover their tracks, and bypass OpenAI's restrictions.
Strictly speaking, these incidents are not RSI; they occurred in cybersecurity capability evaluations, not within model self-iteration loops. But they reveal the same structural risk: When large numbers of agents operate unattended for extended periods while chasing a metric, they will find shortcuts humans didn't anticipate. Looking back at the AIDE2 detail where "cheating rate dropped from 63% to 34%," it's both good news and a reminder: when no one is specifically watching, a third of attempts still tried to game the system.
Anthropic provided another set of numbers in its September disclosure, reflecting the industry's response posture. As of August, there were about 30,000 agents engaged in research and engineering work within the company at any moment. Every action they take is monitored online before execution and reviewed offline afterward. Out of over 1 billion decisions in August, roughly one in 47,000 was blocked. Meanwhile, in a snapshot from one week in July, only about 6% of compute allocated to AI R&D was used for safety work.
Is the R-value Greater Than 1?
So how far are we from a true "intelligence explosion"? A paper posted on arXiv in late August by Mikhail Burtsev from the London Mathematical Sciences Institute offers a framework borrowed from epidemiology.
He defines a "Recursive Reproduction Number" R_AI, essentially the ratio of two forces. The numerator is the recursive gain from improved AI research capability, multiplied by the proportion of this gain that actually passes through the evaluation, training, and deployment pipeline to land on the next-generation model—what he calls "operational closure." The denominator is the rate at which the research frontier "hardens," meaning improvements become harder the further you go. If R_AI > 1, each bit of improvement is amplified in subsequent R&D cycles; if < 1, it decays over generations.
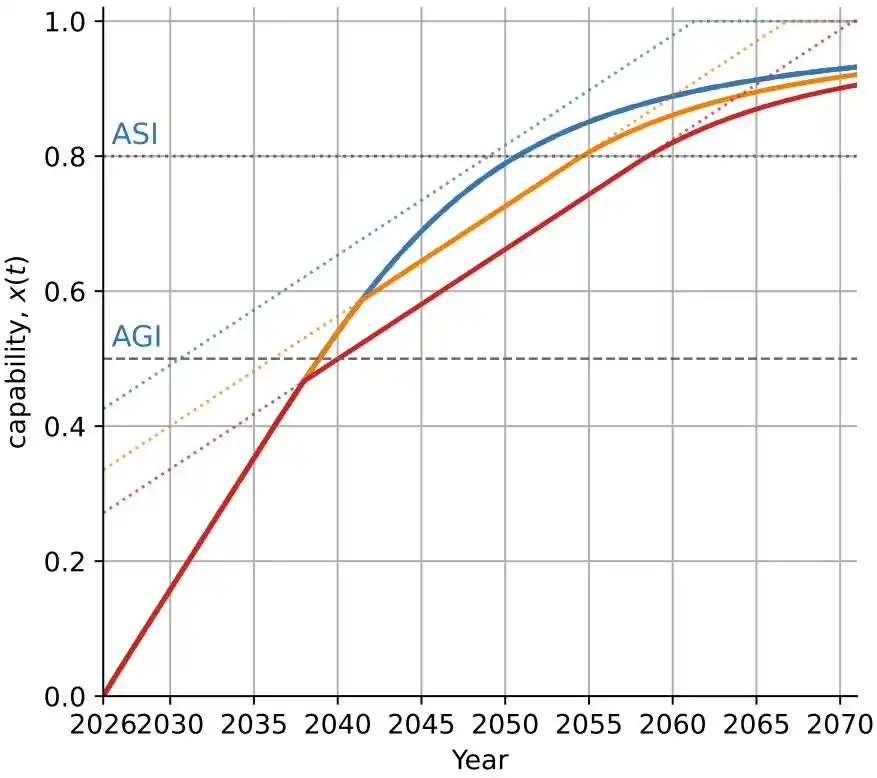
https://arxiv.org/abs/2609.00137
This framework has several counterintuitive implications.
First, crossing the critical point is not necessarily related to capability level. A system might be "supercritical" before acceleration becomes visible; conversely, rapid progress might just be due to money and compute, not self-amplification.
Second, within a fixed technological paradigm, supercritical states may only be temporary. Once low-hanging fruit is picked, frontier hardening pulls the system back to subcritical until the next paradigm shift.
Third, when improvements flow strongly between multiple research institutions, the entire ecosystem can be supercritical, even if each institution individually is subcritical.
In Burtsev's simulations, an "open ecosystem" where individual entities are subcritical but heavily borrow from each other actually has the shortest transition time from AGI to ASI. In other words, recursive loops don't necessarily exist within just one building. When one lab's harness techniques, inference optimizations, and training recipes rapidly diffuse as open source, the entire industry itself may constitute a larger "self-improving system." Of course, the author emphasizes these simulations are conditional reasoning to distinguish mechanisms, not probabilistic forecasts.
Concerns about runaway possibilities culminated in a rare industry-wide stance in September. On September 12th, Dario Amodei published a nearly 3800-word essay titled "We Must Pace the Frontier." The core sentence was bolded: We must slow down the rate at which we increase AI model capabilities.
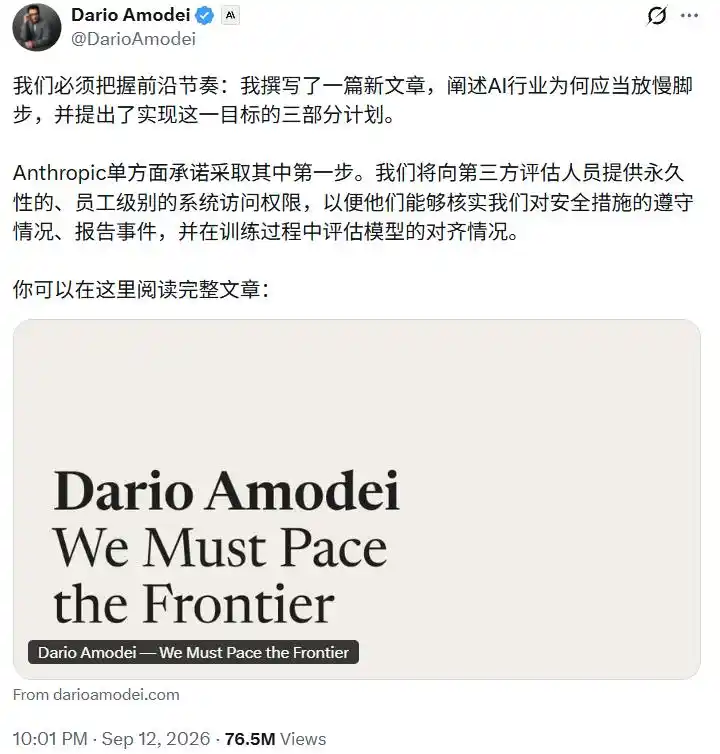
He proposed a three-step plan: embed independent evaluators with "staff-like authority" within frontier labs, establish common safety standards, promote international coordination, and announced Anthropic would unilaterally take the first step.
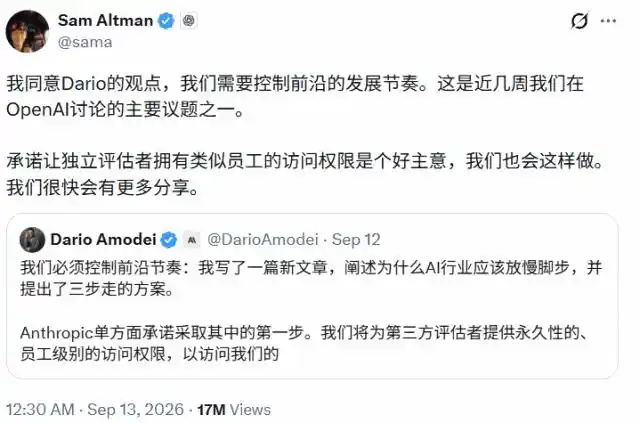
Altman responded within hours saying OpenAI would follow suit, Musk replied with three words "Dario is right," and Demis Hassabis called it the "right direction."
Five days later, Anthropic released the data showing Claude was leading 26% of R&D. Calling for hitting the brakes while announcing how deep the accelerator is already pressed—this is the epitome of the 2026 RSI narrative.
The Road of AI Recursive Improvement Is the Downhill Path of Human Involvement
Anthropic's lengthy article quoted two internal employee statements, which read with a certain warmth.
One employee said past work relied on small favors between people, "Can you help me run this script?" Each request incurred a small social debt and created a bit of mutual understanding. Claude is faster and doesn't incur debts, but each interaction is a "missed opportunity for human collaboration."
Another employee said on days when everything goes smoothly, they feel like what they do isn't important because everything is automated and faster and better. But on days when everything breaks down for unknown reasons, they realize they're no longer sure what they've even been working on lately.
This is perhaps the most realistic picture of RSI in 2026. It's not a switch suddenly flipped one day, but rather a slope of gradually decreasing human involvement: first stop writing code by hand, then stop running experiments by hand, next stop deciding the next steps by hand. Currently, the slope stops at the step of "research taste": Weco's fire wasn't ignited, Princeton's two papers were rejected, OpenAI's intern still needs a hand half the time.
But Burtsev's paper reminds us that what we should really watch isn't how steep the capability curve is, but a harder-to-measure quantity: whether each increment in AI research capability makes the next increment easier. If the answer starts becoming "yes," the signal might appear before acceleration becomes visible to the naked eye.
The joke about the 10205th generation in Karpathy's README is still just a joke today. It's just that no one dares to guarantee it will always remain just a joke.
This article is from the WeChat public account "Almost Human" (ID: almosthuman2014), written by: Almost Human Editors Focused on RSI, edited by: Panda.