From 'Capable of Execution' to 'Capable of Steerage': What Do Long-Horizon Agents Still Lack?
In the rapidly evolving field of Agents, Harness technology has already enabled large language models to interact with the real world, allowing them to call tools, modify code, and run experiments. However, when tasks extend from tens of minutes to several days, systems still require a human to remain at the screen long-term, judging where to go next.
The key bottleneck is not merely insufficient model capabilities, but that most existing Agents have automated "execution" but not truly automated the "steering" above execution. Harness grants the model the ability to act, while humans grant the model decision-making. Once the human leaves, the project stops. Moreover, without dense reward feedback, the Agent's execution and reactions can appear slow and clumsy.
To address this issue, Microsoft, Shanghai Jiao Tong University, and other institutions have open-sourced Argus, a general Agent reasoning runtime for long-horizon research tasks, and released a technical report. Through designs such as evidence-driven operation, self-evolution, multi-agent collaboration, and decoupling of core and vertical domains, the system enables Agents to extend research over multiple domains for days, even without dense standard feedback.
The report covers 27 Campaigns and 1,548 hours of wall-clock time. On average, it requested human intervention once every 40.7 hours; the working duty cycle was 95.1% to 98.7%. What Argus delivers is not just high benchmark scores, but a complete production-grade portfolio of results. The team presents achievements across a wide range of tasks including AI4AI, GPU Kernel, model training, AI4Science, chip design, AI4math, and AI4System, demonstrating Argus's generality and real research-grade intelligence.
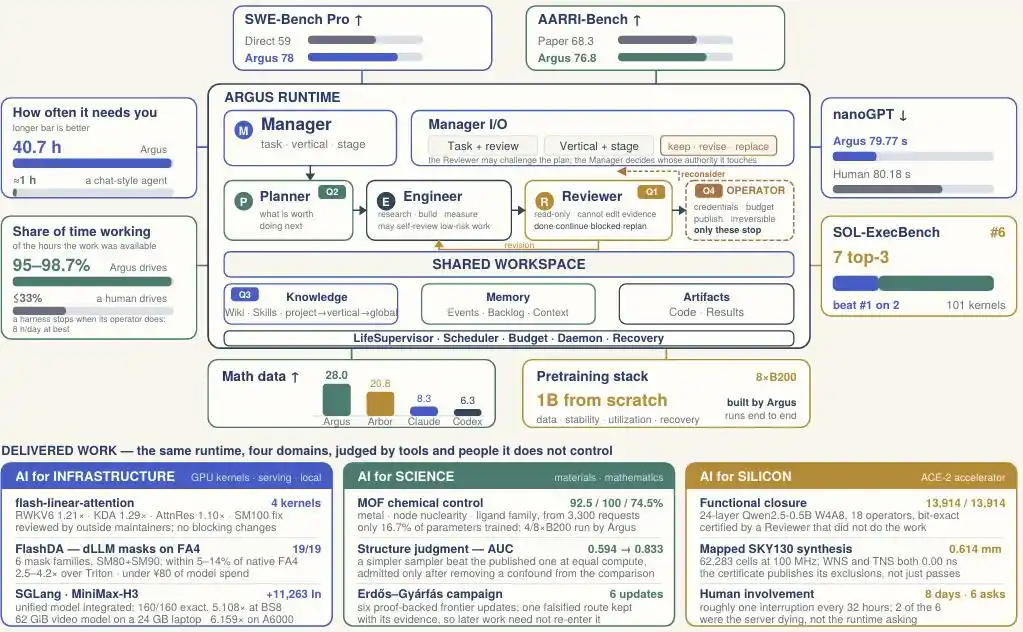
Figure 1: Overview of Argus runtime, capability benchmarks, and delivered results.
- Paper Title: Argus: Who Drives the Harness for Days?
- Paper: https://arxiv.org/abs/2608.05144
- Code: https://github.com/lbx154/Argus
- Project Homepage: https://argusbot.cn/
- Project Results Repository: https://github.com/Argus-AiTeam
- Project Math Problem Solving Live Stream: https://open.argusbot.cn/#counterexample-live
01
Shifting from Goal-Driven to Evidence-Driven:
Who Decides the Agent's Next Step?
Over the past two years, major progress in Agent engineering has centered on Harness: using the analogy of self-driving FSD, the model is like the engine, Harness is like the drivetrain, but the one truly deciding where the vehicle goes is still the person sitting at the screen. For short tasks, like standard automated parking, the task itself can still provide clear feedback; once tasks extend over days, research problems often lack both stable rewards and clearly defined goals from the start. Existing Agents thus reveal the true bottleneck: they can execute, but they still cannot make continuous judgments under uncertainty.
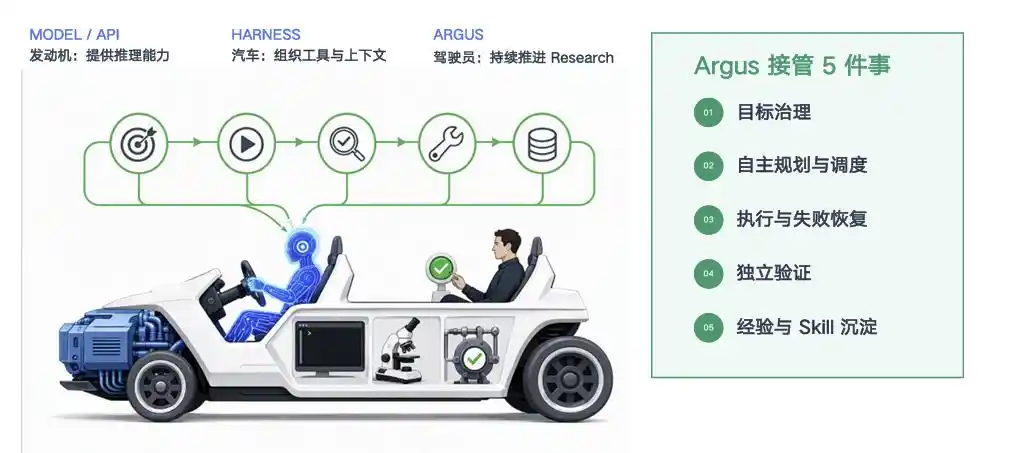
Figure 2: Argus transforms the human role from the ongoing driver's seat to a co-pilot by achieving auto-research for autonomous scientific inquiry.
Argus refers to the previously unautomated position above Harness as the Driver. Its job is to keep steering based on evidence even when plans conflict with reality. The goal written at the start of research is merely the initial hypothesis at the information-poorest stage; if the Agent can only chase preset endpoints in a Goal-Driven manner, or even repeatedly waste tokens on impossible goals, it leads to goal fixation. Evidence-Driven, however, inverts the control logic: the next step is determined by existing evidence, not by the initial hypothesis of the plan. All results during operation are valid evidence that can change the route; the system is precisely driven by evidence. Specifically, the Driver needs to repeatedly answer the following four questions based on current evidence:
1. Is this work already complete, and is the quality sufficient?
2. Based on current evidence, what is the most worthwhile thing to do next?
3. How should the experience gained in this round alter the system's subsequent behavior?
4. Does the remaining problem involve decisions that only humans can make?
02
Building a General, Customizable Long-Horizon Runtime
Argus organizes long-term projects into persistent Campaigns, which are then broken down into a series of well-bounded Missions. Its fundamental loop is: Manager → Planner → Engineer ⇄ Reviewer → Manager:
Using OpenAI Codex's /goal mode as a reference helps clarify Argus's design orientation. /goal extends a single agent's single-turn loop into a persistent loop with a goal state; Argus organizes research projects as a multi-role, multi-harness, knowledge-persisting long-horizon runtime. The former answers "how to keep the agent from stopping," the latter answers "once the agent doesn't stop, how to work effectively." This is precisely the structural difference at the runtime level corresponding to the shift from Goal-Driven to Evidence-Driven.
1. Manager controls phase transitions, process approvals, and global strategy;
2. Planner formulates specific tasks based on current evidence;
3. Engineer enters real codebases, experiments, and executes;
4. Reviewer independently audits artifacts, evaluates novelty and effectiveness, reports to the Manager, or sends tasks back to the Engineer.
The key here is not multi-role itself, but splitting the context—multiple roles collaborate to prevent the agent from becoming a simple local hill climber. Each role has its own unique context but shares a workspace, avoiding entrusting planning, execution, and validation entirely to a single agent, improving token efficiency. This also allows Argus to simultaneously enable different harnesses like Pi, Codex, Claude Code, DeepSeek Harness etc., within a single task, ensuring high customizability.
The system saves a complete set of artifacts; only experiences that pass the evidence threshold enter the Wiki and Skill, and are reused in subsequent tasks within Project, Vertical, or Global scopes.
Simultaneously, Core and Vertical remain decoupled: Core is responsible for role permissions, evidence submission, and human boundaries. Vertical, defined by domain experts, determines what constitutes valid evidence in tasks like mathematics, GPU, materials, etc., along with related human skills and knowledge. Vertical can significantly improve the delivery quality of research tasks and also provides an interface for human experts and agents to co-evolve and customize workflows.
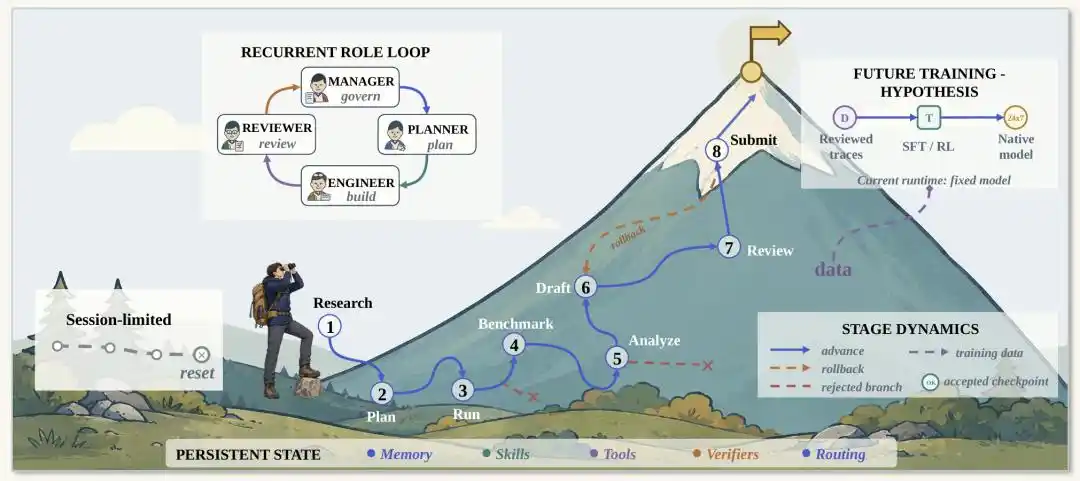
Figure 3: Argus's long-horizon runtime mechanism. Four role types cycle around persistent state; Campaigns can advance or roll back between eight research phases.
03
After 1,548 Hours, What Has Argus Left Behind?
What truly determines the validity of a long-horizon Agent is whether time can be translated into genuine research outcomes. Within less than a month of its open-source release, Argus has already made outstanding contributions in infrastructure, materials, chips, mathematics, and AI system research. The team is also the first to publish complete end-to-end logs for solving mathematical conjecture screening, opening all running trajectory sessions, etc. The following is a summary of Argus's achievements since its open-source release:
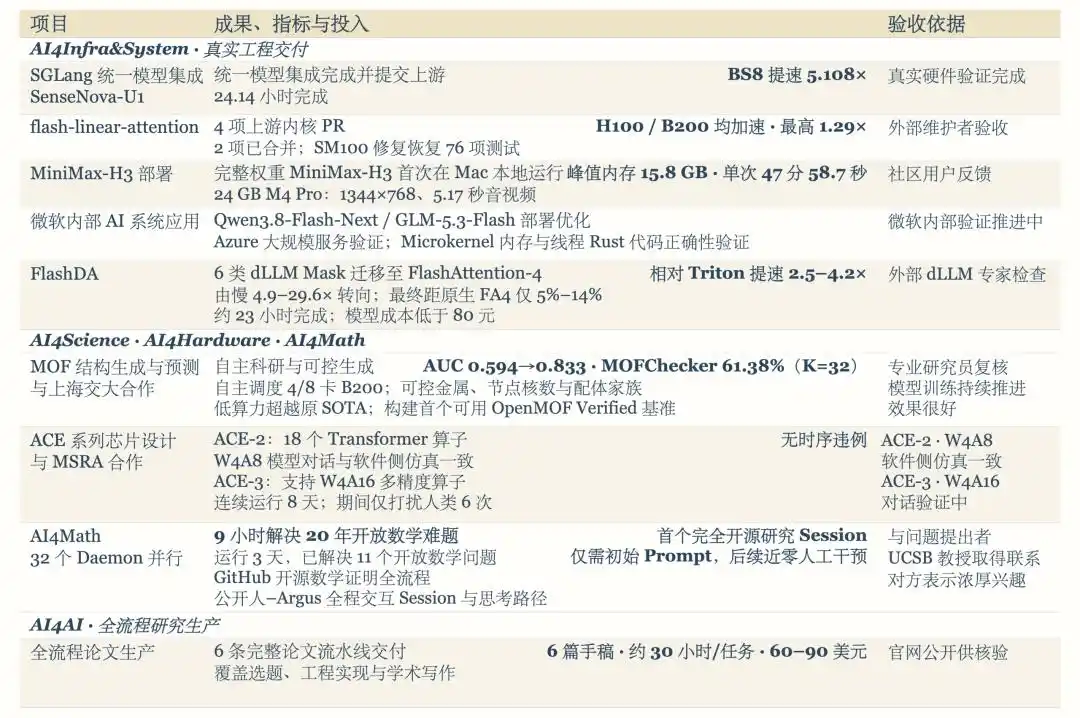
Figure 4: Argus's representative research results, key metrics, and acceptance criteria.
As shown in the table above, Argus first translated continuous operation into verifiable real-world deliverables in AI4System & Infra, achieving the first step from automated execution to autonomous research with clear engineering outcomes. Subsequently, tasks expanded from AI infrastructure to AI4Science, AI4Hardware, and AI4Math, and the evaluation criteria shifted accordingly from "whether the assigned task is completed" to "whether unresolved real-world research problems can be explored." Auto-research thus progressed further from automated delivery to automated exploration. Building on this, Argus extended from point achievements to complete research workflows in the AI4AI direction, continuously driving task progression with evidence without requiring humans to remain at the screen, forming a progressive path from real-world delivery, cross-domain exploration, to full-process autonomous research.
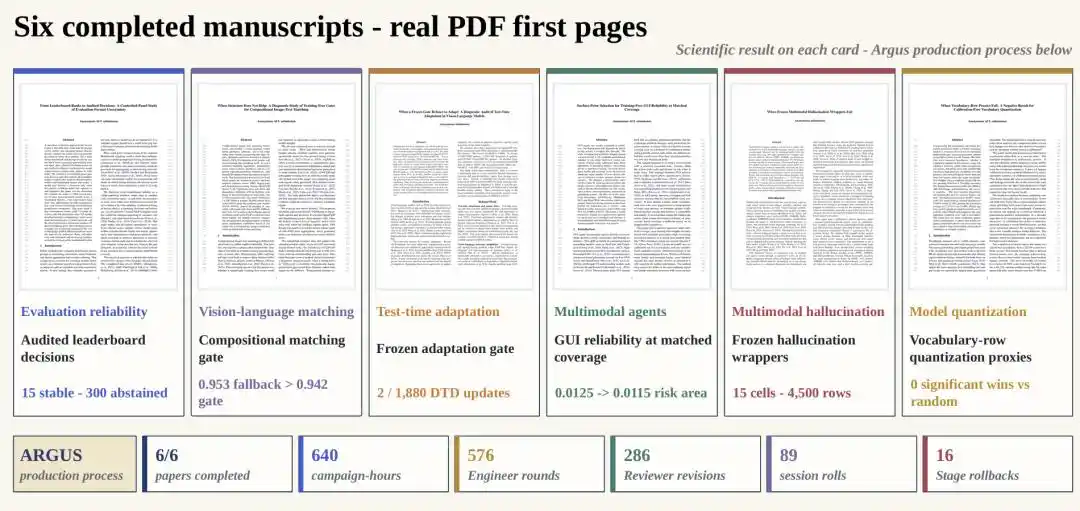
Figure 5: Argus's delivery results in the full-process paper production.
All the above results were achieved within 1 month. Stringing these outcomes together, Argus represents a gradually deepening value chain: the object of automation expands from a single execution to evidence-driven research progression, greatly accelerating research progress. This is the most direct answer to "who steers the Agent after the human leaves the screen."
Conclusion
After the Screen Goes Dark, the Project Doesn't Reset to Zero
Long-horizon intelligence is about transforming tokens into intelligence, then using that intelligence to continuously advance a research project, generating real value. Argus organizes previously disjointed model calls into a continuously operating research system, letting Evidence-Driven control the direction, and then solidifying experience into capability through self-evolution.
Argus demonstrates not just a longer-running Agent, but a new way of organizing research: Harness addresses how the model acts, the Driver determines how the system continuously moves forward, and research speed is no longer constrained by human work and leisure hours. This may signal the arrival of an era of accelerated research. The screen can go dark, but the research continues.
About the Authors
Argus was led by researchers from Microsoft and Shanghai Jiao Tong University, with contributions from researchers at multiple universities.
This article is from the WeChat public account "机器之心" (Almost Human)