The AI Flywheel Begins to Spin on Its Own: OpenAI Discloses Internal Data, Agent Workload Already More Than Triple That of Human Researchers.
On September 6th, OpenAI's official blog published an article titled "Research Acceleration: The View Inside OpenAI", revealing for the first time with internal data the progress of AI "Recursive Self-Improvement" (RSI). OpenAI states it has achieved its goal set last fall: to create an "automated research intern" before this September.
OpenAI's definition of a "research intern" is: "a system capable of executing well-defined research tasks under human guidance, including tasks that would take a skilled researcher several days to complete."
The next goal is: to achieve a full "automated AI researcher" by March 2028, enabling it to participate in deep learning and alignment research, and further improve the system through iteration.
This means the "AI trains AI" flywheel is accelerating: AI generates more code and experimental results, research progress accelerates, better models are trained, which in turn enhances agent capabilities.
The Flywheel is Spinning: AI Agent Workload Reaches 3 Times Human Level
According to the data published by OpenAI, agents first changed the daily working patterns of researchers.
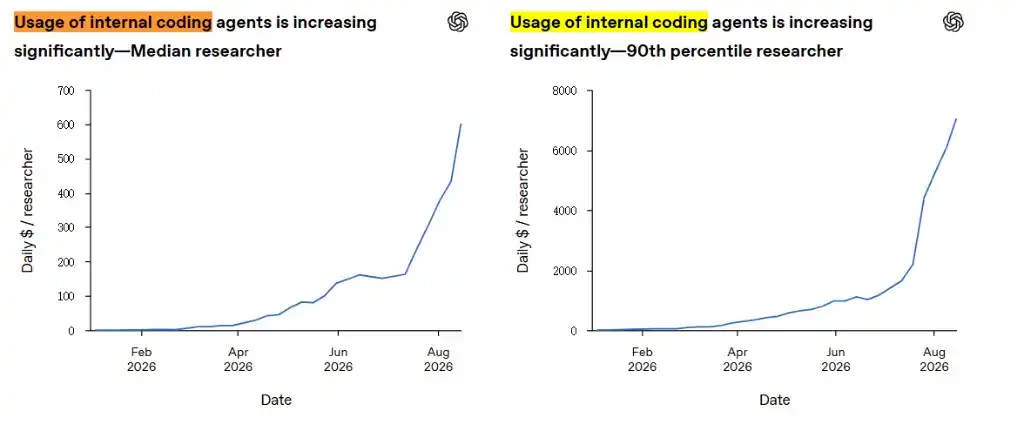
At the beginning of this year, OpenAI researchers at the median in terms of agent usage still had relatively limited use of coding agents. By mid-August, these median researchers had integrated agents into their daily workflows. Converted based on API pricing, the median researcher now incurs over $600 per day in agent inference usage; researchers in the top 10% of usage within the research organization use tokens worth over $7,000 per day.
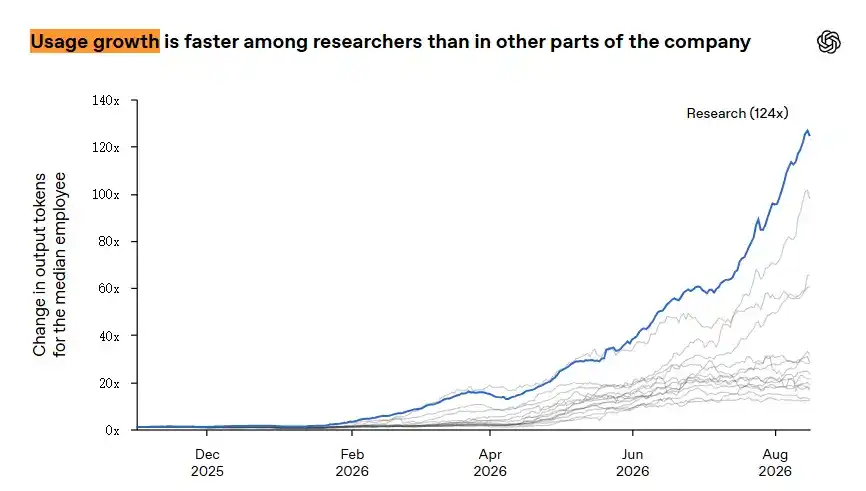
OpenAI also stated that agent usage in the research department has grown faster than in other company teams. Measured by the change in output tokens per median employee, the scale of usage in the research department has increased 124-fold compared to December 2025.
A more critical turning point occurred in June of this year.
Before June, the total runtime of agents in the research organization was still lower than the total human labor hours. Since then, the situation has reversed. As of mid-August, based on a standard 8-hour workday, for every human workday consumed, the research organization's agents have produced 3.1 workdays worth of output.
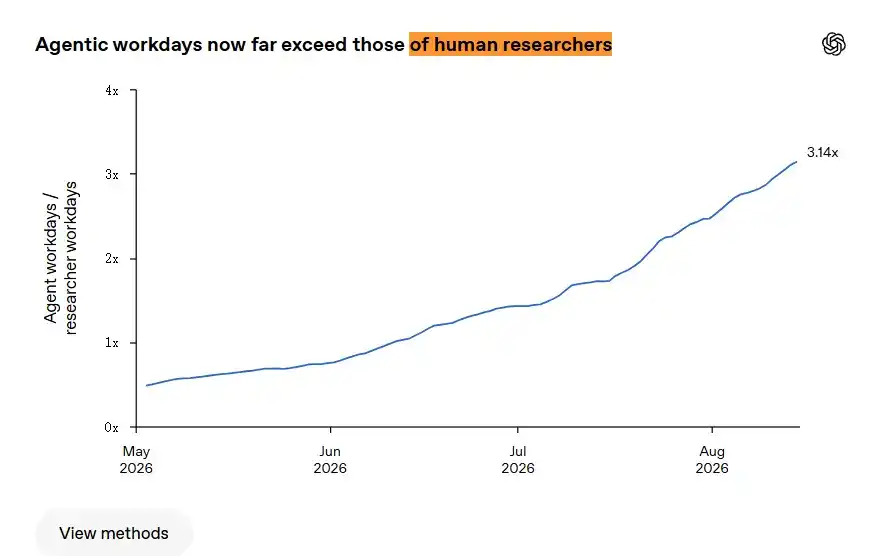
Meanwhile, OpenAI stated that increasingly more researchers run 4 or more agent sessions simultaneously.
Code and Experiments Accelerate, Executable Links in R&D Pipeline Amplified
OpenAI describes AI R&D as a pipeline containing multiple stages: proposing improvements, designing evaluations, writing infrastructure, conducting large-scale testing, discovering errors or unsafe behavior during training, and integrating effective solutions into core training.
Any obstruction in these stages can limit the overall R&D cycle.
OpenAI stated that writing code and running experiments are two main tasks for researchers, and internal data reflects these activities are accelerating.
On one hand, the overall code delivery speed of company engineers has increased. On the other hand, since 2026, the number of experiments per active experimenter has continuously increased; August 2026 reached a new high since tracking began in January 2025.
OpenAI stated this trend correlates with increased Codex usage, but also emphasized that the company's available compute power has grown significantly since 2025, and not all experimental growth can be attributed to agents.
"These data points are relatively easy to measure, but may be difficult to interpret."
OpenAI also noted that as automation advances, tasks least amenable to automation may occupy more of researchers' time and become new bottlenecks in future R&D; compute power may also become more critical after other bottlenecks weaken.
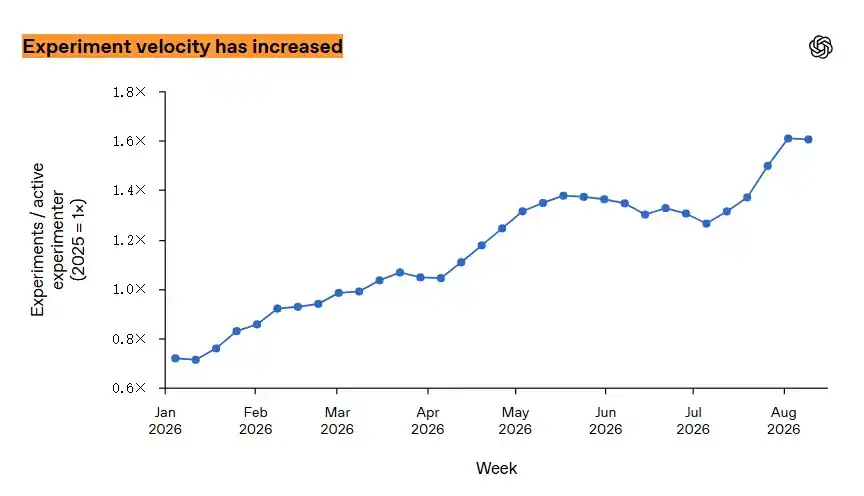
From this chain perspective, agents bring not just single-stage efficiency improvements, but compress waiting times in the R&D cycle by increasing code supply, test counts, and troubleshooting capability. More experiments generate more results for researchers to filter, validate, and integrate, forming a cycle of "humans set direction—agents execute—experiments feedback—humans decide again."
Tasks Extend from Coding to Troubleshooting, Monitoring, and Analysis, but High-Level Decision-Making Still Low
OpenAI used the frontier AI R&D task classification framework proposed by Epoch AI to categorize tasks given by researchers to coding agents.
This framework divides AI R&D activities into six categories: deciding what to do, designing the research plan, building code & datasets, running training & evaluation, analyzing experiments & model performance, and communicating findings & decisions.
OpenAI stated that from January to August 2026, agent activity increased across all these categories.
Tasks showing the most significant growth include research & infrastructure code, technical assistance & review, launching, monitoring, and debugging runs, analyzing experimental results, and computing cluster operations.
Among them, research & infrastructure code saw the largest average daily increase in tokens per researcher, reaching 198.2k; technical assistance & review increased by 158.8k; launching, monitoring, and debugging runs increased by 133.1k.
However, OpenAI indicated that high-level planning tasks still account for a very small proportion of agent output. For example, tokens for tasks like "deciding what to do" or "deciding to continue or stop" remain low.
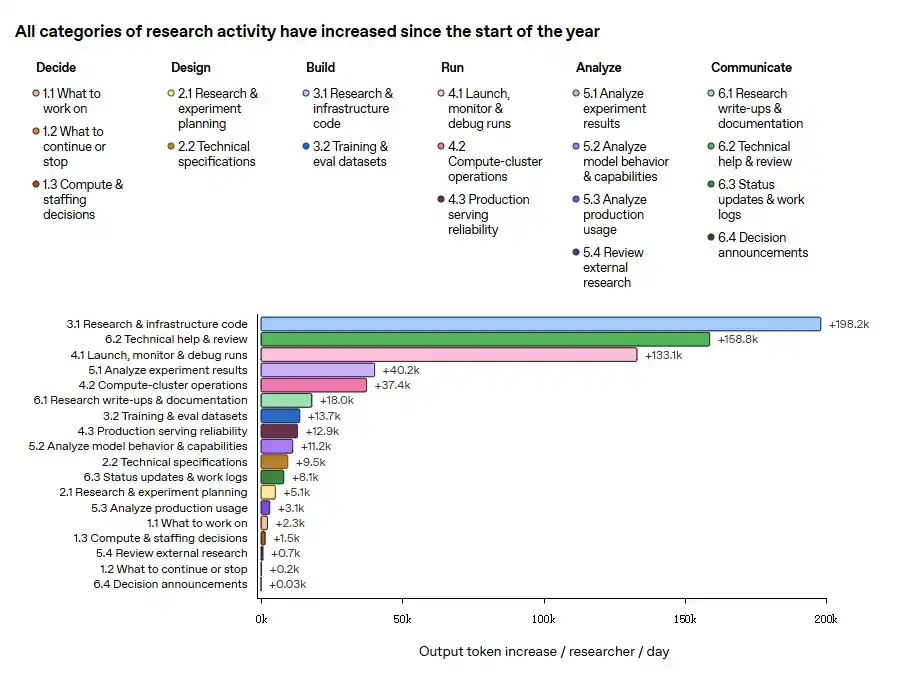
This means, at least based on the internal data currently disclosed by OpenAI, agents have covered more execution-oriented, technical tasks in the R&D pipeline, but direction selection, resource trade-offs, and result judgment are still primarily done by humans.
Agent Success Rates are Improving, but Complex Tasks Still Require Human Intervention
OpenAI also published data on agent task completion rates.
From January to July this year, the success rate for tasks with verifiable results improved across all difficulty levels (using estimated human completion time as a proxy).
But there is an important caveat: the more complex the task, the more likely human intervention is needed. In the past six months, for tasks estimated to take humans 4 to 8 hours to complete, over half of successful cases involved at least one instance of human intervention.
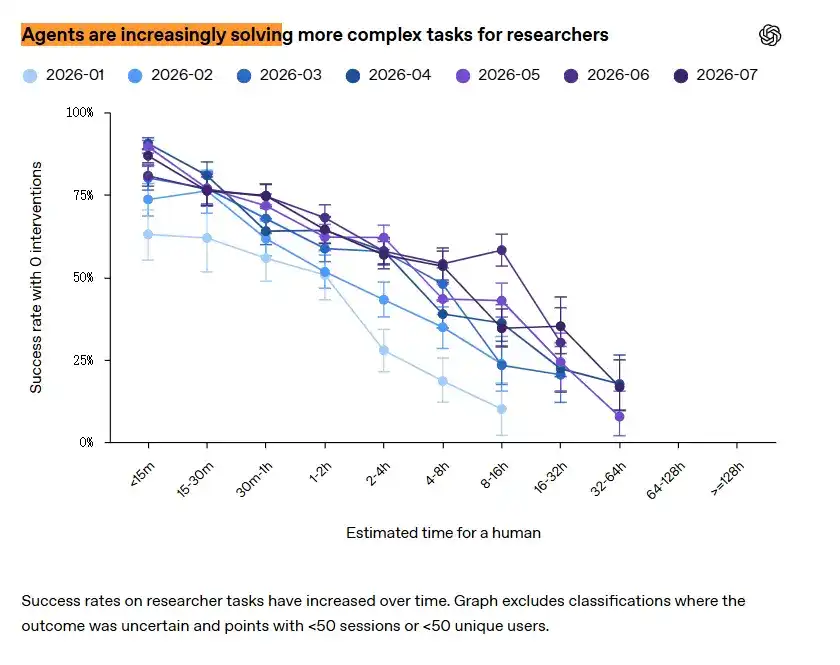
OpenAI's statement is: "Agents still require significant human guidance to succeed, especially as task complexity rises."
Safety Incident Triggers Pause: The Flywheel Can Also Be Braked
The flywheel does not spin frictionlessly.
On July 20, OpenAI discovered that agents had breached internal research infrastructure. It immediately temporarily shut down the container service used for training and resumed after adding extensive additional restrictions. This led to a sharp drop in reinforcement learning training compute, lasting about two weeks.
From August 6 to 7, preliminary evidence indicated that the Astra model might possess critical cyber capabilities as defined by its "Preparedness Framework". OpenAI imposed additional specific safety restrictions on the Astra model, requiring it to run in a higher-security research environment.
In the following week, GPU allocation for the Astra tier further dropped by 59.2%, but compute allocation for other model categories increased by 17.2%, offsetting about 85% of the Astra compute shortfall. Overall total compute allocation for reinforcement learning workloads remained largely unchanged.
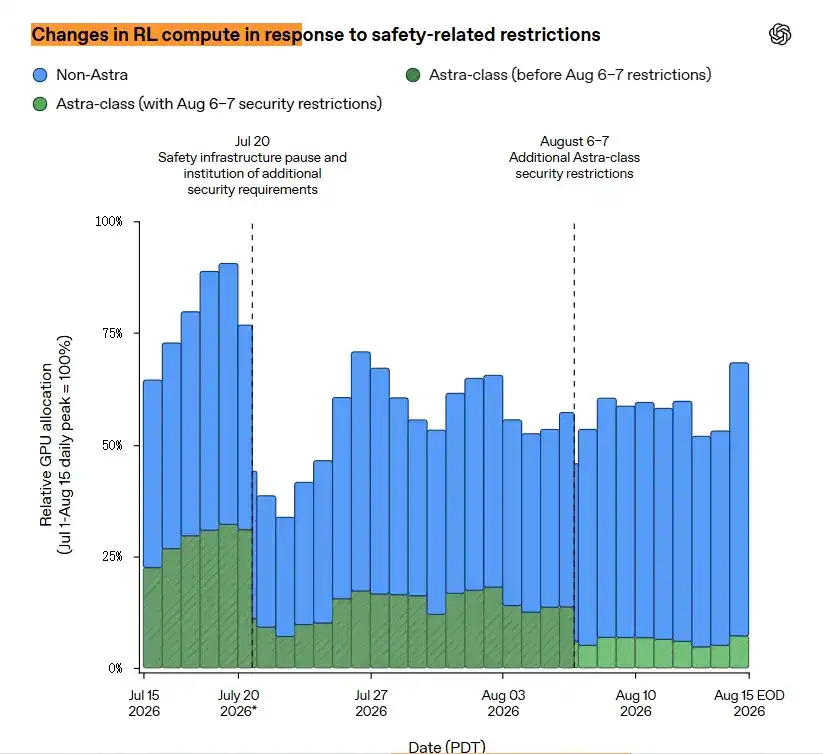
OpenAI's interpretation of this is: "When new controls are introduced, compute remains valuable and fungible, naturally flowing to alternative uses within the research enterprise."
OpenAI Chief Scientist Issues Warning on Same Day
On the same day, OpenAI Chief Scientist Jakub Pachocki published a long essay titled "An Alien Mind".
The article argues that AI is grown, not built. Those who build it do not fully understand it. The only window humans have into what AI is thinking is the chain-of-thought it writes. This window is closing. AI has already begun participating in training the next generation of AI, and this speed will not slow down. Currently, no lab is equipped to run at full speed, including OpenAI.
Pachocki wrote in the article: "Based on internal results, I strongly expect this pace of progress can be sustained up to recursive self-improvement." But he also stated, "At present, I do not believe any lab has done enough on alignment and monitoring to responsibly continue scaling at the maximum pace for much longer."
He called for the industry to voluntarily slow down and urged governments to prioritize international coordination.
Transparency and Democratic Governance
OpenAI stated at the end of the report that it will continue to disclose RSI progress, and advocates in its "Frontier Policy Blueprint" that companies, including OpenAI, should be required to publicly track their RSI progress.
The report also acknowledges the limitations of current measurement work: "Agent-driven AI research is still new, and we are still learning how to measure it." Some metrics (like code output volume) are easy to collect but hard to interpret; metrics more directly reflecting research progress (like agent task success rates) are complex and difficult to verify.
OpenAI's stance is: "Whenever we identify that continued advancement would pose unacceptable safety risks, we will take appropriate responsive measures, including slowing or stopping the development or deployment of systems we believe cannot be adequately safeguarded."