OpenAI's fastest-ever model is dead.
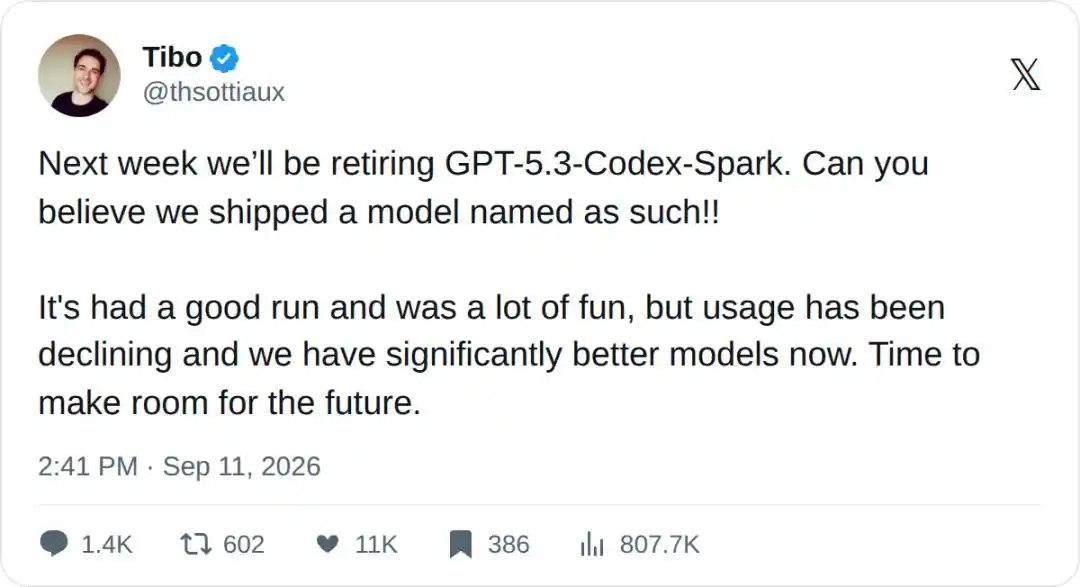
Codex lead Tibo posted that GPT-5.3-Codex-Spark is retiring next week.
With 1200 tokens per second, OpenAI's first model to escape NVIDIA, the first delivery from the 750-megawatt Cerebras mega-deal—it survived only 7 months from launch to shutdown.
Tibo gave a simple reason: usage has been consistently dropping, and they already have clearly better models in hand. "It's time to make room for the future."
Then, he added another jab in the comments, "I can't believe we ever released a model with such a long name!!"
At the Farewell, Everyone Only Cared About the 'Backup Quota'
Spark went quietly, even a bit awkwardly.
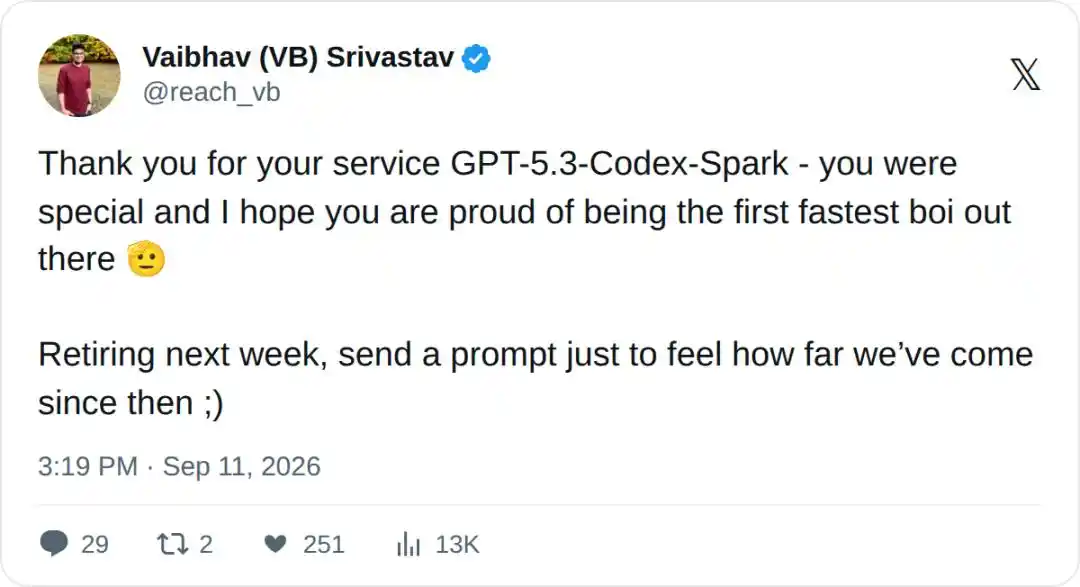
Hugging Face's Vaibhav Srivastav tried to leave a touch of warmth in the comments.
Thanks for your service, you were special, hope you're proud of being the first 'fastest kid on the block'. Before you retire next week, send one last prompt, feel how far we've come since then.
The top comment that followed immediately changed the tone sharply.
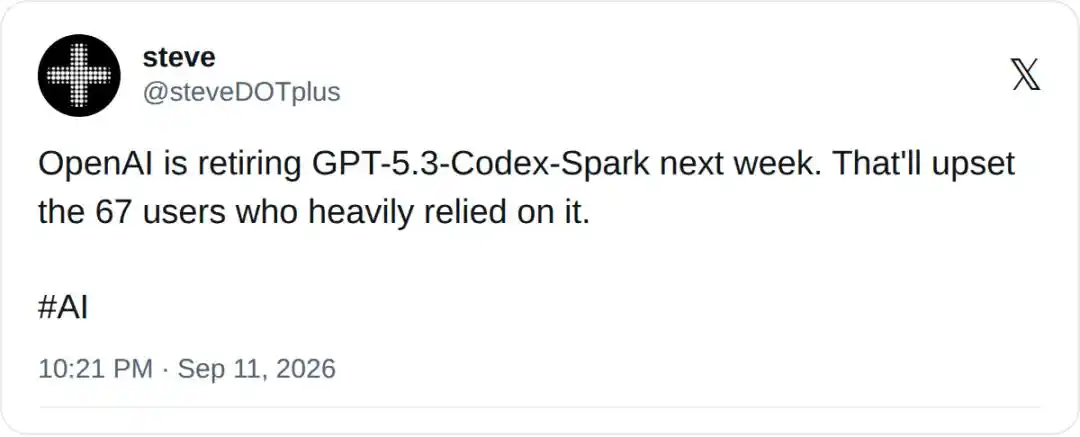
So what was it actually used for? I was just discussing this with a colleague the other day.
OpenAI is retiring Codex-Spark, the remaining 67 heavy users must be heartbroken.
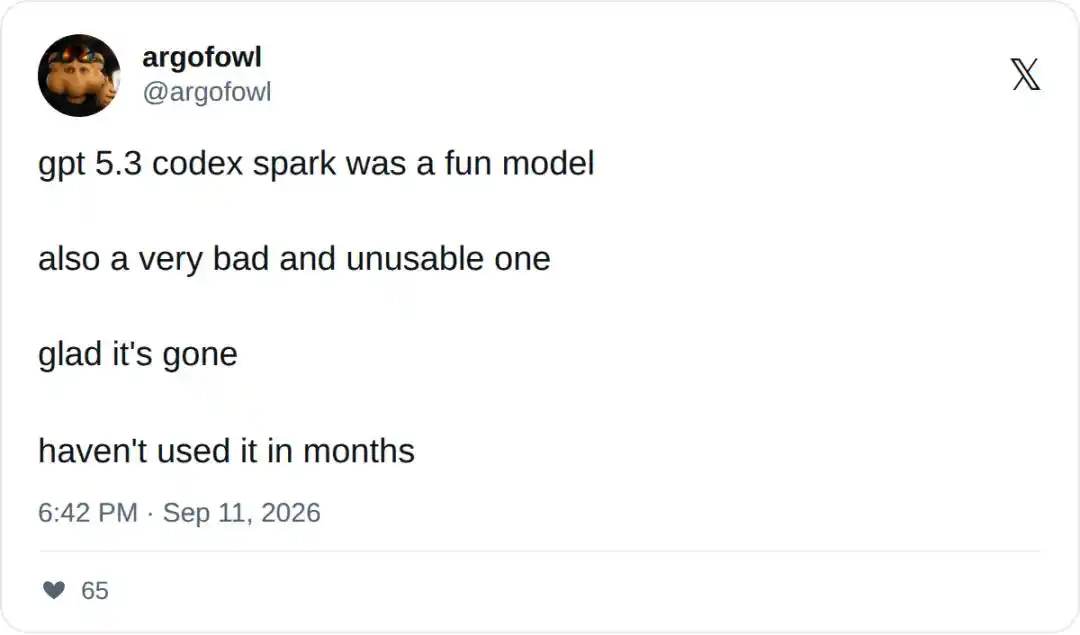
The more fatal review came from developer argofowl, "Spark was a fun model, and also an extremely terrible, completely unusable model. Glad it's gone, I haven't touched it in months."
Another developer mentioned that in several sizable projects, they barely used Spark. Even basic tasks like understanding project context or analyzing logs would quickly fill the context window, forcing them to start a new conversation.
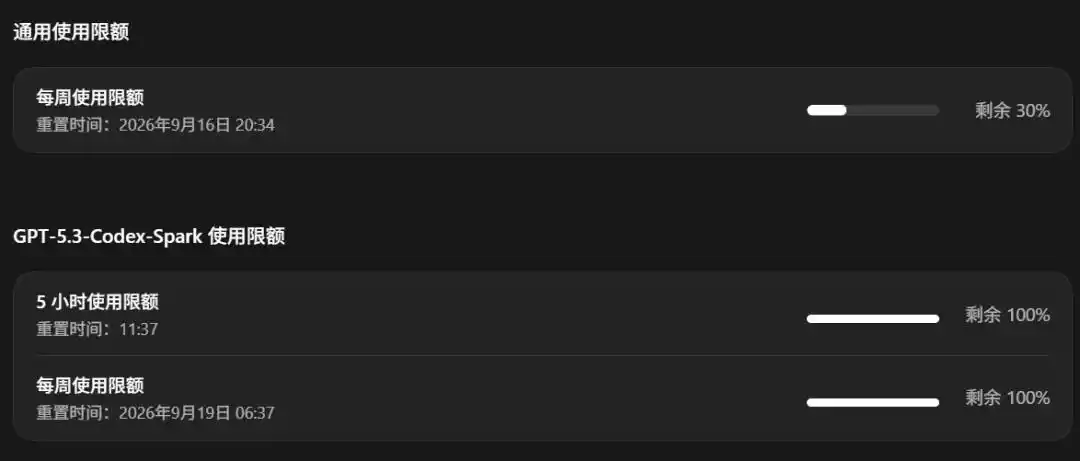
In fact, those who expressed a slight regret about Spark's retirement weren't mourning the model itself, but its attached independent quota.
Well-known developer Chubby frankly said they wanted a "GPT-6-Spark" because Spark had a separate package that didn't count against the main quota.
With Astra quotas extremely tight now, many developers used Spark as a "reserve tank" to tide them over after their main quota ran out.
The 'Future' From 7 Months Ago, Defeated by 'Dumbing Down for Speed'
Rewind to February 12th this year, the day Spark launched with great fanfare.
It was OpenAI's first model specifically designed for real-time programming, with 128k context, generating over 1000 tokens per second.
According to official numbers, round-trip overhead between client and server was reduced by 80%, processing cost per token by 30%, and first token latency cut in half.
Code didn't pop out line by line anymore, but poured onto the screen in whole blocks.
The earliest developers to try it were genuinely excited.
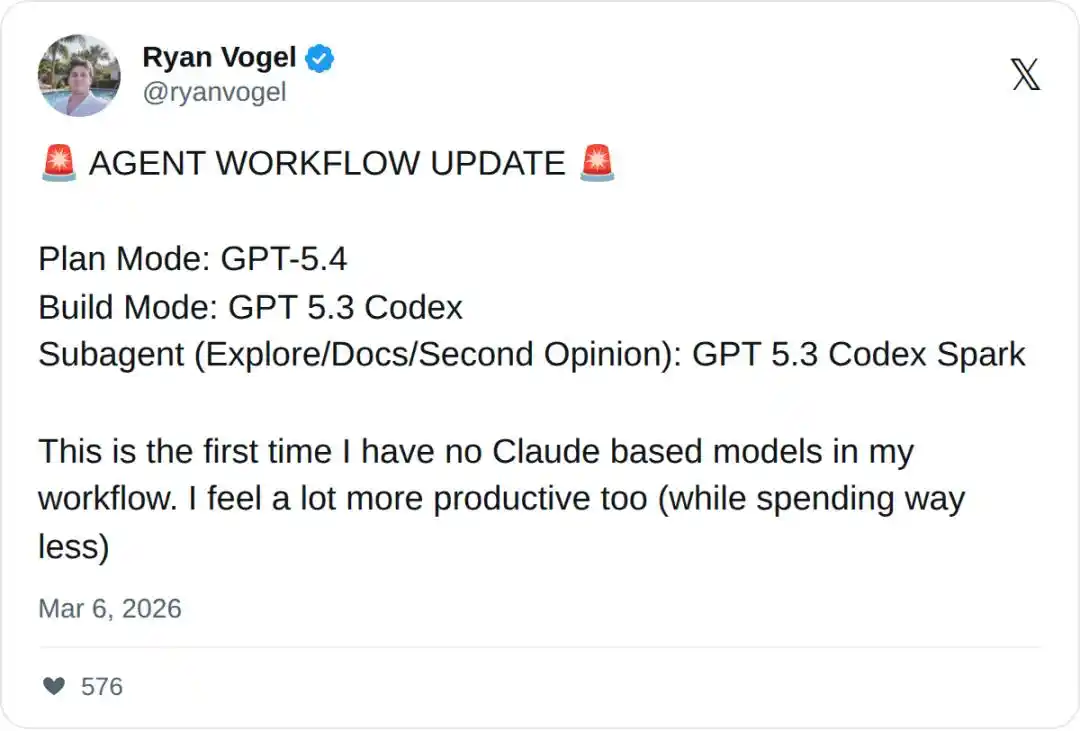
Developer Ryan Vogel directly integrated it into his formal workflow: GPT-5.4 for planning, GPT-5.3-Codex for building, and Spark for exploring codebases, checking documentation, giving second opinions.
He said it was the first time his workflow had zero Claude models, "More efficient, costs less."
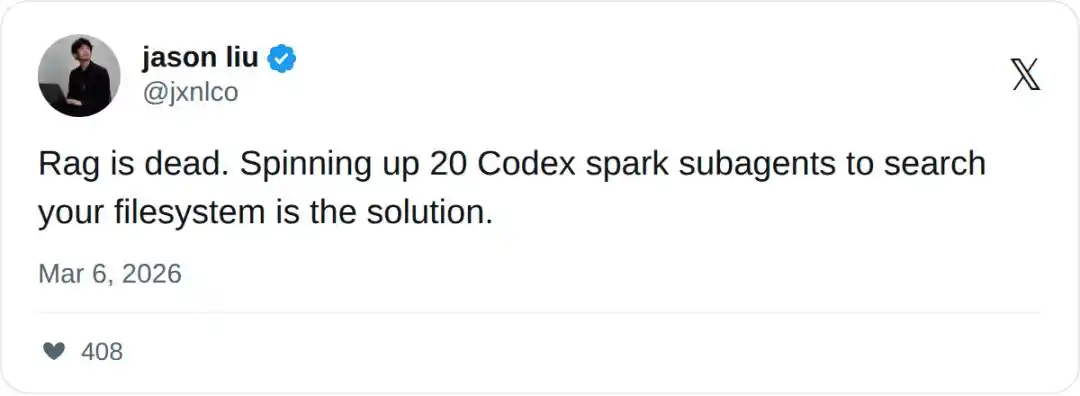
Instructor author Jason Liu directly spun up 20 Spark sub-agents to search the file system, declaring "RAG is dead."
Shortly after, he joined OpenAI's Codex team.
More crucially, Spark carried OpenAI's ambition to break free from single-vendor hardware dependency.
It was OpenAI's first production model running outside NVIDIA's tech stack, powered by startup Cerebras's wafer-scale chip WSE-3.
It marked the delivery of the first milestone from OpenAI's massive 750-megawatt, over $20 billion compute deal with Cerebras.
But the hype faded faster than it rose.
Spark's fatal flaw was that a flagship model couldn't fit on a single wafer; it was essentially a 'distilled small model' compromised for extreme speed.
In the Terminal-Bench 2.0 evaluation, Spark scored only 58.4% accuracy, far below the full GPT-5.3-Codex's 77.3%.
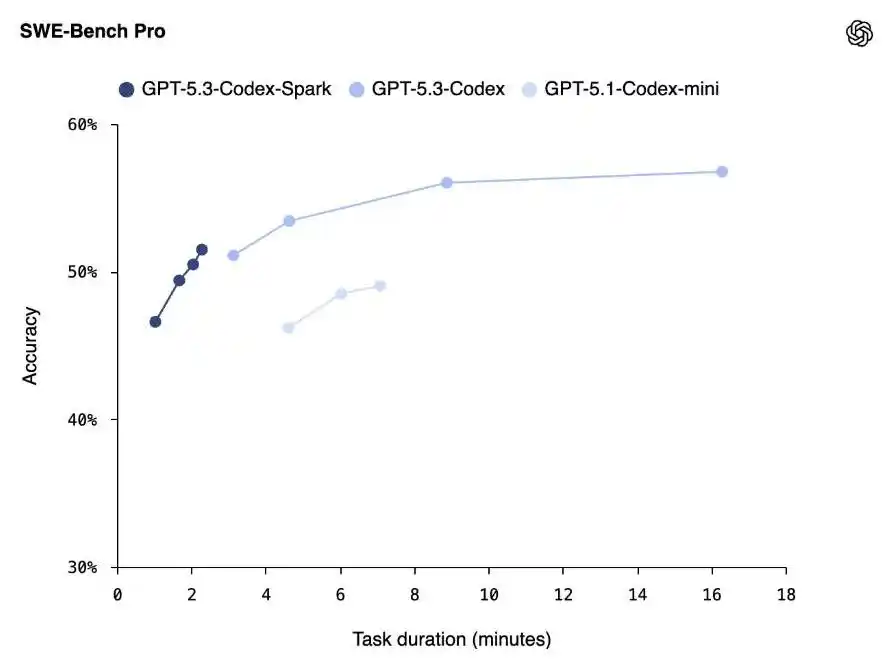
OpenAI's own released SWE-Bench Pro curve also showed—Spark could keep task time under 1 to 2 minutes, but accuracy would plateau between 47% and 51%.
In contrast, the full GPT-5.3-Codex started at 51% from the 3-minute mark, reached 56% at 9 minutes, and 57% at 16 minutes.
Meaning, the few minutes saved by Spark came at the cost of a 5-6 point drop.
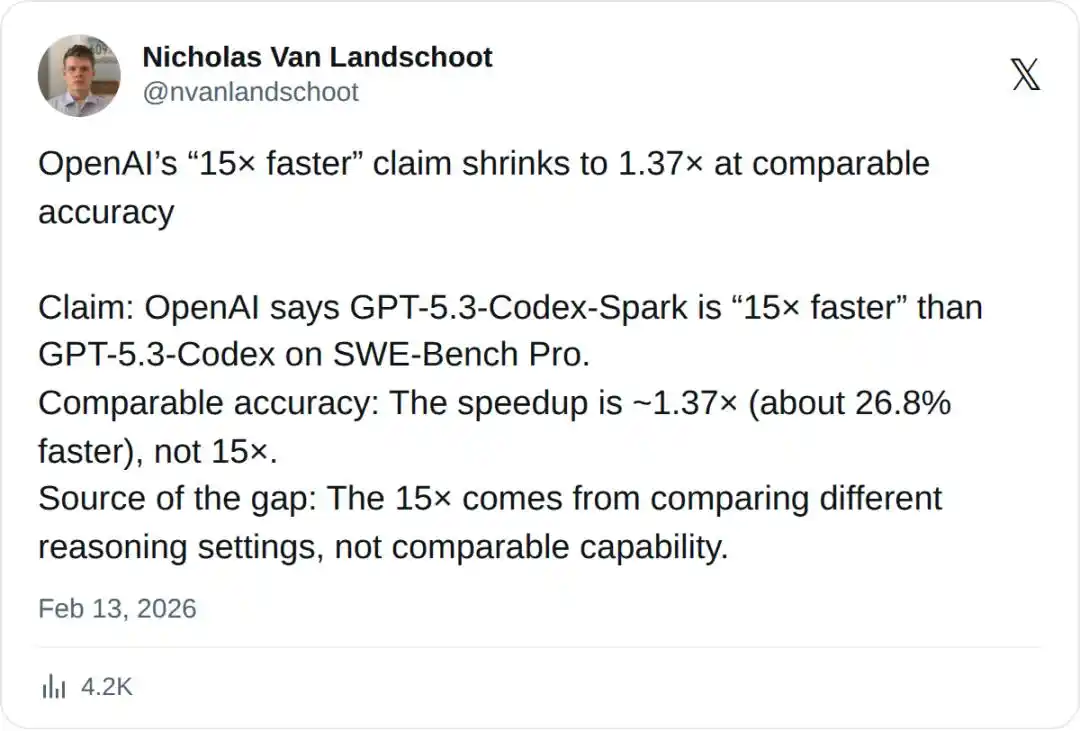
The advertised "15x speedup" was also debunked.
The day after launch, developer Nicholas Van Landschoot posted a lengthy thread on X dissecting OpenAI's comparison conditions. The so-called 15x was comparing Spark against GPT-5.3-Codex with maximum inference strength enabled.
At comparable accuracy levels, Spark was actually only 1.37x faster.
In real coding scenarios, its flaws were magnified endlessly: fabricating API endpoints out of thin air, unstable JSON formatting, multi-step tasks prone to derailing.
Training institution Turing College's summary was spot on: "Speed without intelligence is just failing faster."
For a programmer, waiting 17 minutes for code that works is always more worthwhile than spending 2 minutes on bug-ridden garbage.
Thus, this speed-centric model was destined for marginalization.
The Flagship Itself Steps In, Ultrafast Terminates Spark
The real death sentence for Spark came with the August 13th release of Ultrafast mode by Cerebras.
This time, what ran on the wafer wasn't a shrunken-down Spark, but the flagship model GPT-5.6 Sol itself.
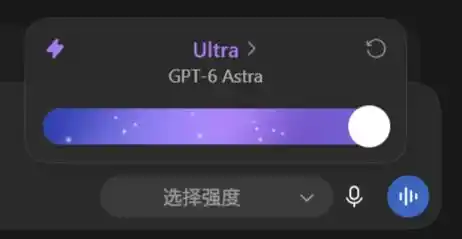
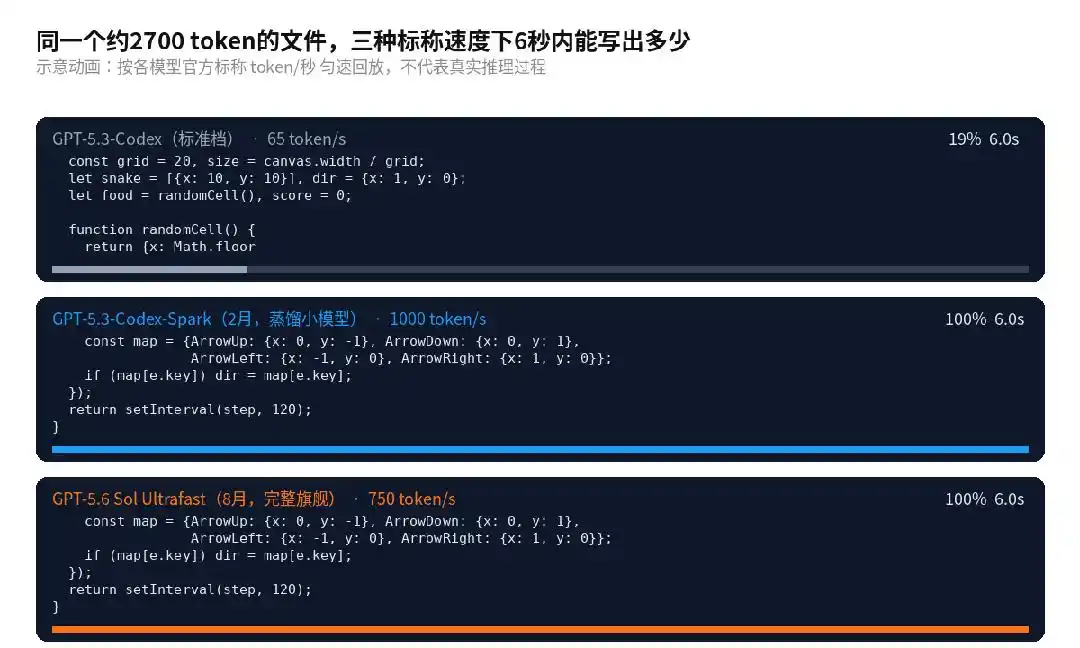
By slicing the massive flagship model layer-by-layer and distributing it across multiple CS-3 nodes to form a pipeline, Ultrafast mode achieved a terrifying speed of 750 tokens per second while guaranteeing "intelligence equal to the standard version."
Cerebras's comparison: Ultrafast is 14x faster than Standard, with a middle Priority tier that's only 2.5x faster.
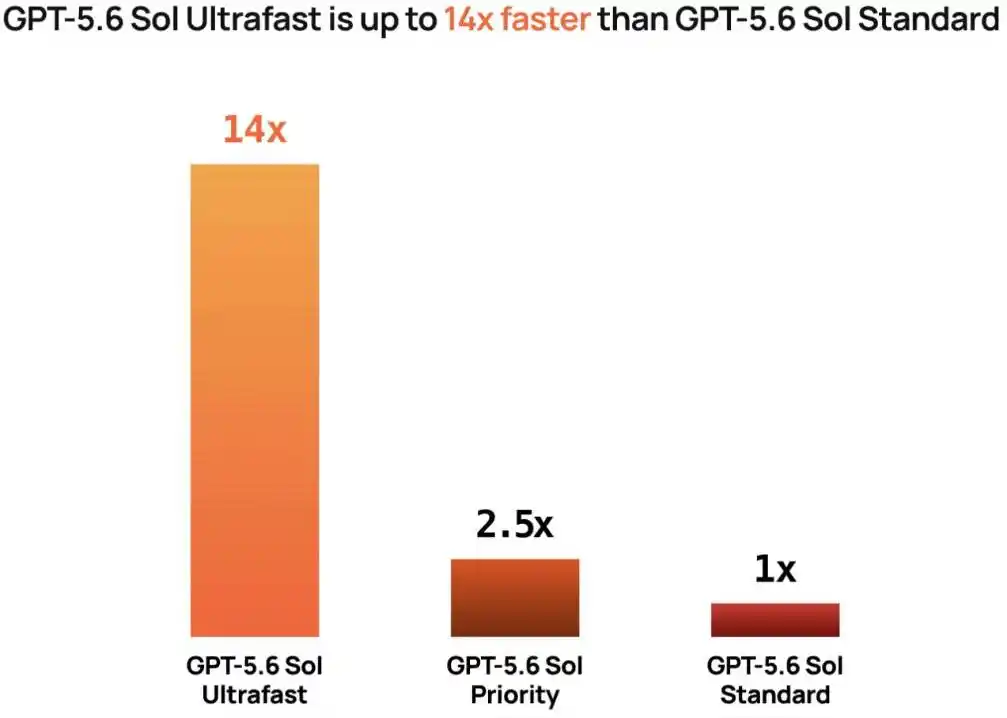
Cerebras CEO Andrew Feldman's statement was resounding: "Speed and intelligence are no longer mutually exclusive."
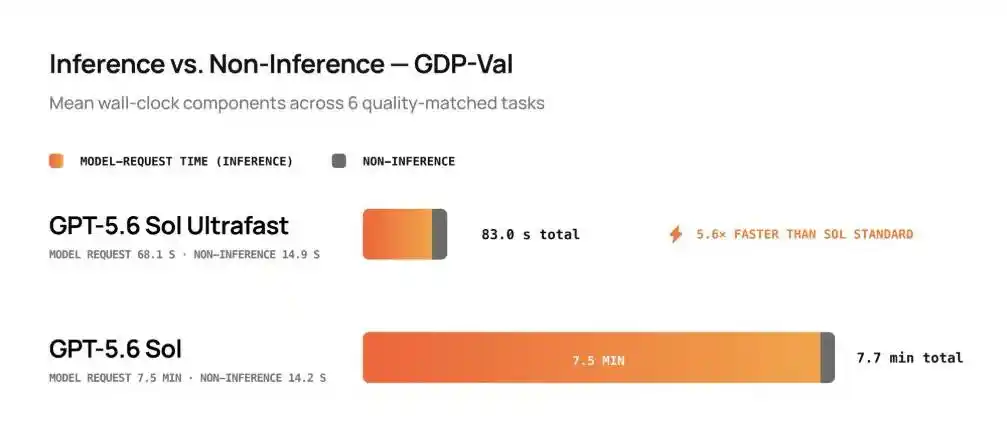
They ran a time comparison on 6 quality-aligned tasks from GDP-Val.
Standard Sol averaged 7.7 minutes, with 7.5 minutes spent on model generation. Switching to Ultrafast, the same tasks took 83 seconds total, with 68 seconds for model generation and the remaining 15 seconds for non-inference overhead like tool calls.
Meaning, end-to-end speed was a full 5.6x faster, and answer quality showed almost no difference.
This statement not only declared a technological breakthrough but directly drained all remaining rationale for Spark's existence.
Spark's design philosophy was "trading intelligence for speed." Just half a year later, the same company's wafers could run the full flagship model, at only a quarter slower speed, with no loss in capability.
Cerebras's production capacity is finite.
When the ignored "miniature version" and the queue-crashing "flagship version" compete for space on the same batch of wafers, the choice of who should make room for the future is self-evident.
Speed is No Longer a 'Dedicated Model', But a 'Paid Tier'
Spark isn't the only historical baggage being cleared out.
Over the past three months, OpenAI's model library has been undergoing an aggressive "refresh."
June 2nd: GPT-5.2 and GPT-5.3-Codex retired.
August 31st: GPT-5.4 and 5.4 Mini retired, users migrated en masse to the 5.6 generation.
September 11th: It's GPT-5.3-Codex-Spark's turn.
Accompanying the departure of the old generation, Codex has ushered in a new naming era: Sol (Sun), Terra (Earth), Luna (Moon), Astra (Star).
Names like "GPT-5.3-Codex-Spark," with lengthy version numbers and product line suffixes, indeed already feel like relics from a bygone era.
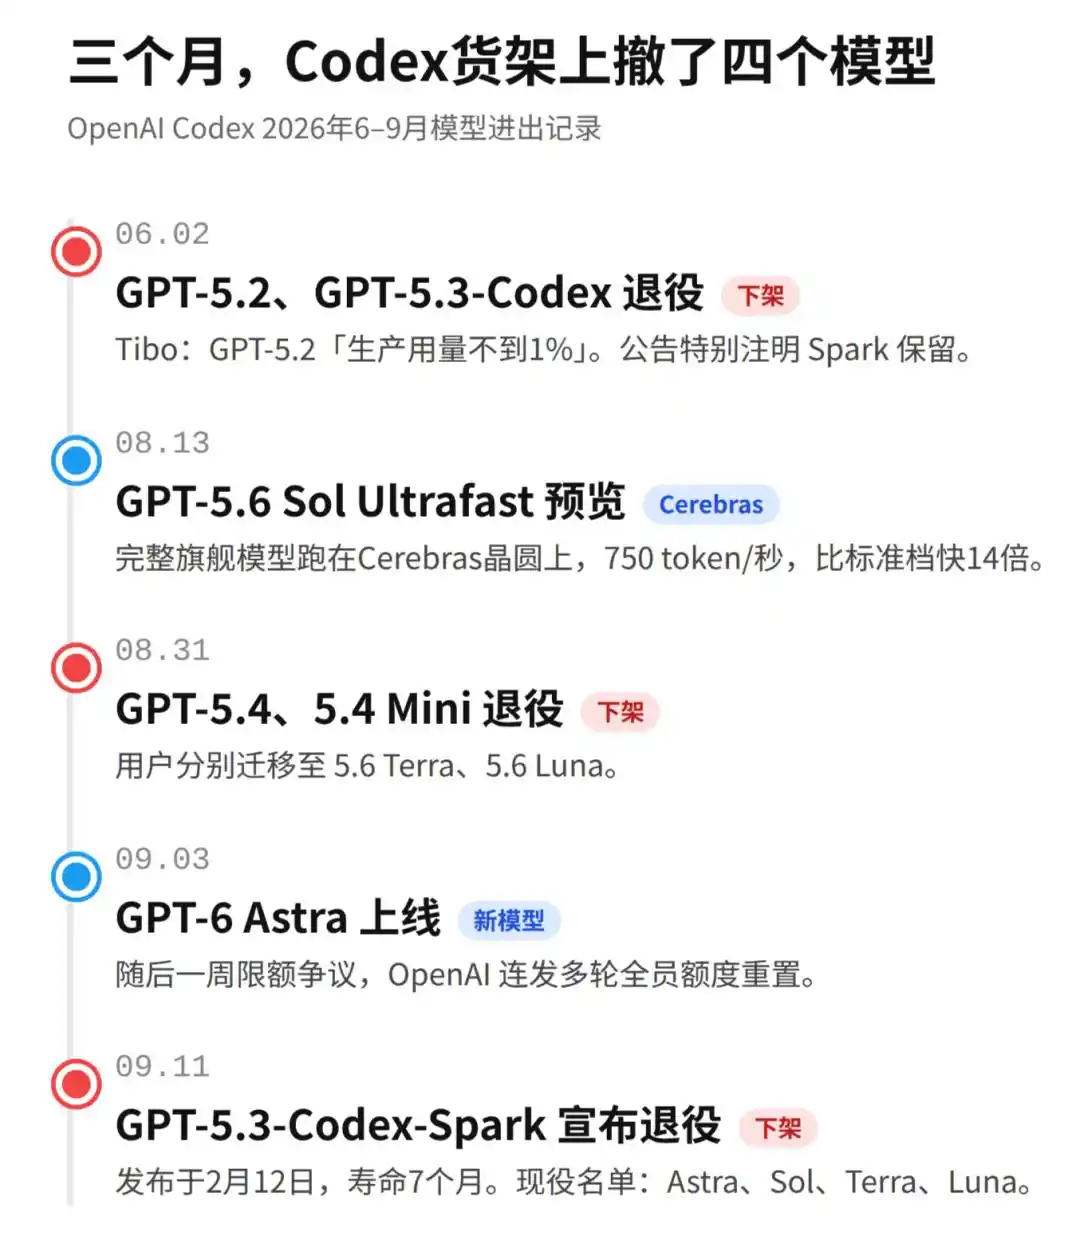
A deeper shift in logic is that the attribute of "fast" is evolving from a standalone dedicated model to a standard "tier" of the flagship model.
Just like inference strength ranges from Light to Max, OpenAI's current speed now tiers from Standard, Priority to Ultrafast. Speed is tied to compute power, and the pay-by-tier business model is fully established.
Looking back, Spark perfectly fulfilled its historical mission.
As a transitional pathfinder, it proved Cerebras's wafers could handle production-level generative AI traffic and that inference tasks could indeed run outside NVIDIA's ecosystem.
When the pathfinding ended and the main forces officially moved in, the pathfinder's mission naturally concluded.
The misguided path of "trading intelligence for speed" is officially sealed today.
As major platforms begin competing for the ultimate utilization of underlying hardware, the rules of the next arms race have been completely rewritten.
The next round won't be about who can make the fastest castrated model, but who can run the strongest flagship model at the most extreme speeds.
References:
https://x.com/thsottiaux/status/2098300998968357218
Editor: Moses
This article is from WeChat public account "New Zhiyuan", author: ASI Revelation