GPT-6.1 Sol's default context window has surged directly to 500k!
With the OpenAI Day 7 update, the default window in Codex and ChatGPT Work expanded from 272k to 500k, a jump of about 80% in one go.
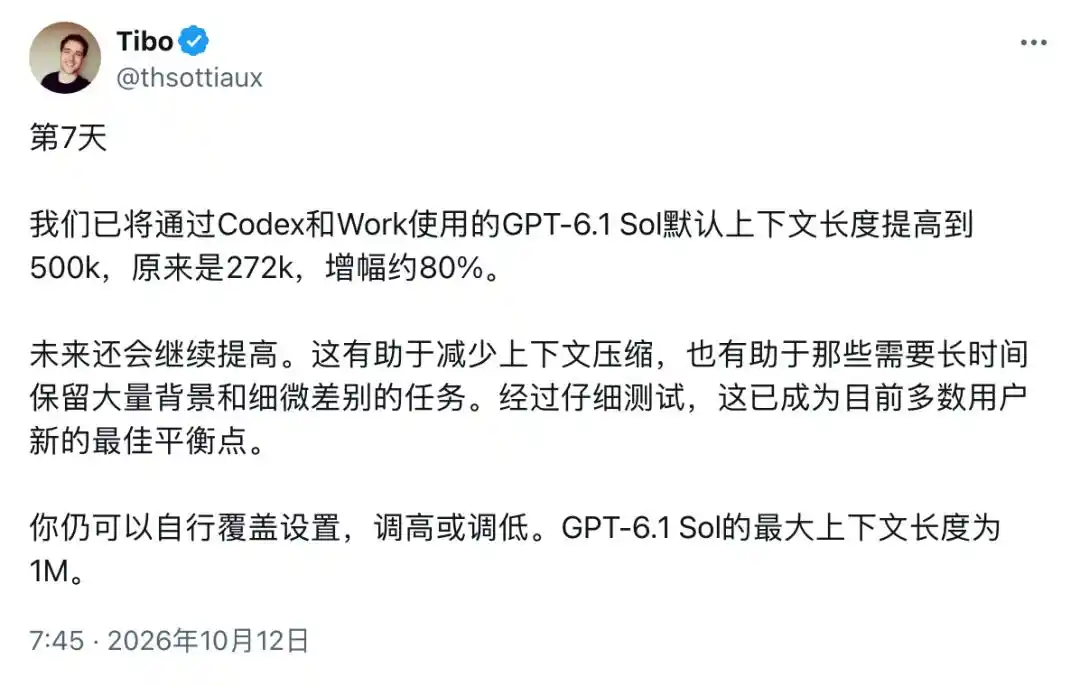
Immediately after, Tibo added another point: Using subscription credits to run GPT-6.1 Sol will not incur long-context surcharges.
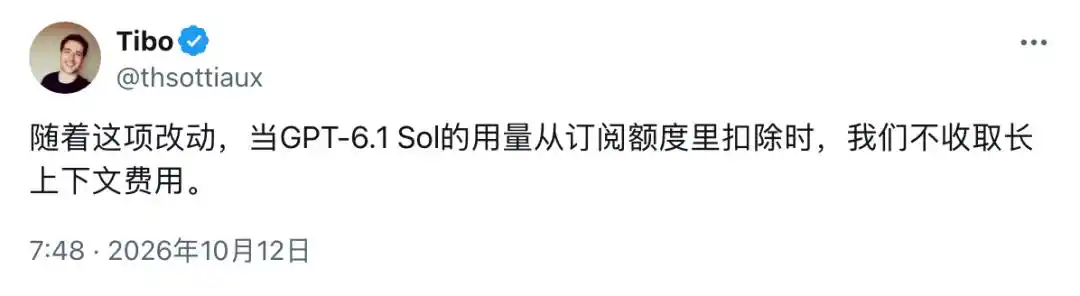
Tasks will still consume subscription credits as usual, but there will be no extra charge specifically for the longer context.
API calls are still billed according to the API pricing table.
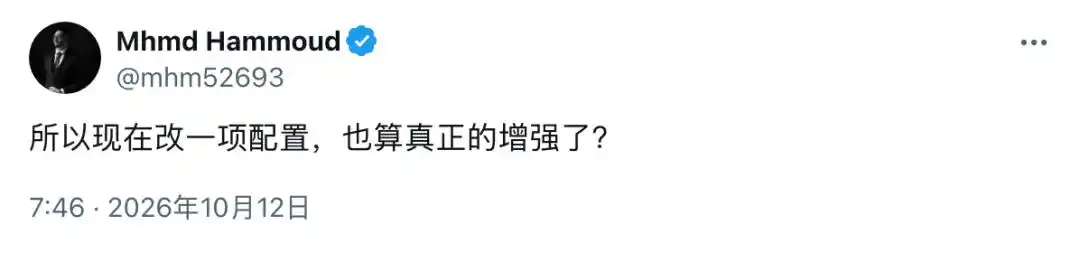
However, developer Mhmd Hammoud countered in the comments: "Does tweaking a configuration now count as a real upgrade?"
GPT-6.1 Sol Roars to 500k, Wish Granted
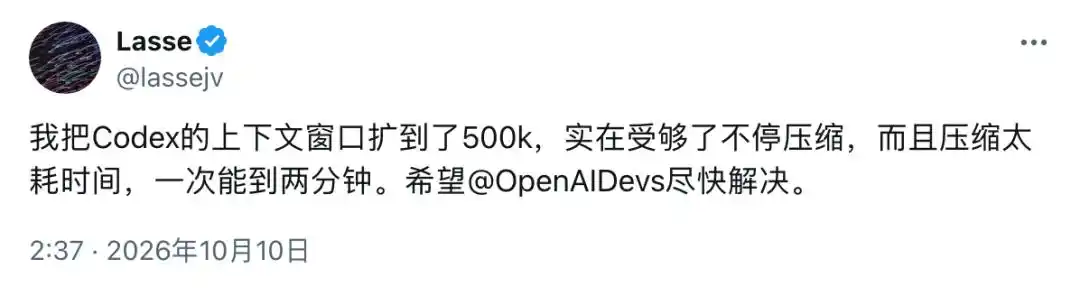
Even before the default 500k was rolled out, developer Lasse was already fed up with waiting for compression.
He once complained, "Codex compressing the context could make me wait up to two minutes at worst."
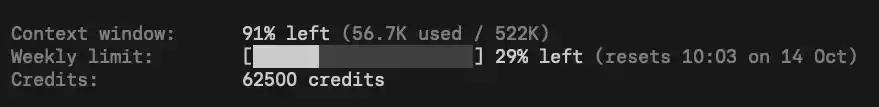
Two days before this update, he simply set his window to 500k himself, posted a screenshot of the status, and called on OpenAI to fix the slow compression issue quickly.
When asking Codex to review files, modify code, or run tests, the code read and errors encountered all occupy the context.
When the context is nearly full, it must first compress and organize the earlier conversation and progress to free up space before it can continue working.
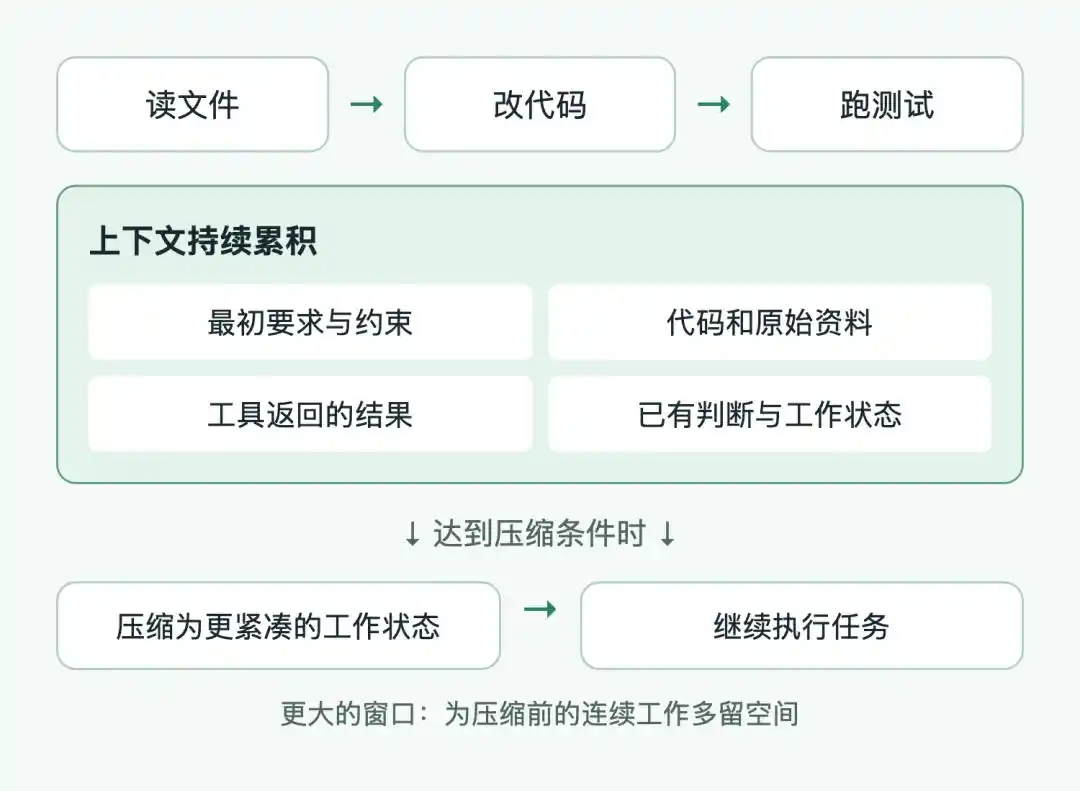
After waiting for compression, you still have to check if it missed the initial requirements.
For example, you might have said, "This interface needs to be backward compatible." If it modifies a dozen files, the new feature works, but the old interface breaks, you'd end up having to fix it yourself.
Tibo stated that this expansion reduces the need for compression and allows the model to retain more details during long tasks.
Fewer waits for compression, fewer repeats of the same requirement – that's how the 500k truly helps.
Surcharge Waived, Credits Still Deducted
The biggest fear was that less compression might lead to credits depleting even faster. OpenAI had indeed stepped into this pitfall before.
In July of this year, OpenAI increased the context in their products from 272k to 372k for use with GPT-5.6 Sol.
The result was subscription usage being deducted more than expected, so the team rolled back to 272k. The capacity just added was promptly taken away.
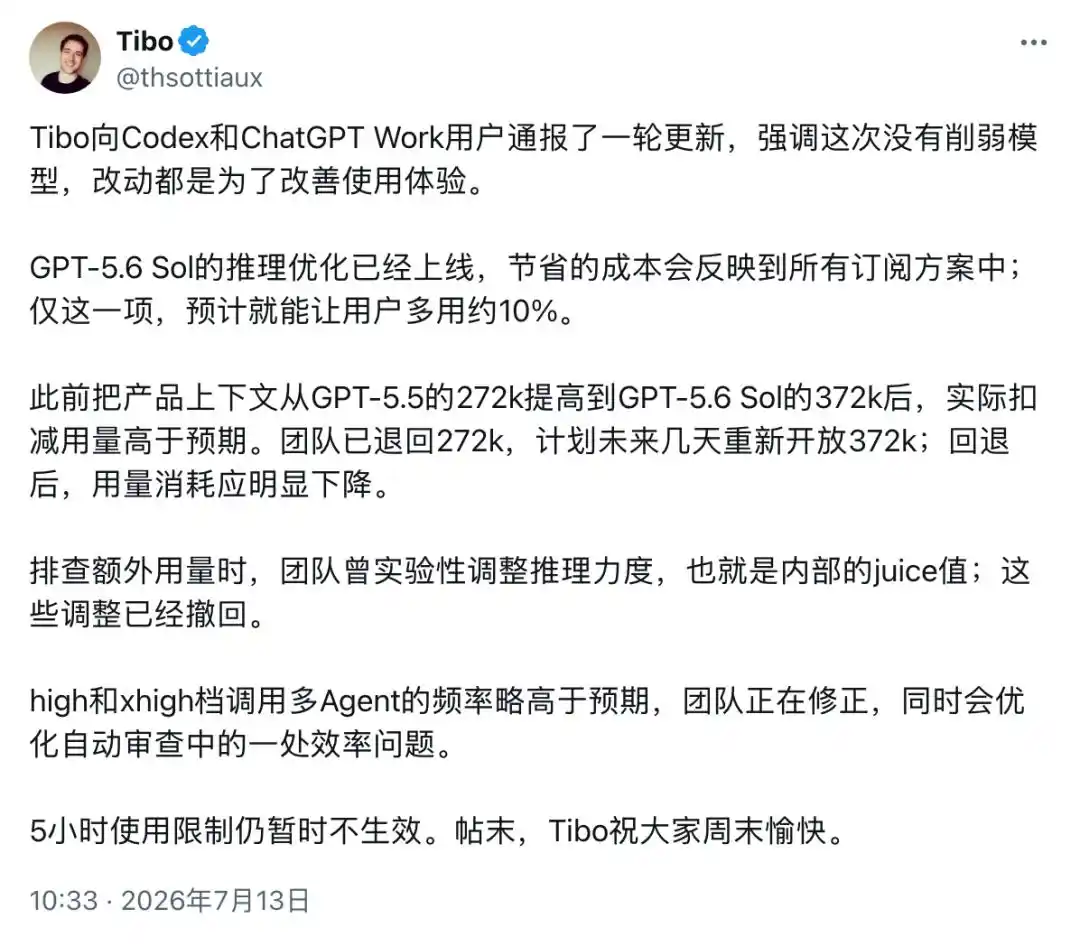
Developer Theo speculated at the time that it might be due to double charging for context exceeding 272k.
Tibo corrected this, saying that subscriptions back then also didn't have a long-context surcharge. The extra usage came from repeatedly reading more cached content.
You only typed "continue," but the Agent, needing to continue modifying code, still has to bring along the previously read files, test results, and requirements.
When subsequently calling tools and continuing reasoning, this content might be read repeatedly.
Caching allows reuse of already processed content at a lower read cost, but each read still counts towards usage. More content read and more frequent reads accumulate consumption.
Waiving the surcharge doesn't necessarily mean the same task will definitely use fewer credits.
Developers want to wait less for compression, but not run out of credits before the project is finished.
Claude Already Defaults to a Million
However, whether 500k is sufficient must be compared with Claude.
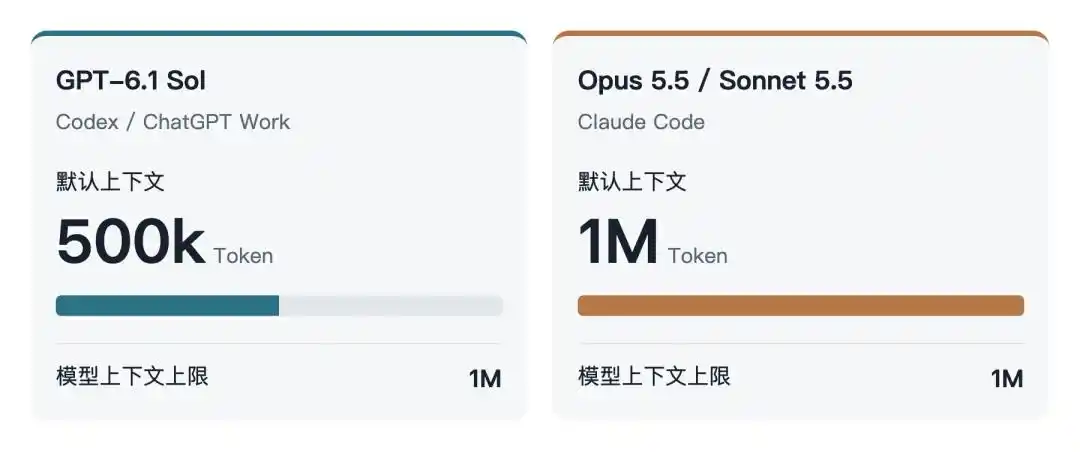
In Claude Code, Opus 5.5 and Sonnet 5.5 already have a default context of 1M, double the new default value of Codex.
In reality, GPT-6.1 Sol's upper limit can also reach 1M, and users can manually increase it.
However, OpenAI defaulted to 500k this time because, after testing, they believe this setting is more suitable for most users.
Regarding costs, when calling the API for these two Claude models, the standard token price applies within 1M, and the unit price doesn't increase with longer context.
What OpenAI waived this time is the long-context surcharge within subscription credits; API pricing is separate. Both sides are referring to different fee scopes.
Even with a 1M window, it can still fill up. In Claude Code, using these two models, the default auto-compression point is around 967k.
When nearing the limit, it first removes earlier tool outputs from the context, such as records from reading files or running commands.
If more space is needed, it then condenses the conversation into a summary, retaining the current requirements and key code, allowing the task to continue.
Sub-tasks like file lookups can be delegated to a sub-Agent. It has its own context, and after the lookup, it returns a summary of the results.
This way, the main Agent can proceed with the results without needing to stuff the entire lookup process into the main conversation.
OpenAI states that the default window will continue to increase in the future.
The window will grow larger, but developers' patience cannot expand alongside it. After handing code to AI, there should be fewer waits and fewer repeats of "I mentioned this requirement earlier."
References:
https://x.com/thsottiaux/status/2109430343346581527?s=20
This article is from the WeChat public account "新智元" (New Zhiyuan), author: Moses & Taozi