Conversation with Mai-Lan from AWS: The Next Battlefield for S3 – How to Handle the Data Consumption Surge in the Agent Era

marsbitPublicado em 2026-05-08Última atualização em 2026-05-08

Resumo

The explosive rise of Agent AI, exemplified by OpenClaw in China, is putting unprecedented pressure on cloud data infrastructure. Unlike human engineers, Agents consume data in an "extremely active and aggressive" parallel fashion, launching tens to hundreds of queries simultaneously, leading to exponentially higher call frequencies and throughput. Mai-Lan Tomsen Bukovec, VP of Technology at AWS, emphasizes that cost-effectiveness in this data layer is now a decisive factor for customers building Agent systems. To address this, AWS is positioning its foundational Amazon S3 service, now 20 years old, as the critical data platform for the Agent era. Recent key innovations include: **S3 Table** with native Apache Iceberg support, enabling Agents to efficiently interact with structured data via familiar SQL; **S3 Vector**, which introduces vectors as a native type for building contextual data and serving as a shared "memory space" for AI systems; and the newly launched **S3 Files**, which provides a POSIX-compliant file system interface over S3, allowing Agents to interact with data through the familiar paradigm of files and directories. These enhancements are designed to meet the unique data interaction patterns of Agents, which are trained on models already proficient with SQL, file systems, and contextual vectors. By unifying these access methods on the scalable, durable, and cost-efficient S3 foundation, AWS aims to provide the data backbone capable of supporting the next w...

At the beginning of the year, the popularity of OpenClaw in the Chinese market allowed everyone to see the enormous potential of Agents. But what followed was a question that all cloud vendors must answer: When Agents begin to multiply like cybernetic lobsters and call data at high frequencies, are the AI cloud infrastructure layers, especially the data layer, ready?

For example, when enterprise data teams deploy Agents into production environments, they often encounter bottlenecks at the data layer. Building Agents across different platforms such as vector databases, relational databases, graph databases, and data lakehouses requires synchronized data pipelines to maintain the timeliness of context information. But in real production environments, this context information gradually becomes outdated.

The urgency of this problem stems from the fundamentally different data consumption patterns of Agents compared to human engineers.

"Agents are consuming data in an extremely active and aggressive way. Their call frequency to data warehouses or data lakes is astonishing."

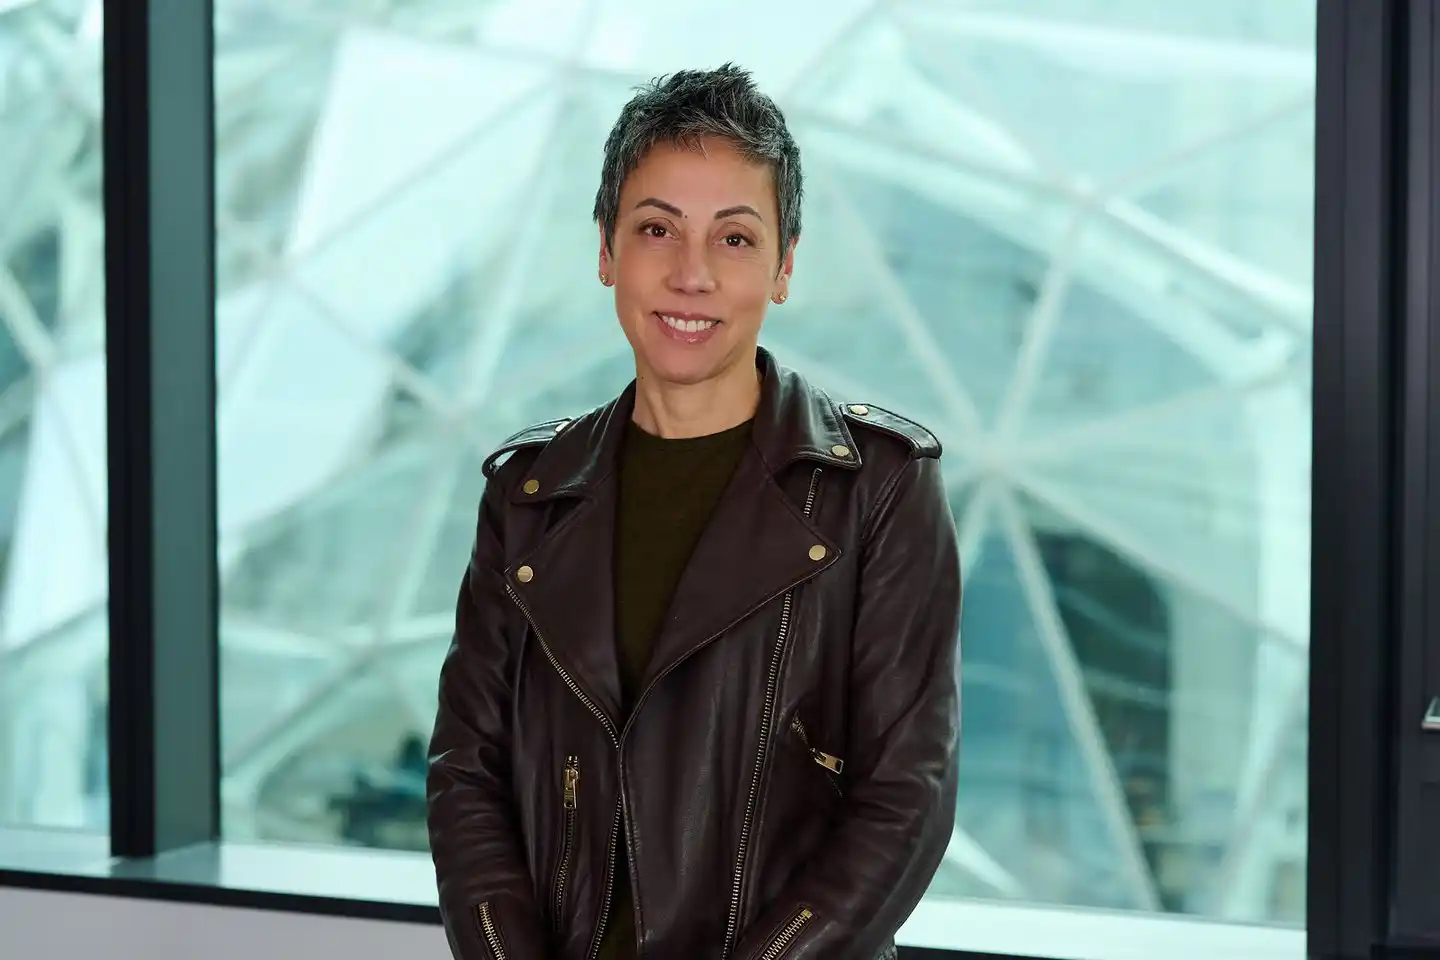
Mai-Lan Tomsen Bukovec, Vice President of Technology at Amazon Web Services, recently pointed out in a discussion with the author that Agents operate through a "parallel comparison and selection" mode of work. That is, instead of one query at a time, they run dozens or hundreds in parallel simultaneously, comparing results to find the optimal path. This makes Agents far more aggressive data consumers than humans—with call frequencies several orders of magnitude higher and data throughput growing exponentially.

Mai-Lan further pointed out, "Customers are now very eager to build Agent infrastructure. Cost, or rather cost-effectiveness, is no longer a secondary factor but has become a decisive one. In the next six months to a year, with the explosion of Agents, the choice of underlying data services will become crucial."

Now, the OpenClaw frenzy is subsiding, leaving behind a pressure test warning for the underlying storage and compute capabilities of cloud vendors. Mai-Lan believes that AWS holds a natural advantage in this field. The scale of Amazon S3 (Amazon Simple Storage Service), and the cost efficiency of Amazon Redshift and Amazon Athena under high concurrency, are precisely prepared for this ultra-large-scale, ultra-high-frequency Agent data interaction mode.

Coinciding with the 20th anniversary of Amazon S3, and centered around customer demands for data processing in the AI era, Amazon S3 has recently implemented three major evolutions: S3 Table (Tabular), S3 Files (Files), and S3 Vector (Vector).

Take S3 Table's native support for Apache Iceberg, for example. Mai-Lan noted that when Agents process data, they tend to interact directly with data in Iceberg format via SQL. The underlying logic is that Agents are built on large language models (LLMs), and LLMs have developed mature processing capabilities for SQL syntax and Iceberg data formats during training. Storing all table data in Iceberg format on S3 allows Agents to efficiently handle data without needing to learn complex access APIs for multiple systems. Currently, Agents show a high degree of compatibility with S3 and Iceberg.

When Iceberg capabilities were introduced to S3, it triggered a new wave of innovation. Data sources like Postgres and Oracle began writing directly to Iceberg, and Agent systems could interact directly with these tables. And with the launch of S3 Vectors, more and more AI applications are using vectors as a shared memory medium, thereby injecting "state" into AI interaction experiences.

Mai-Lan also pointed out that vectors have been introduced as a native data type in S3. The application of vectors mainly concentrates on two dimensions: one is using vectors to build contextual information for data stored in S3, and the other is using vectors as shared memory. In the five months since S3 Vectors was released, market feedback has met expectations. A large number of customers have started using this feature, generating vectors via embedding models to enrich the context of their data. The usage of S3 Vectors as the memory space for Agent systems has seen explosive growth.

It is worth mentioning that S3 Files was released a few weeks ago, enabling Agents to process data in S3 via the POSIX standard—that is, through a file system approach. In Agent systems, LLMs pay high attention to the "file" form. Whether it's Python libraries or Shell scripts, they are content familiar from LLM training. Agents naturally prefer to use files as data interfaces.

For this reason, the design concept of S3 Files is to mount an EFS file system on an S3 bucket. Through this mechanism, users can process S3 data in the file system based on POSIX standards: small files can be accessed faster via EFS caching, while large files are streamed directly from S3. This allows Agents to interact natively with S3 data using the familiar language of the file system and treat the shared file system as a "shared memory space" from S3.

From the perspective of the development of LLM memory capabilities, this progress is significant. Current AI experiences are gradually introducing deeper conversational context and personalized interactions—whether between Agents, between humans and Agents, or between Agents and data, model performance is continuously evolving. By further extending this natural interface of the file system, the memory capabilities of Agent systems are expected to achieve deeper enhancements.

The author notes that from its start in 2006 primarily handling semi-structured data like images, to later analytical data, from the initial data warehouse to the rise of the data lake, AWS is now vigorously promoting Amazon S3 to become the key foundation for carrying AI workloads to meet current customer demands. Mai-Lan believes that the design core of Amazon S3 is to drive the growth of mainstream data types in a cost-effective way, while always adhering to principles such as data availability, durability, and resilience. And this is precisely why customers have entrusted their data operations to S3 for the past 20 years, and it will also carry its possibilities for the next 20 years.

(Author | Yang Li, Editor | Yang Lin)

Criptomoedas em alta

Perguntas relacionadas

QWhat is the core difference in data consumption patterns between AI agents and human engineers as highlighted in the article?

AThe article emphasizes that AI agents consume data in an 'extremely active and aggressive' manner. They operate on a 'parallel comparison' or 'optimization by comparison' model, issuing dozens or even hundreds of parallel queries simultaneously to find the best path. This results in a data consumption frequency and throughput that is several orders of magnitude higher than that of human engineers.

QWhat are the three major innovations recently implemented for Amazon S3 to meet the demands of the AI era?

ATo address AI-era data processing needs, Amazon S3 has recently introduced three major innovations: S3 Table (with native support for Apache Iceberg format), S3 Files (enabling POSIX file system access to S3 data), and S3 Vector (introducing vectors as a native data type for building context and shared memory).

QWhy does the article suggest that S3's support for Apache Iceberg is particularly beneficial for AI agents?

AThe article states that AI agents, built on large language models (LLMs), are already proficient in handling SQL syntax and Iceberg data formats due to their training. By storing all table data in Iceberg format on S3, agents can interact with the data efficiently without needing to learn multiple complex access APIs. This creates a high degree of compatibility between agents and the S3/Iceberg ecosystem.

QHow does the newly released S3 Files feature enable better interaction for AI agents with data in S3?

AS3 Files allows agents to interact with S3 data via the POSIX file system standard. It works by mounting an EFS file system on an S3 bucket. This lets agents use familiar file system operations: small files are accelerated via EFS cache, while large files are streamed directly from S3. This provides agents with a natural 'file' interface, treating the shared file system as a 'shared memory space' sourced from S3.

QAccording to Mai-Lan, what has become a decisive factor for customers looking to build Agent infrastructure, moving beyond just being a secondary consideration?

AMai-Lan points out that for customers eager to build Agent infrastructure, 'cost, or rather cost-performance ratio, is no longer a secondary factor but has become a decisive factor.' She emphasizes that in the coming 6 to 12 months, the choice of underlying data services will be crucial as Agent adoption explodes.

Leituras Relacionadas

AI Redefines What Makes a Good Teacher

AI is redefining the role of the good teacher. While AI adoption in Chinese K-12 education is widespread—reducing new teachers' lesson prep time by over 60%—it has not replaced teachers. Instead, it amplifies the need for their human judgment and presence. Research highlights a critical shift: AI excels at elevating a student's initial 30-point idea to a 70-point answer, but it risks eliminating the crucial 20-point journey of deep, personal learning from 70 to 90. A study from the University of Pennsylvania showed students using an unfettered AI as a "crutch" performed worse on subsequent tests than those using a teacher-guided "guardrailed" AI or a control group. AI efficiently handles standardized tasks like lesson planning, grading, and personalized assignments, making differentiated instruction scalable. However, it cannot replicate the "collective teacher efficacy"—the shared belief among educators that they can impact students—which research identifies as the top factor influencing student achievement. The new benchmark for teachers involves three levels of AI literacy: verifying AI output, directing AI to complete tasks, and, most critically, redesigning courses and pedagogy with AI. Currently, most training stops at the second level. The gap is widening between "super teachers," who use saved time for deeper student engagement, and those who risk "metacognitive laziness" by over-relying on AI without critical oversight. Ultimately, AI makes affordable, one-on-one tutoring possible, fulfilling a long-standing educational challenge. Yet, the Penn study underscores that access alone is insufficient. Effective learning still requires a teacher to guide when to intervene and when to step back, ensuring students earn the final, transformative 20 points of their intellectual growth.

marsbitHá 8m

AI Redefines What Makes a Good Teacher

marsbitHá 8m

Kotlin 'J God' Two-Hour Controversial Interview: I'd Rather Lose 80% of Job Opportunities Than Use AI for Programming

Jake Wharton, a prominent Android and Kotlin developer known as "J God," has taken a strong stance against using AI for programming. He publicly stated that he will not join AI companies, work on AI-centric products, or accept roles that mandate AI tool usage, a condition he estimates eliminates 80% of potential job opportunities for him. Wharton values stable cash compensation and the freedom to choose his employer over the potentially higher, riskier rewards of trending tech sectors like AI and cryptocurrency, which he views critically. In a recent two-hour interview, Wharton explained his skepticism. He argues that the push for AI in software development is often driven top-down by management, bypassing engineering judgment, unlike the traditional bottom-up adoption of new tools by developers. He has never used an AI agent to write code, believing the most irresponsible use is generating code beyond a developer's understanding, which can lead to unmaintainable software and erode an engineer's core skills and bargaining power. While he acknowledges AI as a potentially useful tool in the toolbox, he firmly opposes making it the foundation of the engineering process. Wharton also discussed Kotlin's evolution, describing it as "what Java wanted to be 10 years later." He highlighted its advantages, such as built-in null safety, and its success in becoming a default for Android development. However, he noted that merely knowing Kotlin is no longer a distinct career advantage due to its widespread adoption. He expressed admiration for languages like Swift and Rust, particularly Rust's approach to ownership and error handling. Having left large companies like Google and Cash App, Wharton now prefers working in small, focused teams. He recently joined Skylight, a company that aligns with his values of open-source contribution and restrained, non-core use of AI. Wharton remains unconvinced that AI will replace programmers, emphasizing that software creation and maintenance require human understanding and that AI-generated code still needs expert review and debugging.

marsbitHá 12m

Kotlin 'J God' Two-Hour Controversial Interview: I'd Rather Lose 80% of Job Opportunities Than Use AI for Programming

marsbitHá 12m

Trading

Spot

Artigos em Destaque

Como comprar ERA

Bem-vindo à HTX.com!Tornámos a compra de Caldera (ERA) simples e conveniente.Segue o nosso guia passo a passo para iniciar a tua jornada no mundo das criptos.Passo 1: cria a tua conta HTXUtiliza o teu e-mail ou número de telefone para te inscreveres numa conta gratuita na HTX.Desfruta de um processo de inscrição sem complicações e desbloqueia todas as funcionalidades.Obter a minha contaPasso 2: vai para Comprar Cripto e escolhe o teu método de pagamentoCartão de crédito/débito: usa o teu visa ou mastercard para comprar Caldera (ERA) instantaneamente.Saldo: usa os fundos da tua conta HTX para transacionar sem problemas.Terceiros: adicionamos métodos de pagamento populares, como Google Pay e Apple Pay, para aumentar a conveniência.P2P: transaciona diretamente com outros utilizadores na HTX.Mercado de balcão (OTC): oferecemos serviços personalizados e taxas de câmbio competitivas para os traders.Passo 3: armazena teu Caldera (ERA)Depois de comprar o teu Caldera (ERA), armazena-o na tua conta HTX.Alternativamente, podes enviá-lo para outro lugar através de transferência blockchain ou usá-lo para transacionar outras criptomoedas.Passo 4: transaciona Caldera (ERA)Transaciona facilmente Caldera (ERA) no mercado à vista da HTX.Acede simplesmente à tua conta, seleciona o teu par de trading, executa as tuas transações e monitoriza em tempo real.Oferecemos uma experiência de fácil utilização tanto para principiantes como para traders experientes.

858 Visualizações TotaisPublicado em {updateTime}Atualizado em 2026.06.02

Como comprar ERA

Discussões

Bem-vindo à Comunidade HTX. Aqui, pode manter-se informado sobre os mais recentes desenvolvimentos da plataforma e obter acesso a análises profissionais de mercado. As opiniões dos utilizadores sobre o preço de ERA (ERA) são apresentadas abaixo.

活动图片