In recent years, video generation models have rapidly advanced in clarity, temporal consistency, and controllability. Given text, images, camera trajectories, or player actions, models are now capable of synthesizing coherent subsequent frames, bringing the concept of "interactive video worlds" from theory to observable, operable prototypes.
However, continuing the visual sequence does not equate to running a world. Movement and collision within the frame are only the most intuitive layer of interaction; in more complex environments, characters have goals, identities, and relationships, events are constrained by rules, and actions have causal consequences that span longer timeframes. Many states occur even off-screen yet still alter subsequent plots and actions. Predicting the next segment of observation based solely on local pixels makes it difficult to explicitly maintain these high-level semantics.
Complex worlds first require "understanding why." Goals, rules, memory, and causal chains are often not directly readable from the current frame, yet they determine how the world should change next. Language models, with their capabilities in knowledge retrieval, reasoning, planning, and programming, are well-suited to handle these low-frequency but high-complexity decisions and translate them into executable rules.
Another often overlooked fact is: game video is not the world itself, but the pixel projection of a program's execution after rendering. Currently, games and simulators still constitute the primary source of interactive data for video world models. If only actions and pixels are retained, and a video model is tasked with directly learning the mapping between them, it bypasses the originally existing program, rules, and explicit world state, instead requiring the model to reverse-engineer the entire program behavior from visual outcomes. This learning path is not only inefficient but also couples "how the world evolves" and "how the world is presented" into a single model.
Based on this observation, a research team from the Westlake University AGI Lab and Nanyang Technological University proposed Code World Model, a novel world model paradigm with a language model as its "brain." Its core idea is to have a coding agent continuously write, invoke, and modify code to maintain and update an executable world state; the state relevant to the current observation is then converted into proxies to guide a video model in generating detailed visual scenes.
Paper Link:https://arxiv.org/abs/2608.25927
Project Page:https://buaacyw.github.io/cwm/
Code Repository:https://github.com/buaacyw/code-world-model
Here, the language model does not replace the video model. Code World Model redefines their responsibilities: knowledge, goals, rules, and long-term causality are handled by the coding agent and code; appearance, motion details, lighting, and texture are handled by the video model. In other words, the former determines *what* happens in the world, the latter determines *how* it all looks.
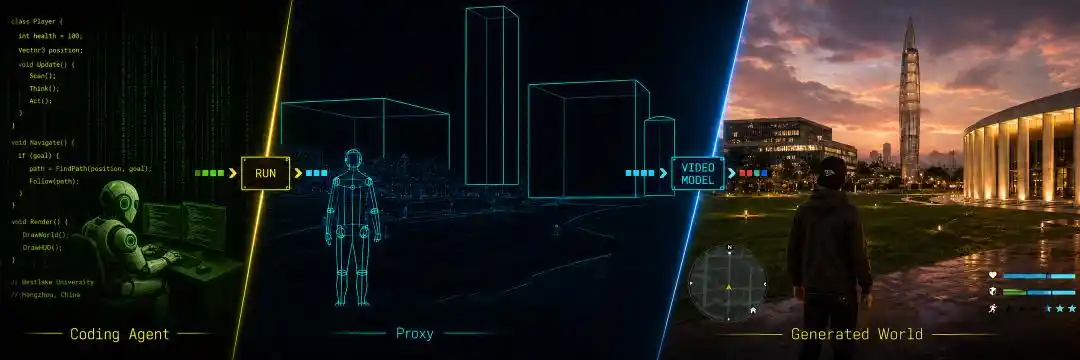
Figure 1: The core division of labor in Code World Model: the coding agent evolves the world state through code, proxies convert relevant states into visual conditions, and the video model generates the final scene.
Method Overview
Building on this division of labor, Code World Model decomposes the world's operation into three interconnected parts.
Coding Agent: Understands player intent and new events, invokes world knowledge, infers potential consequences, and decides which mechanisms need to be executed, combined, or modified.
Code: Executes deterministic updates such as position, attributes, collision, cooldowns, and event triggers at a higher frequency, turning high-level decisions into inspectable, reusable, and continuously executable rules.
Video Model: Reads the evolved state conditions and leverages the appearance, motion, and interaction priors learned from large-scale visual data to generate visual observations rich in texture, lighting, and local dynamics.
This division also corresponds to different computational frequencies. The coding agent only needs to make sparse decisions when new goals, complex events arise, or existing mechanisms are insufficient; once decisions are written into code, the program can continuously execute dense state updates.
More importantly, the coding agent can rewrite not just numerical values at a given moment, but also the operational rules the world follows thereafter.
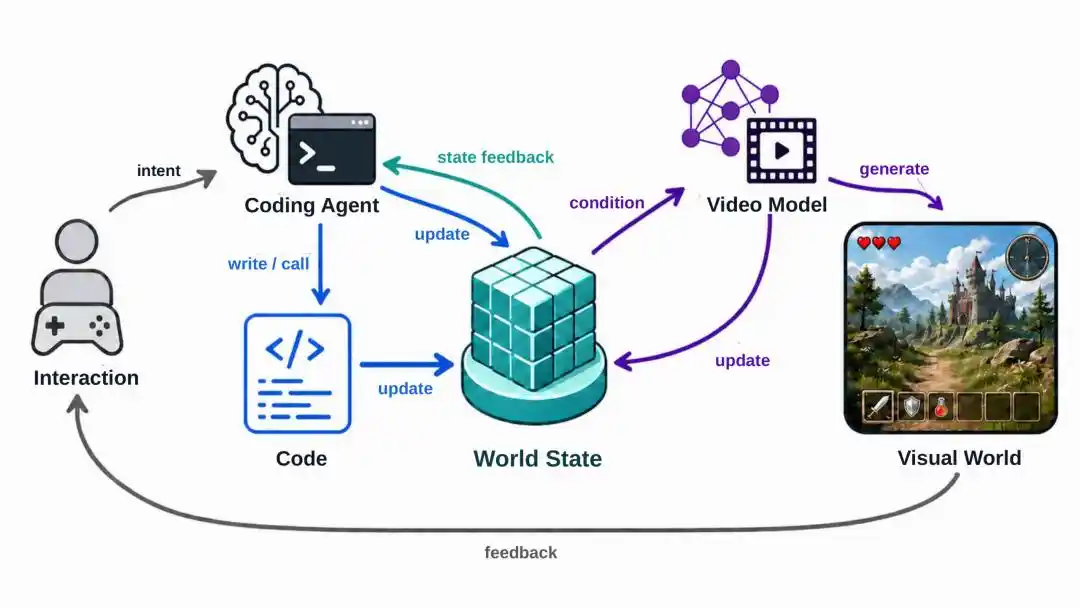
Figure 2: Overall framework of Code World Model. The complete vision includes visual feedback; the current prototype focuses on validating the forward path: coding agent / code → world state → proxy → video model.
Proxy: Connecting Executable State to Video Generation
After dividing responsibilities, a key interface problem remains: the coding agent and code maintain an executable state, but the video model receives text, images, or video tokens. A common language is needed that is both easy to construct programmatically and can provide per-frame spatial constraints.
Structured text is flexible but struggles to stably describe per-frame entity positions, relative relationships, motion trajectories, and precise camera changes for each frame; fully constructing and rendering a 3D world offers stronger control but reintroduces the high cost of assets, geometry, materials, animation, and rendering pipelines.
To address this, this work introduces a proxy. It extracts from the world state the information truly needed for the current observation and organizes it into a coarse-grained visual representation. A lightweight, deterministic compiler renders the proxy into a proxy video, which is then fed into the video model along with structured text.
Text is responsible for specifying "who, what, and what to do," while the proxy dictates "where, how to move, and how the camera shoots."
The proxy can express camera and viewpoint, entity positions and orientations, scale and trajectories, scene layout and occlusion, and the coarse-grained state needed for current interactions; texture, materials, detailed lighting, and full local motion are intentionally left to the video model. The paper summarizes this design principle as: retain only the minimally sufficient state required for the current observation, striking a balance between control capability and state encoding cost.
In the current implementation, the proxy's width and height are only one-quarter of the target video's, with approximately 1/16th the pixel count. It is composed of simple, reusable geometric primitives, requiring no production-quality assets, yet it provides a per-frame, editable spatiotemporal skeleton.
Obtaining Strictly Aligned Data from Game Runtime Recordings
For the video model to learn to understand the proxy, training samples need to simultaneously contain proxy video, structured text, and target RGB video, with strict alignment in time, camera, and entity identity between the proxy and RGB.
Game runtime recordings naturally preserve this correspondence. The research team synchronously recorded RGB, camera state, entity identity, position and orientation, approximate scale, scene layout, and interaction state from the same gameplay execution, then compiled the proxy offline via code. Since both originate from the same execution, a one-to-one correspondence can be established for each frame, and identities can be consistently mapped across frames.
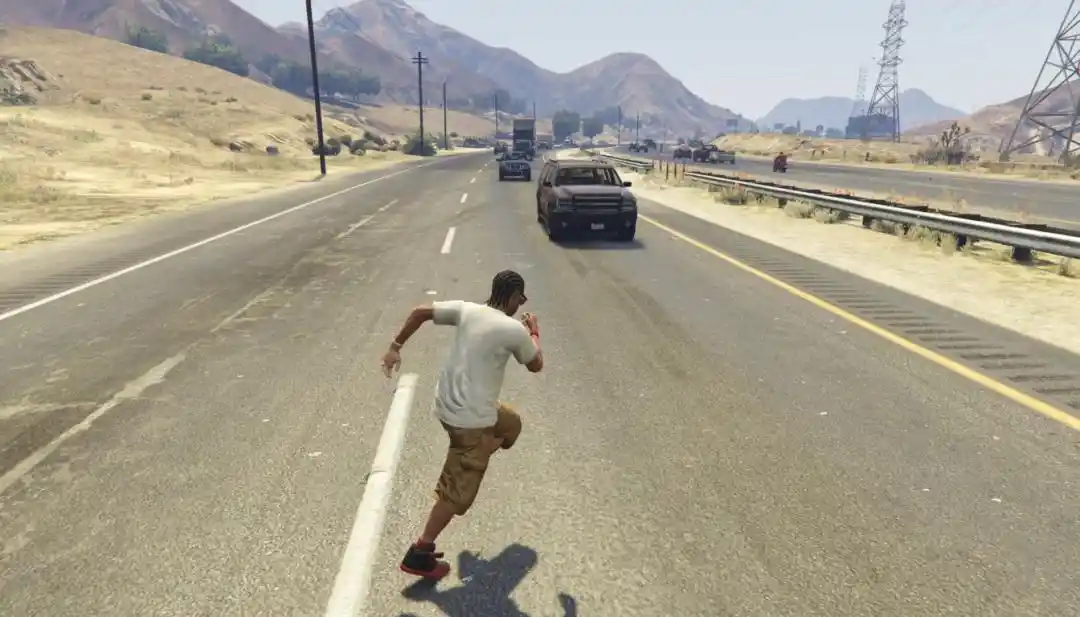
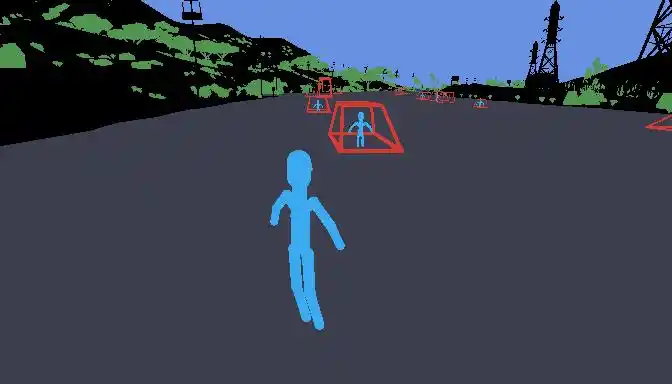
Figure 3a: Target RGB (top) and same-frame proxy (bottom) from game data.
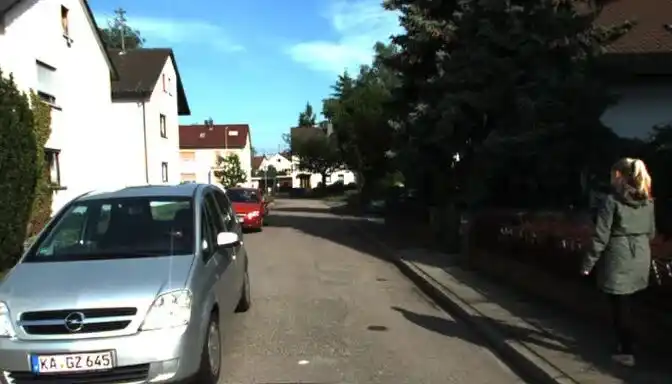
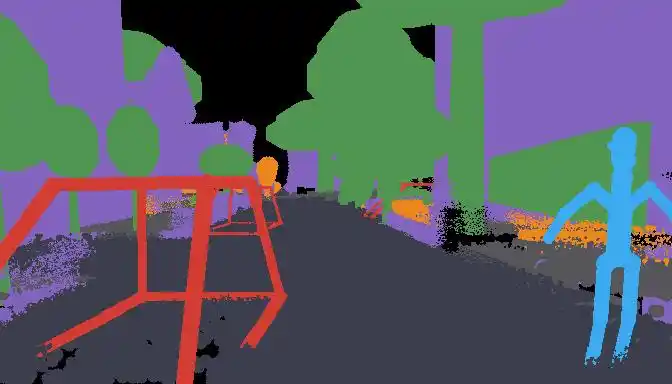
Figure 3b: Target RGB from real video (top), and proxy constructed offline using camera calibration, 3D reconstruction, and object annotation (bottom).
The gameplay data used in the paper comprises 157 recordings, totaling approximately 5.6 hours of source video. The research team sampled at 2-second intervals, obtaining 9,420 training clips of 5 seconds each; each RGB target contains 124 frames at a resolution of 1344×768, 24 FPS. The corresponding proxy also contains 124 frames at a resolution of 336×192, combined with fixed-log depth and categorical semantic-ID maps.
The same runtime recording can be recompiled into proxies with different coverage and information granularity without needing to re-record RGB.
The paper also demonstrates an offline construction pipeline for proxy-observation pairs from real videos using KITTI-360 to illustrate the potential for extending this interface to real data; the current video model adaptation still only uses paired gameplay data.
How Does the Prototype System Operate?
The current prototype uses the Ref2VA backbone of MiniMax-H3 as the video model, applying rank-128 LoRA adaptation to all 50 transformer blocks, with approximately 596 million trainable parameters. Training was conducted on 8 NVIDIA H800 GPUs for 3 epochs and 3,534 optimization steps.
During inference, GPT-5.6 Sol serves as the coding agent. The system provides it with basic player controls, collision handling, runtime update loops, existing game-engine scene and gameplay logic templates, and the proxy primitives used during training. The coding agent can combine, extend, and rewrite this code to construct simple, executable, player-controllable worlds; the coarse-grained 3D geometry is used solely to express the proxy, not as the final visual output.
For each 5-second clip, GPT Image 2 generates an appearance anchor based on the first proxy frame and text; MiniMax-H3 then combines the first frame, the full proxy sequence, and text to generate a 124-frame, 1344×768, 24 FPS RGB video.
Longer videos are generated via a sliding window with a 34-frame overlap: the latter window inherits the RGB context from the end of the previous window and reuses the same appearance anchor to maintain local continuity and overall identity appearance.
Experimental Results
Qualitative results show that even with LoRA adaptation using only about 5.6 hours of gameplay source video, the model can still follow the character positions, action trajectories, scene layouts, and camera movements specified by the proxy, while complementing them with rich textures, lighting, and local dynamics, even when character, environment, and style significantly deviate from the training appearance.
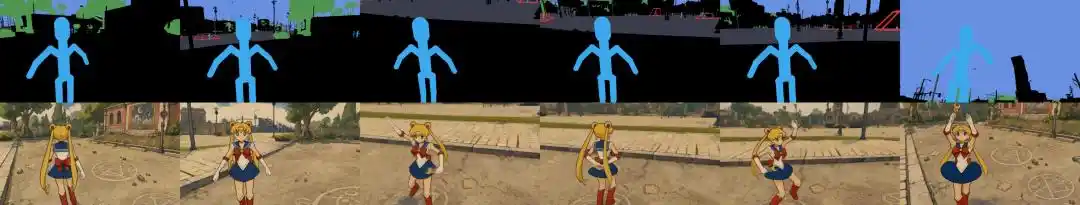
Figure 4: The proxy provides character position and action trajectory; the video model renders the same coarse skeleton into characters of different identities and artistic styles. Top: proxy; Bottom: generation results.
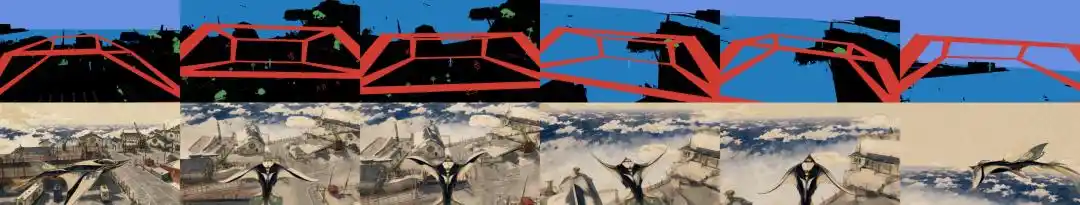
Figure 5: Simple geometric primitives constrain complex objects and camera movements. Top: proxy; Bottom: generation results.
For example, the same coarse human primitive can be rendered as characters with completely different identities and artistic styles; wireframes or boxes can constrain the position and approximate motion of vehicles, boats, and other complex objects; the same proxy interface can also express running, dancing, swimming, falling, and camera orbiting.
This demonstrates that the proxy fixes the necessary spatiotemporal skeleton for the current observation, not the assets and style of the training game.
The project page also provides video comparisons with action- or camera-conditioned video world models.
This comparison focuses on the granularity of control and visual results: the proxy directly provides per-frame entity motion and viewpoint changes, thus enabling finer-grained, more direct spatiotemporal constraints; the paper does not present this set of results as an inference latency comparison.
A netizen commented, "Will Unreal Engine 6 be the last engine to create games using traditional 3D methods? Perhaps Unreal Engine 7 will use a similar technical approach. Only Unreal Engine CEO Tim knows the answer."
Tim then came to view it and said, "I don't know either!"
Conclusion: First Decide What Happens in the World, Then Generate How It Looks
Previous video world models mainly learned "how observations continue." Code World Model pushes the problem a step further: before generating the next segment of observation, first maintain what the world currently is, which rules it follows, and why the consequences of an event persist.
A truly open generative world requires both the visual imagination of video models and an execution mechanism capable of maintaining knowledge, goals, rules, relationships, and causal consequences. The core of Code World Model can be condensed into one sentence: let code decide what happens in the world, and let the video model decide how it all looks.
Reference: https://arxiv.org/abs/2608.25927
This article is from the WeChat public account "New Zhiyuan," author: New Zhiyuan; Editor: LRST