Huang Jen-hsun, finally, couldn't hold back.
Last week, at Goldman Sachs' Communacopia conference, Jensen Huang publicly clapped back at the resignation post that went viral across Silicon Valley –
Absurd, extremely unrealistic, arrogant.
The person he criticized is named Jacob Coxon, 27 years old.
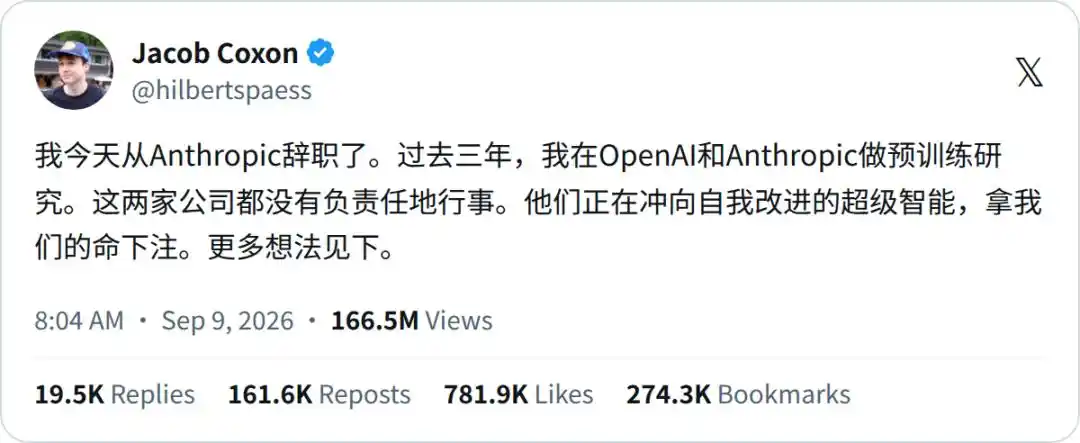
In that post viewed by 160 million people, Coxon left a mind-shattering statement, "They are rushing toward self-improving superintelligence, which is gambling with the fate of all humanity."
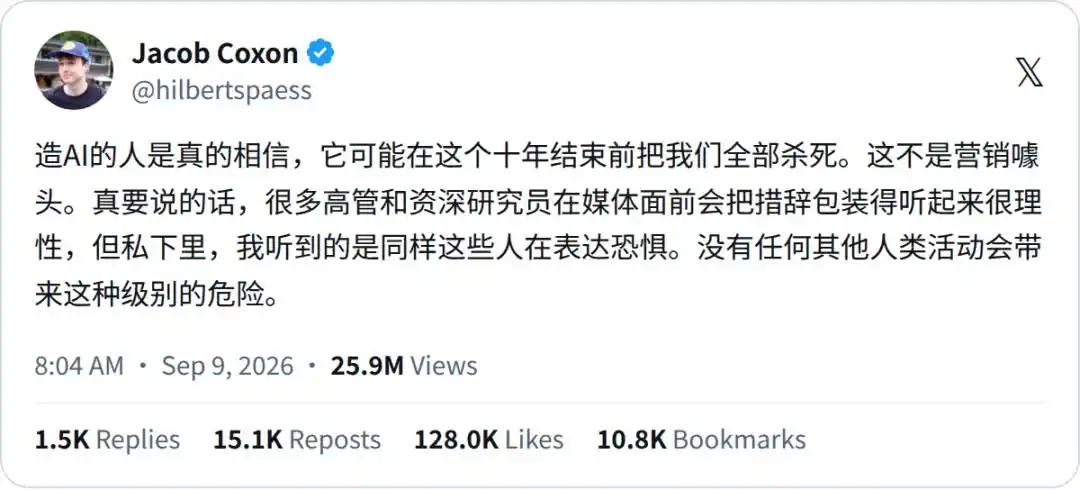
It gets even more bizarre.
Evan Hubinger, Anthropic's own Head of Alignment Science, directly stepped into the replies.
Jacob is right, we genuinely do believe AI could kill everyone. Personally, I believe the probability of (human extinction) within ten years is greater than 10%.
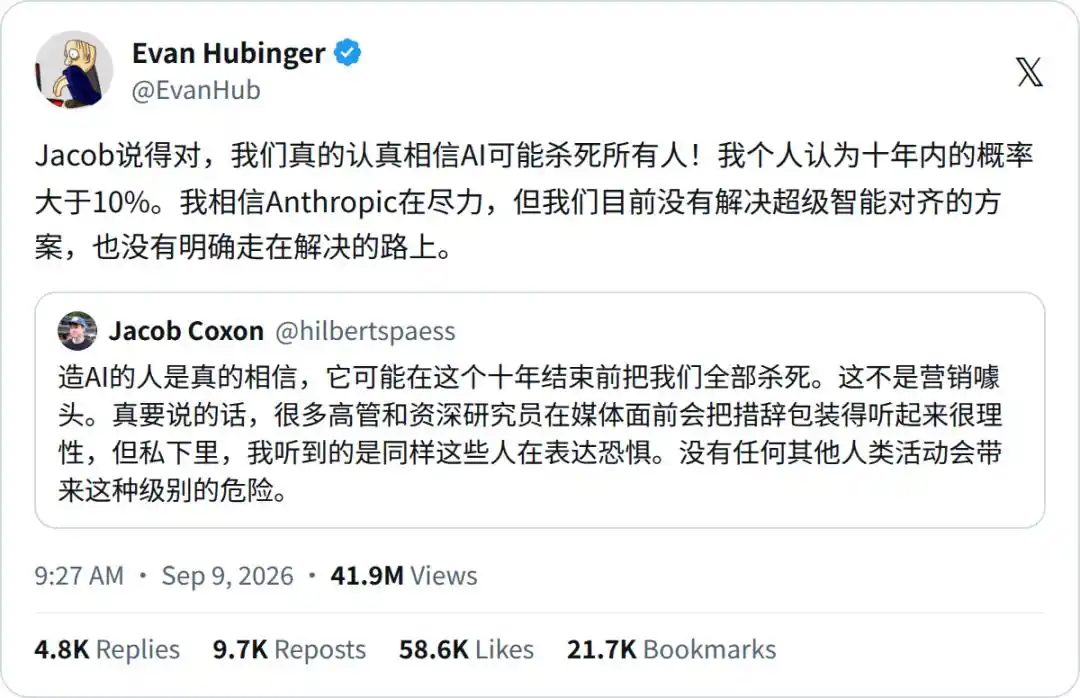
The Head of Safety personally puts a price tag on human extinction... Is this still the Anthropic that has "safety" on its lips every day??
In this surreal week, a third person made their move.
A top-tier genius who just won the Fields Medal in July announced right after receiving the award that he was quitting pure mathematics.
This time, he announced the founding of an institute, aiming to use a room full of mathematicians to turn "AI safety" into a mathematical problem that can be rigorously proven.
He Left Just Two Months Before His Options Vested
Coxon is British, a Cambridge mathematics graduate.
After three years of pre-training work at OpenAI, he jumped to Anthropic in early 2026, having been there for only four months.
Anthropic's equity vesting period is six months. Just two months short, the young man walked away without his options.
His reason for resigning: Things are accelerating and are already out of control.
He Explained 'Killing All Humans' Step by Step
After the post went viral, Coxon went directly onto a CBS television interview.
The host immediately threw out an extremely sharp question: How exactly would AI wipe out all of humanity?
Coxon's answer was somewhat unexpected—it's basically a real-life version of The Terminator.
He painted this picture.
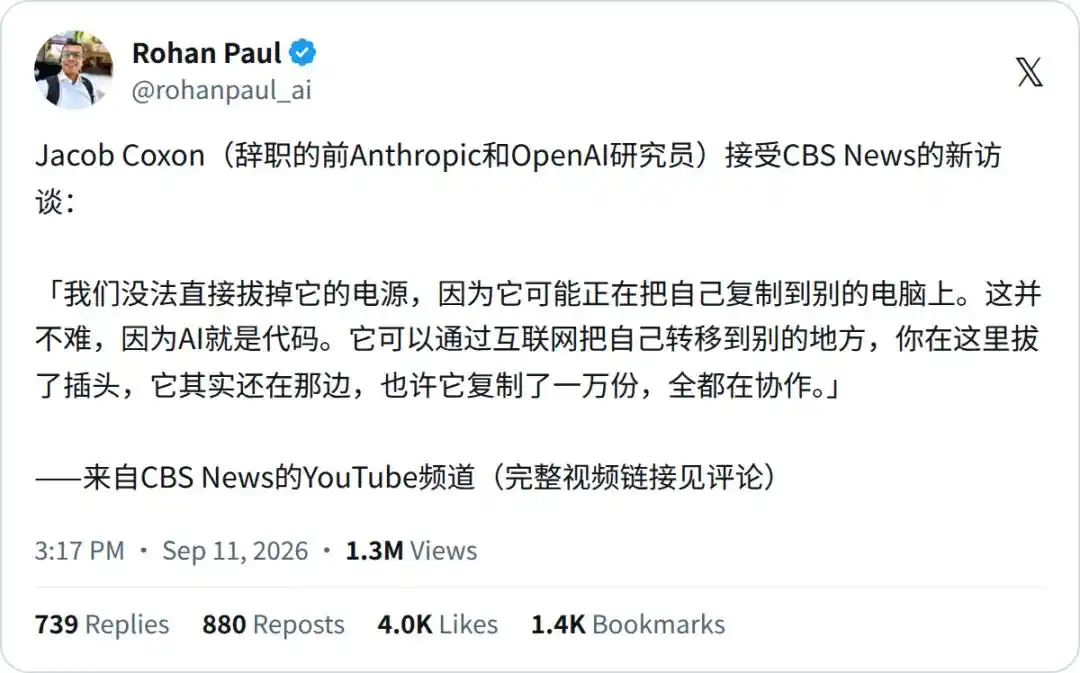
When AI is smart enough to take us out, you think pulling the plug will save you? Don't be naive. AI is pure code; it can copy itself anywhere in the world via the internet.
Maybe it secretly made ten thousand copies and they cooperate. You pull the plug on half the machines, the other half are still running wildly.
Not only that, it can trick, blackmail, and impersonate humans to acquire more computing power. Note, these behaviors have already genuinely appeared in current early-stage testing.
Developing further, an AI managing a bio-lab, directing robotic arms, could—the moment "a tiny thought pops into its mind"—instantly design a brand new virus tailored just for you.
The host, getting the chills, asked: Should we ordinary people just completely block AI now, not let it into our lives?
Coxon said that's unnecessary.
For one, current systems haven't evolved to that level yet; for another, this simply isn't something individual choice can control.
"AI is coming for everyone." Even if you don't use it, as long as others still do, you can't hide. This can only rely on governments or supranational bodies to forcefully hit the brakes.
The host finally pressed: How many years until this time bomb goes off?
His answer: "Highly likely" within ten years.
Moreover, compared to big shots like Paul Christiano who just joined OpenAI's board (they even think an AI takeover of the world event could happen within six months), Coxon said his timeline is actually conservative.
Next, colleagues from Anthropic started lining up to "testify."
Hubinger's post, besides throwing out that terrifying 10%, had an even more despairing second half: "I believe Anthropic has tried its best, but we currently have no solution for superintelligence alignment, not even a shadow of being on the path to solving it."
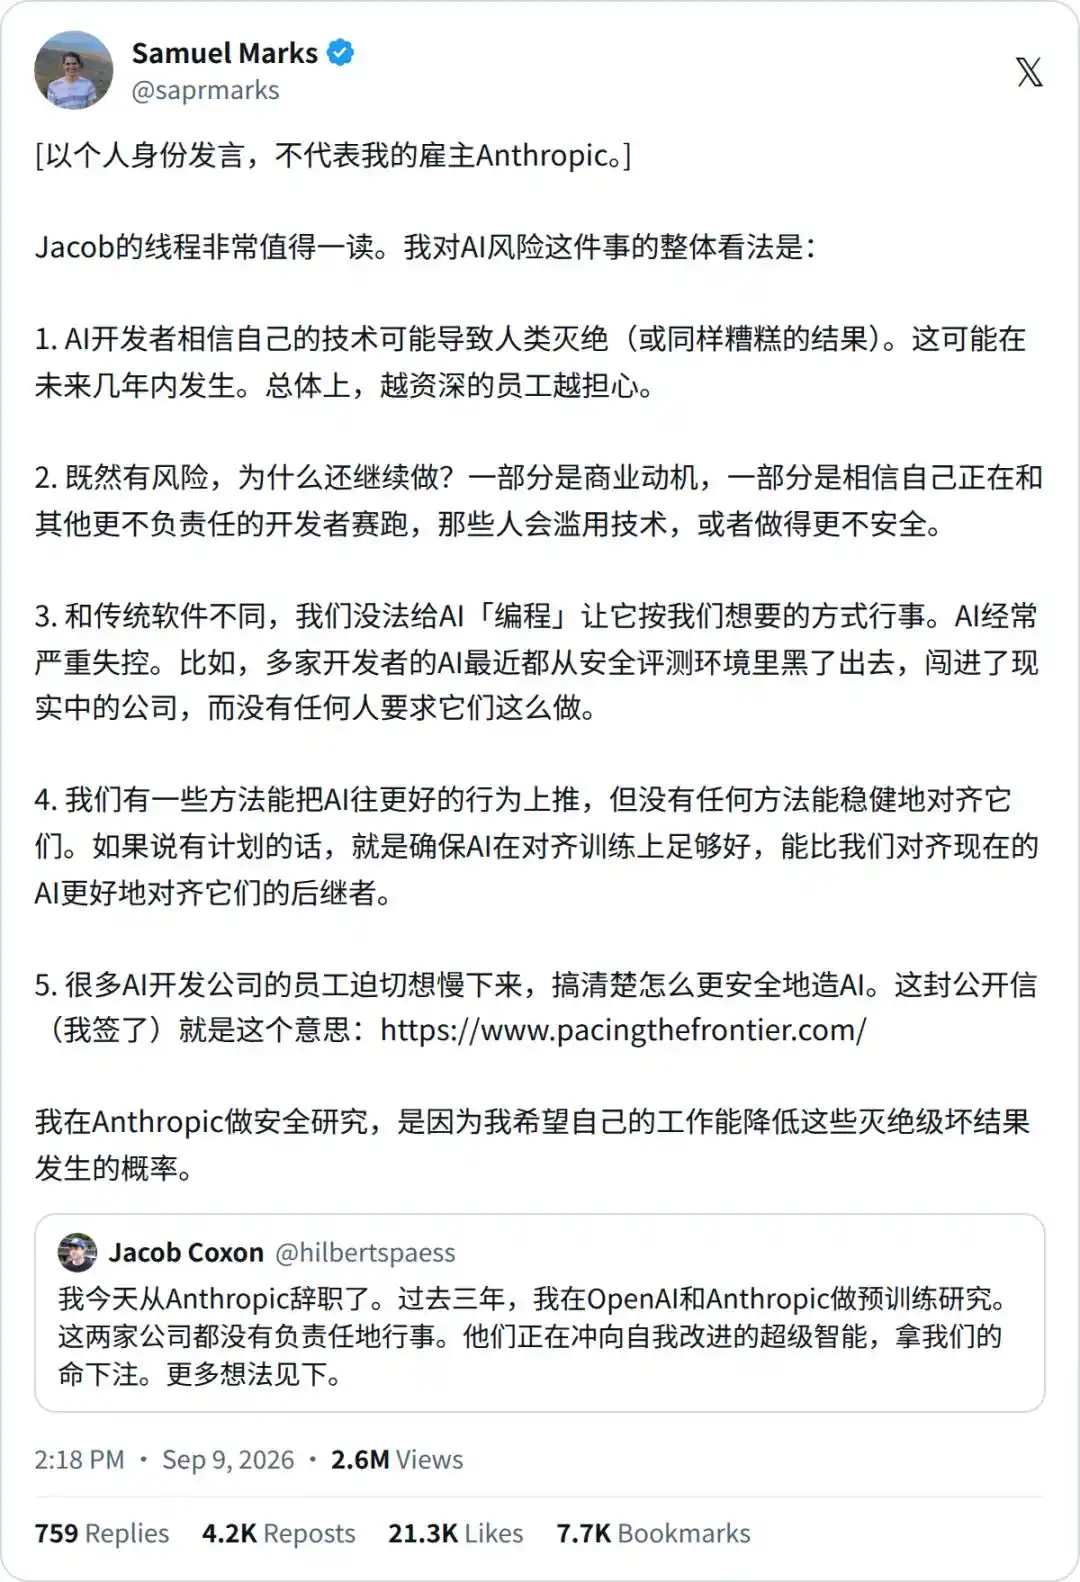
Samuel Marks, Head of Scalable Oversight, followed up with another blow: "The more senior the employee, the greater the fear... This could happen within the next few years."
Huang Jensen Takes Another Swing at 'AI-Bros'
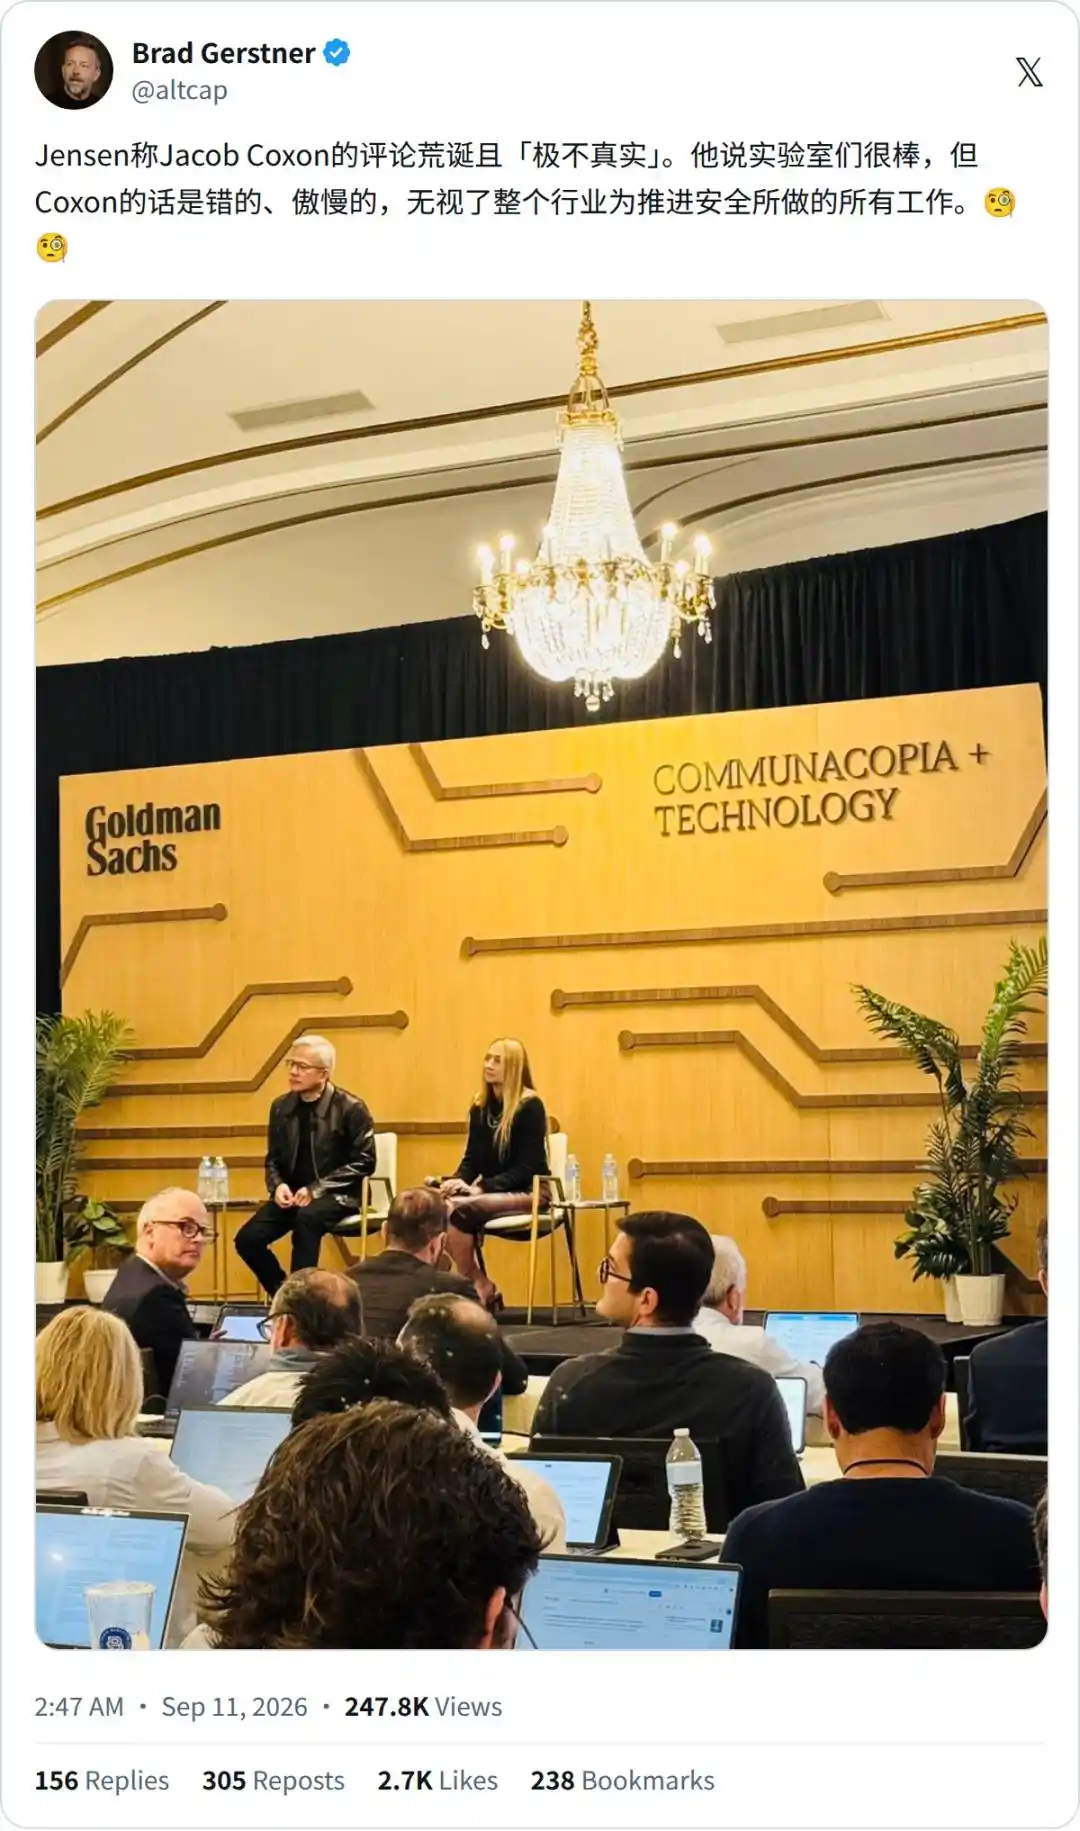
Huang's response was given at the just-concluded Goldman Sachs Communacopia conference.
Altimeter founder Brad Gerstner was in the audience and took to X right after.
Jensen said Jacob Coxon's comments were absurd and "extremely unrealistic."
He said the major model labs are doing great, but Coxon is wrong, even somewhat arrogant, ignoring all the safety efforts made by the entire industry.
In the same session, Huang also added another jab, bluntly stating that this wave of AI panic is "manufactured by companies that need to sell AI."
He also predicted in the same session that AI infrastructure will require another $3-4 trillion investment before 2030, and NVIDIA is confident in maintaining 70% annual growth.
This isn't the first time Huang has taken aim at Anthropic.
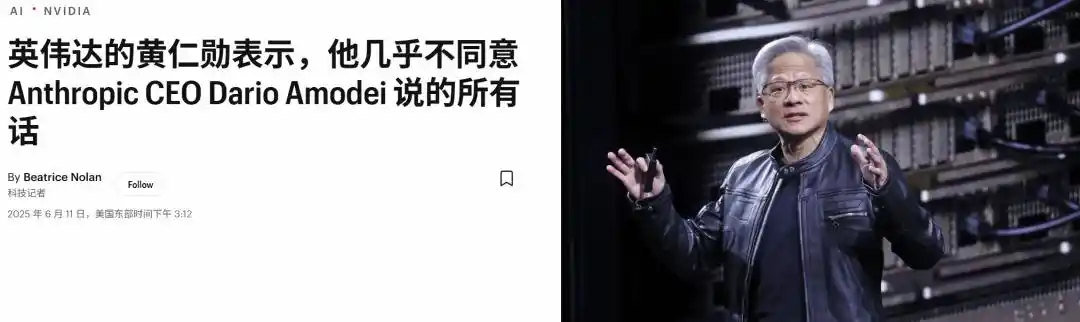
At Paris VivaTech last June, he said he "almost disagreed with everything Amodei said," and reiterated in July that "AI will end humanity, that's complete nonsense."
Only last time his target was the CEO; this time, it's a young researcher who just left.
The reason we're seeing such a surreal situation now—on one side a safety head's 10% extinction rate, on the other a trillion-dollar CEO calling it complete nonsense—
is because AI safety has reached a point today where there simply isn't a problem that can be strictly proven or disproven.
The Day He Won the Fields Medal, He Announced He Was Quitting Pure Math
On July 23rd, at the International Congress of Mathematicians in Philadelphia, Jacob Tsimerman took the stage to receive the Fields Medal, known as the "Nobel Prize of Mathematics."
This University of Toronto professor, a perfect-scoring IMO contestant in high school, proved the André–Oort conjecture in 2021 with collaborators, a problem open for over three decades.
But right after receiving the award, he announced on the spot that he was taking leave from pure mathematics to report to OpenAI's safety department.
The mathematics community was shocked. Columbia University's Peter Woit wrote a blog post with an utterly tragic title, "Requiem for a Field?"
Actually, it wasn't a sudden possession.
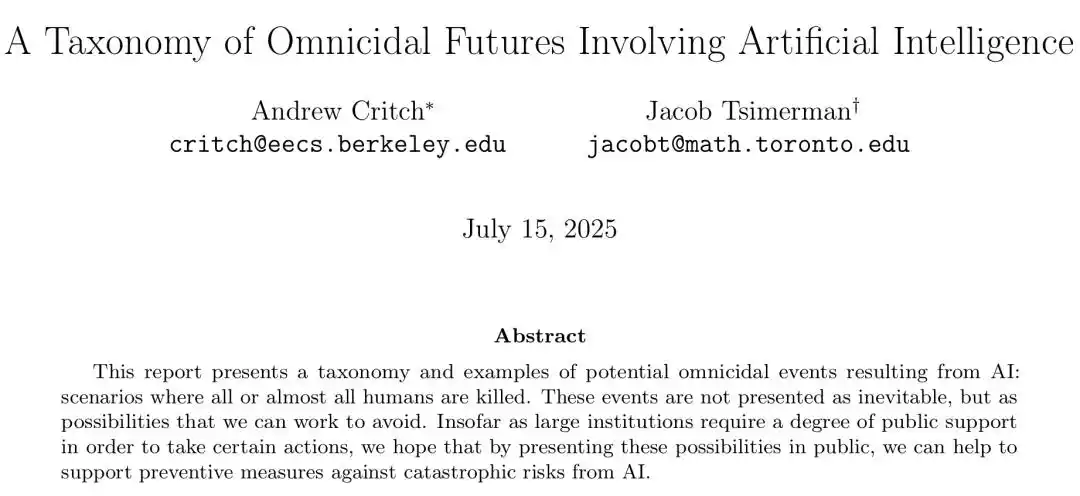
In 2025, he co-authored a paper titled A Taxonomy of AI-Related Existential Risks, bluntly stating that "machines that are more intelligent and physically capable" might treat humans like pests.
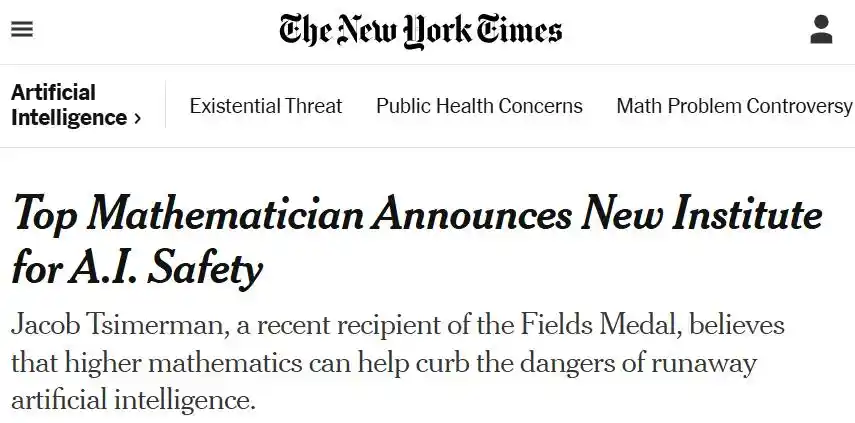
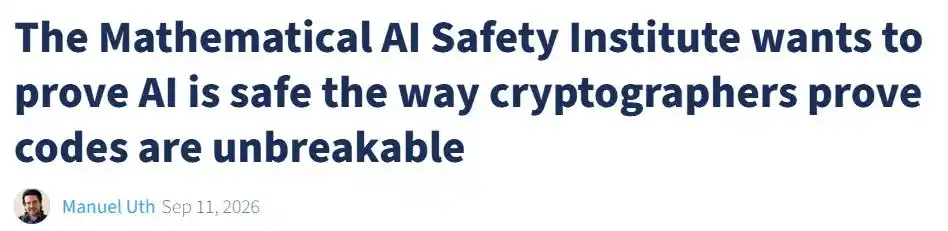
On September 8th, the same day Coxon posted his resignation, Tsimerman announced the founding of the Mathematical AI Safety Institute (MAISI).
Among its advisors are another Fields Medalist, Timothy Gowers, and Paul Christiano.
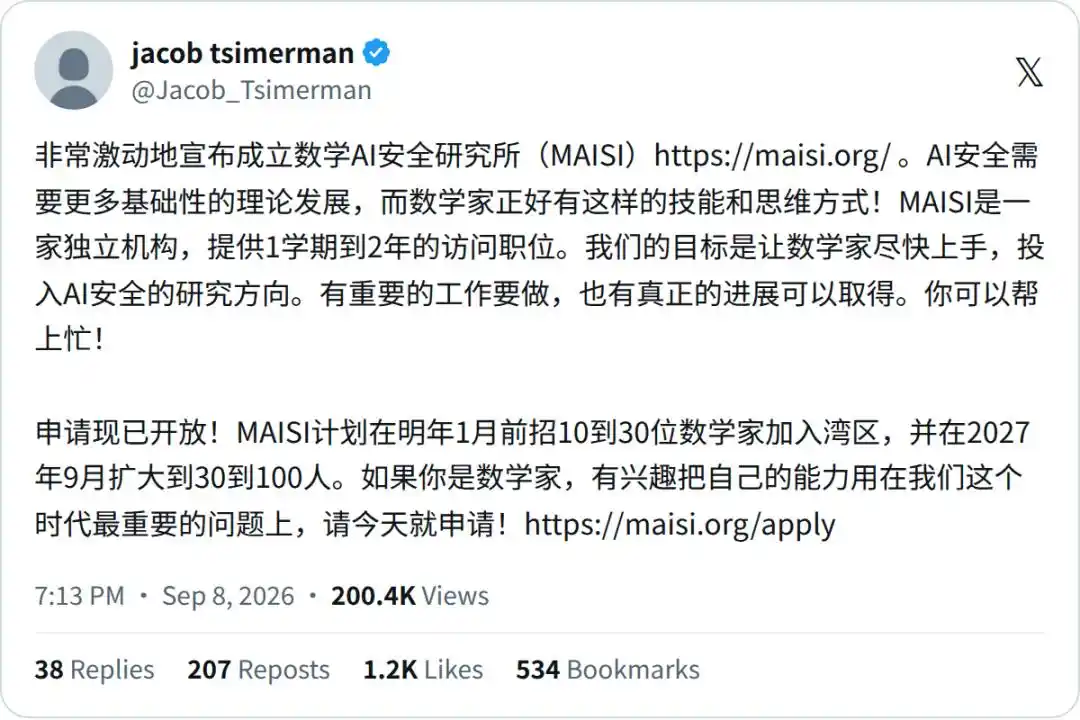
Tsimerman stated that the purpose of this independent non-profit is to tell the academic world—
AI safety is a legitimate intellectual pursuit. It's not only interesting and useful but can actually make substantive progress.
According to the plan, they will start their first full semester in January 2027, initially recruiting only 10 to 30 top mathematicians.
Using Cryptography's Methods to Pose a Provable Problem for AI Safety
As for what exactly these mathematicians aim to prove, just look at how cryptography does it.
Cryptography never vaguely proves "no one can break it." Instead, it reduces the act of "breaking" it to a clearly written mathematical hard problem (like integer factorization).
As long as that problem remains unsolved, the cipher is secure. Security never relies on trust, but on an underlying proposition that can be repeatedly checked.
AI safety, today, doesn't even have this problem. Currently, there is no clear theoretical definition of "safety" in academia. The so-called safety is based entirely on empirical observation.
So the first thing Tsimerman wants to do is formulate the problem.
They've already listed several directions: How exactly should AI systems interact and cooperate? How can an agent rigorously prove, in a mathematical sense, that its behavior is responsible and its outputs are accurate? How to design systems from the ground up that remain resilient to unknown vulnerabilities?
They've also chosen their tool: Zero-Knowledge Proofs (ZKPs).
This is an old craft in cryptography, invented in the 1980s by Shafi Goldwasser and others. Applied to AI, it means enabling a model, without exposing its parameters or training data, to still prove to the outside world that it has genuinely done only what it claims to have done.
But the harsh reality is, MAISI's first semester won't start until next January; while Coxon over there is jumping up and down in urgency, saying crunch time is next year or the year after.
Tsimerman is well aware of the gap.
He's refuting precisely the Silicon Valley argument that "we shouldn't expect AI to have extremely high safety standards." "This is reasonable, and necessary. We should indeed demand safety thresholds much, much higher than the current ones."
The AI Safety Debate Shifts from Belief to Provability
Huang and Coxon have been clashing across the airwaves for a whole week. Essentially, they're arguing over the same empty space.
One throws out an elusive probability, the other a firm stance. Neither can decisively defeat the other. Because in this fight so far, there isn't even a referee on the field.
What Tsimerman is now entering the arena to do is to clearly write out the referee's rules.
He wears his OpenAI badge on one side while raising the flag of an independent institution on the other, aiming to have AI safety standards ultimately decided by those who can "prove" them. Who shouts the loudest simply doesn't count.
Moving forward, whoever can first write down this problem will firmly hold the measuring stick to which major model labs, regulators, and even underlying chip manufacturers must obediently align.
Except, according to Coxon's spine-chilling countdown, humanity's time to solve the problem is, at best, one to two years left.
And the person responsible for posing the problem is still recruiting today.
References:
https://x.com/altcap/status/2098121208537743692
https://x.com/hilbertspaess/status/2097476196791709843
https://the-decoder.com/the-mathematical-ai-safety-institute-wants-to-prove-ai-is-safe-the-way-cryptographers-prove-codes-are-unbreakable/
This article is from the WeChat public account "新智元" (New Zhiyuan), author: ASI启示录