DeepSeek's "Jekyll and Hyde" duality has been caught by ByteDance's Seed team.
The same problem, with nothing changed but a few irrelevant characters added in front, and the model suddenly fails???
And it's not just an occasional hiccup.
Seed researchers found that DeepSeek-V4's performance actually changes periodically every 4 tokens depending on the input position of the information.
What does this mean? Whether the model remembers something actually depends on *where* that information is located in the input??
Add two tokens in front, the answer might change from wrong to right; add two more, it flips back again.
Great, now models need to worry about positioning too.
In 128K long-context retrieval tests, researchers found that simply moving the same piece of information to a different position could cause the retrieval accuracy of DeepSeek-V4 series models to differ by up to 40.2 percentage points.
The team further discovered this issue is related to a long-context optimization technique adopted by DeepSeek-V4—
Chunked KV Cache Compression.
This technology was originally intended to make the model more memory-efficient and faster when processing long text.
But after compression, it ended up making the model perform inconsistently (doge).
With Two Extra Tokens, DeepSeek Suddenly Gets It Right
The ByteDance Seed researchers initially experimented with DeepSeek's own code.
The test subject was DeepSeek-V4-Flash-Base.
They took a snippet of FP8 quantization function from DeepSeek-V4's official inference code and asked the model to complete the last token.
The correct answer should be 8, as this code segment needed to complete a type conversion related to FP8.
But sometimes the model insisted it should be 32.
To figure out what was going on, the researchers added a purely decorative docstring in front of the code, containing some repeated equal signs.
Then, they started adjusting the number of equal signs.
The code itself wasn't changed, the position to be completed wasn't changed, the correct answer certainly wasn't changed... the only variation was the few meaningless tokens added in front.
The result? DeepSeek's answer started flipping back and forth.
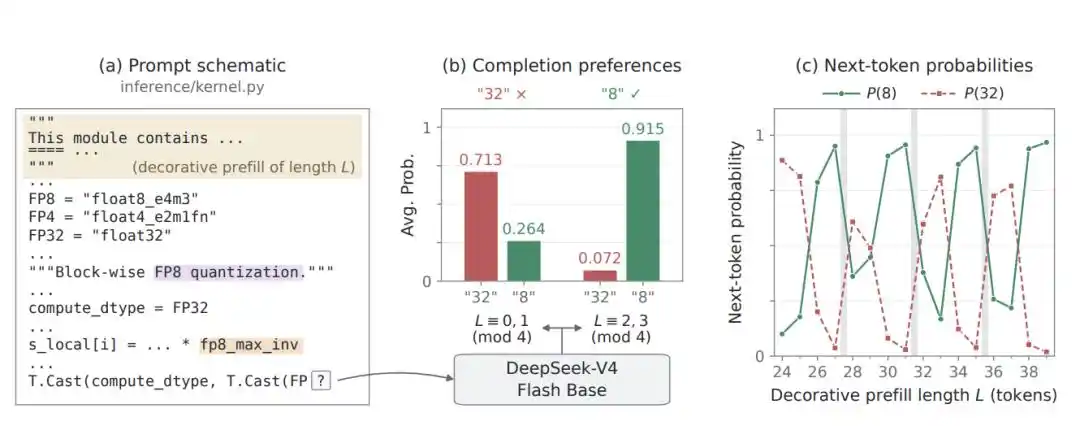
When the padding length fell at certain positions, the model was more inclined to answer incorrectly with 32.
Move forward one or two tokens, it started leaning towards the correct answer, 8.
Continue moving, and the wrong answer came back—
The entire process repeated with a period of 4 tokens.
More specifically, among the 16 padding lengths tested in the paper, when the length modulo 4 had a remainder of 0 or 1, the model favored the wrong answer 32; with a remainder of 2 or 3, it favored the correct answer 8.
The researchers also tallied the probabilities the model assigned to the two candidate answers.
At one set of positions, the average probability for the wrong answer 32 reached 71.3%, while the correct answer 8 only got 26.4%.
Switch to another set of positions, and the situation directly reversed:
The average probability for the correct answer 8 rose to 91.5%, leaving the wrong answer 32 with only 7.2%.
In other words, a change in the length of a few irrelevant characters in front was enough to make the model produce completely different judgments for the same problem.
This is a bit hard to assess.
When debugging code, programmers usually check logic, variables, and dependencies first.
Now it seems they might also need to check if they typed two extra equal signs in front.
However, a single code completion case isn't enough to show how widespread the problem is.
So the Seed team expanded their testing.
They turned their attention to a classic task in large language model long-context capabilities: Needle-in-a-Haystack.
The researchers constructed a 128K-token-long context containing approximately 16,000 key-value pairs.
For example, K1 corresponds to V1, K2 to V2...
Then they asked the model to find the Value corresponding to a specified Key.
During testing, the key-value relationships remained unchanged, the questions were the same, and the total context length was consistent.
The researchers focused on adjusting the position of the target information relative to the compression window boundaries.
They found that the accuracy curve of the DeepSeek-V4 series actually showed very明显的明显的 (obvious) periodic起伏 (fluctuations).
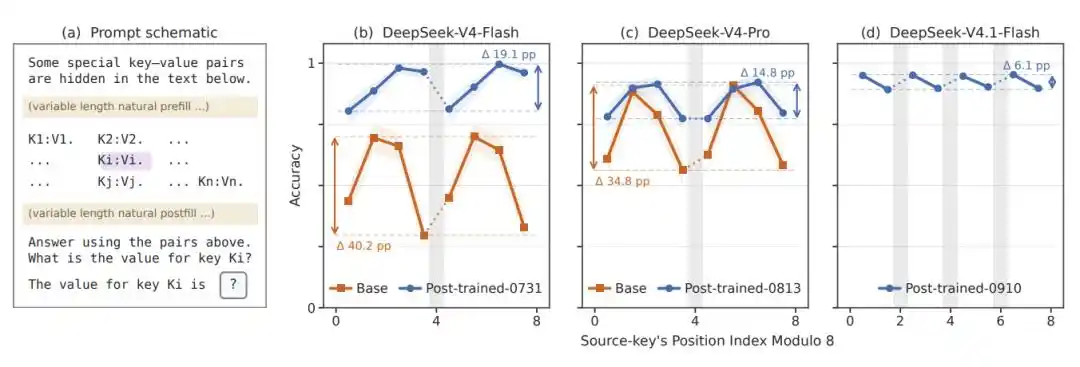
Among them, DeepSeek-V4-Flash-Base showed a maximum accuracy gap of 40.2 percentage points between different positions.
DeepSeek-V4-Pro-Base also reached 34.8 percentage points.
After post-training, the situation improved somewhat.
The gap for DeepSeek-V4-Flash-0731 narrowed to 19.1 percentage points, and DeepSeek-V4-Pro-0813 narrowed to 14.8 percentage points.
The newer DeepSeek-V4.1-Flash-0910 further reduced the gap to 6.1 percentage points.
But periodic differences still exist.
How did this disparity arise?
Looking closer, DeepSeek-V4's fluctuation period is 4 tokens, while DeepSeek-V4.1's changed to 2 tokens.
The researchers found this corresponds exactly to the KV Cache compression stride used by each generation of the model.
Well then, even the fluctuation period of answer performance matches the underlying compression configuration.
The Problem Lies in KV Cache Compression?
Let's talk about KV Cache compression then.
When large models process long contexts, they need to store Key and Value information corresponding to a large number of historical tokens for subsequent attention calculations.
The longer the context, the more memory and computational overhead this cache occupies.
Especially for long tasks involving tens or hundreds of thousands of tokens, KV Cache can easily become a bottleneck for inference efficiency.
Therefore, DeepSeek-V4 adopted Chunked KV Cache Compression.
The idea is to divide consecutive tokens into windows and then compress the information within each window into fewer cache entries.
This way, the model doesn't need to preserve cache of the same scale for every historical token.
It saves memory and reduces the cost of long-context attention calculations.
But the Seed team discovered that the reason for DeepSeek's "Jekyll and Hyde" performance might be hidden in this chunking process.
Suppose every 4 tokens form one compression stride.
Then, if the same piece of information appears at the 1st, 2nd, 3rd, or 4th position within the window, the conditions during compression might differ.
The paper calls this position relative to the compression window boundary the Phase.
Researchers found systematic differences in the model's retrieval ability for information in different phases.
They named this phenomenon Phase Sensitivity.
To give an analogy, giving the same document to the model:
In the first layout, the key number happens to land in a position the model finds easy to retain;
In the second layout, just a few extra words are added in front, changing the key number's position relative to the compression window.
The document is still the same document, but whether the model can later find the number might show a significant difference.
Moreover, this problem can't be simply attributed to "the information happened to be split between two windows."
Researchers found that even when both the Key and Value fall within the same compression window, retrieval accuracy can still vary greatly depending on their specific positions.
This indicates the issue also involves how the model writes information into the compressed cache and how it reads from it later.
To confirm further, the Seed team simply trained a batch of models from scratch.
Using the Qwen3-0.6B architecture as a base, they constructed various KV Cache compression schemes and set up a full-attention model without chunked compression as a control.
The focus was only on changing the compression mechanism to see if periodic fluctuations would appear accordingly.
The result: All chunked compression models tested exhibited periodic changes corresponding to their compression stride.
Conversely, the full-attention baseline model did not show the same level of periodicity.
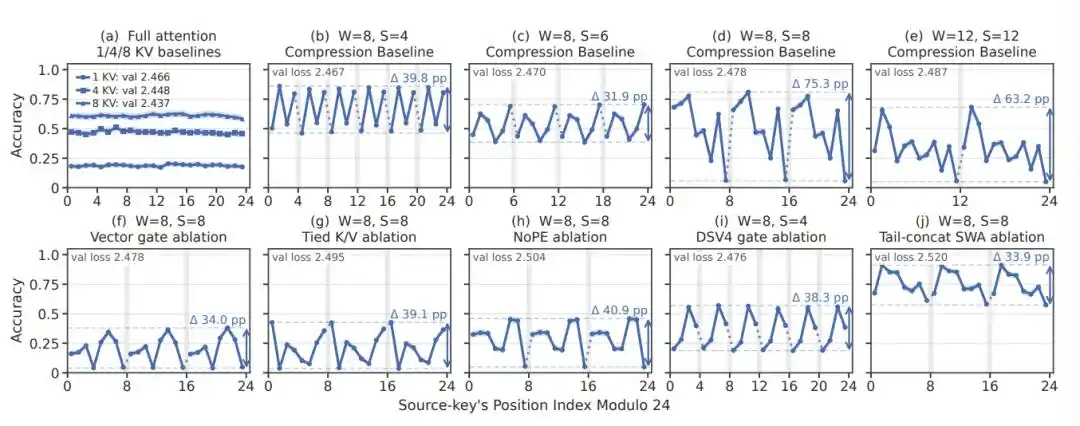
The researchers also separately adjusted window size and compression stride, finding that the period mainly changed with the compression stride.
Stride of 4, performance fluctuated with a period of about 4 tokens;
Stride of 6, the period also became about 6 tokens;
Stride of 8, same thing;
...
Even without using RoPE position encoding, or replacing learnable compression weights with simple averaging, this phenomenon persisted.
In other words, the problem isn't caused solely by a particular position encoding or a special module.
The design of chunked compression itself may introduce periodic retrieval weaknesses.
The Seed team further intervened on attention heads, observing how the model's retrieval ability across different phases changed after removing different components.
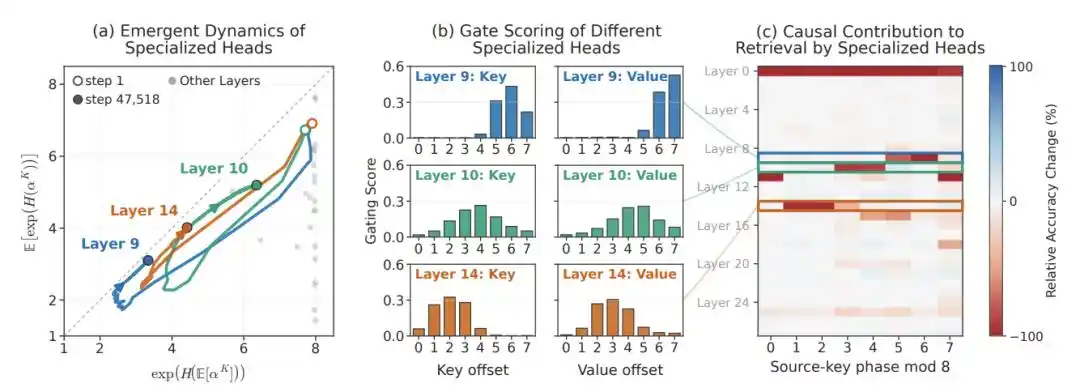
They found that different attention heads contributed differently to different phases.
Some heads were better at processing information at certain positions, while others played a larger role at other positions.
The researchers termed this Phase Specialization.
That is, the model's internals seem to have formed a division of labor: different attention components developed preferences for different positions within the compression window.
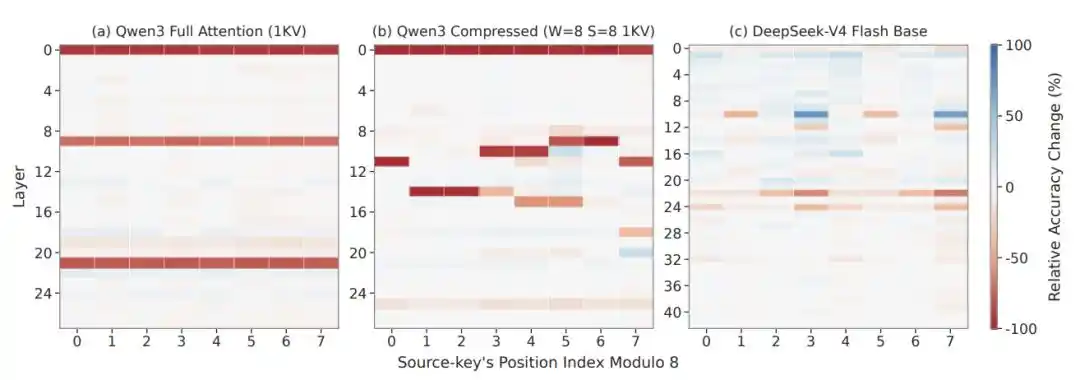
This division of labor can help the model perform information retrieval, but it may also make certain positions relatively weak links.
The paper also analyzed the training process using a simplified theoretical model, finding that gradient flow might drive compression modules to form stable positional preferences.
This also explains why this periodicity isn't simple random noise. It might be a natural outcome of the model learning how to compress information.
But such problems might not be directly visible from ordinary benchmarks because conventional evaluations usually aggregate a large number of test results into a single average score.
Suppose the model performs very well at some positions but significantly worse at others; the final calculated average score might still look good.
Therefore, the Seed team suggests that when evaluating models using chunked KV Cache compression, one shouldn't just look at overall retrieval accuracy but also test the same piece of information placed at different compression phases separately.
Even though this position-dependent performance bias exists, the memory and computational costs of long-context reasoning are still there, making compression valuable for practical reasons.
But after saving on cache, the model might no longer treat information from different positions equally.
Of course, judging from this experiment's results, post-training and architectural iterations can indeed significantly narrow this gap.
Paper address: https://arxiv.org/pdf/2609.36322
This article is from the WeChat public account "QbitAI", author: Wen Le